
 Script Planner Assistant▸
 AI Apps
 AI News

IndexTTS: A Text-to-Speech Model Developed by Bilibili Based on XTTS and Tortoise
IndexTTS: A Text-to-Speech Model Developed by Bilibili Based on XTTS and TortoiseIntroduction
IndexTTS is a text-to-speech model developed by Bilibili based on XTTS and Tortoise, delivering industrial-grade zero-shot TTS capabilities. It innovatively employs a character-pinyin hybrid modeling approach tailored for Chinese scenarios, enabling quick correction of pronunciation errors. Combined with a Conformer conditional encoder and BigVGAN2 decoder, it enhances training stability, timbre fidelity, and output audio quality.
Core Features:
✅ Supports both Chinese and English
✅ Chinese Pinyin Correction: Input pinyin to adjust the pronunciation of polyphonic characters (e.g., for "长" you can specify "zhǎng" or "cháng")
✅ Punctuation-Based Pause Control: Control speech pause rhythm through punctuation marks
✅ Audio Quality Enhancement: Conformer encoder extracts timbre features, while the BigVGAN2 decoder improves waveform generation quality
✅ Emotion Disentanglement Control: Independently adjust emotional expression and speaker timbre
✅ Precise Duration Control: Supports both token-count specification and autoregressive generation modes
Technical Highlights:
✅ Chinese Hybrid Modeling: The input layer supports both pure text and pinyin hybrid input, automatically predicting unlabeled pinyin and reducing word error rates
✅ Conformer Encoder: Fuses convolution and self-attention mechanisms to strengthen timbre and prosody modeling
✅ BigVGAN2 Decoder: A GAN-based waveform generator that balances computational efficiency with audio quality
Key Advantages:
✓ Accurate pronunciation of polyphonic characters
✓ Natural pause rhythm
✓ High-fidelity audio quality
✓ Fast voice cloning
✓ Chinese-English bilingual support
Typical Applications:
IndexTTS synthesizes speech with natural and emotionally rich expression, closely resembling real human voices. It is widely applicable to scenarios such as intelligent assistants | audiobooks | videodubbing | intelligent customer service | educational tools.
Performance
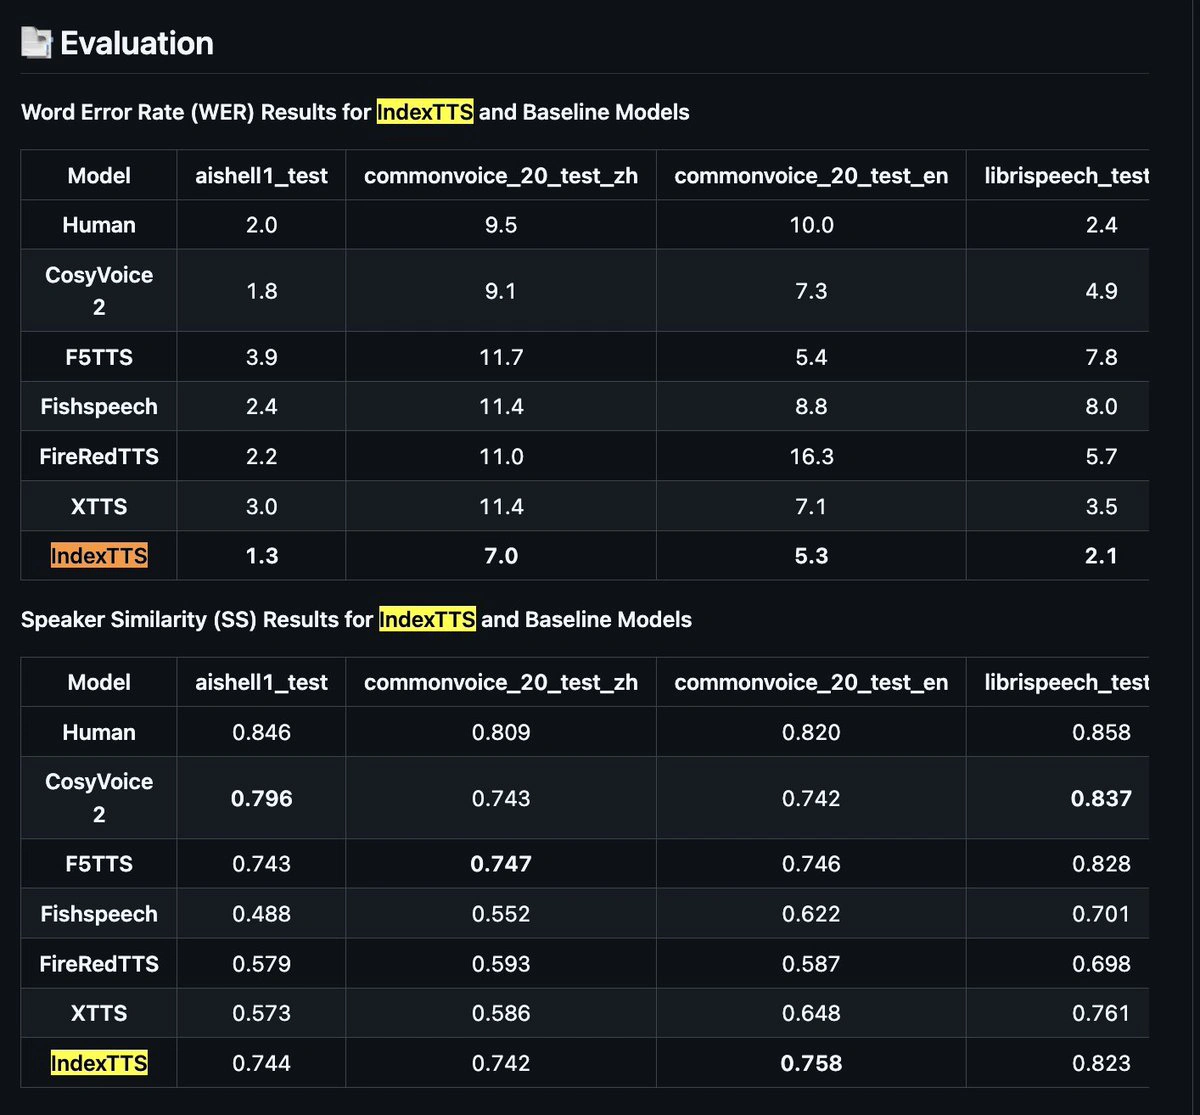
✓ Naturalness and Consistency: In terms of naturalness, content consistency, and zero-shot voice cloning, IndexTTS shows significant improvements over existing models such as XTTS.
✓ Training and Inference Efficiency: The training process is relatively simple, with faster inference speed, outperforming mainstream open-source TTS systems such as Fish-Speech, CosyVoice2, FireRedTTS, and F5-TTS.
✓ Codebook Utilization: Compared to Vector Quantization (VQ) and Finite Scalar Quantization (FSQ), it solves the codebook collapse problem, achieving a codebook utilization rate close to 100%.
Deployment:
Clone the GitHub repository
Install dependencies such as PyTorch
Prepare and preprocess audio data
Train or load a pre-trained model
Tune parameters and generate audio files
Project Address:https://github.com/index-tts/index-tts














