
 Script Planner Assistant▸
 AI Apps
 AI News
StoryDiffusion: Generate Consistent Images, Videos & Comics
StoryDiffusion: Generate Consistent Images, Videos & ComicsIntroduction
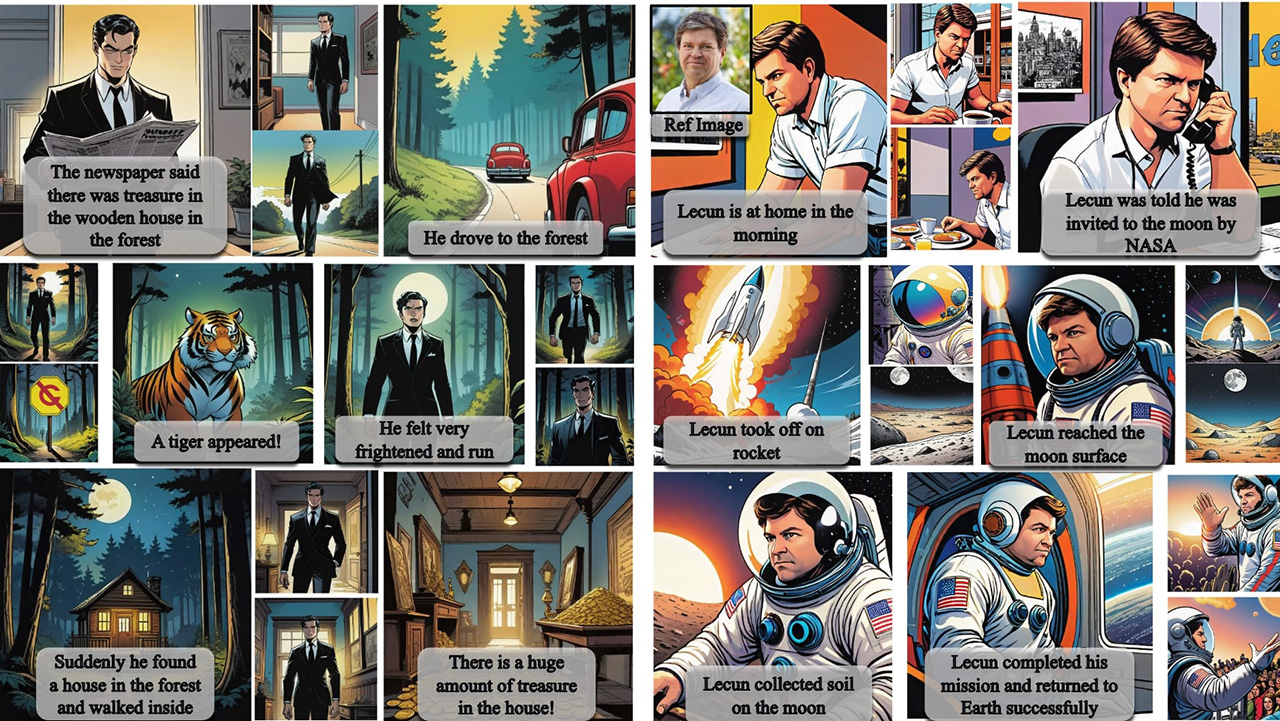
StoryDiffusion is an artificial intelligence tool developed by the HVision team at Nankai University. Its main functions include generating coherent image and video stories, as well as comic generation and creation. StoryDiffusion leverages Consistent Self-Attention technology to generate theme-consistent images without the need for training, which can be used to tell stories or serve as input for subsequent content generation.
StoryDiffusion is capable of maintaining character consistency and generating multi-image comics and long videos, which is especially important for fields such as advertising and film that require coherent narratives.
Key Features of StoryDiffusion:
Character Consistency Preservation: StoryDiffusion is able to generate theme-consistent images and videos through the consistent self-attention mechanism, ensuring the consistency of character style and clothing across multi-image comics and long videos, thereby achieving coherent storytelling.
Multi-Scenario Application: This tool is not only suitable for comic generation, but can also be applied to various scenarios such as image-to-video. Users can generate videos by providing a series of conditional images and utilizing the Image-to-Video model, which provides new creative approaches and production methods for fields such as advertising and film.
Educational Material Design: Educators can use StoryDiffusion to design educational videos or interactive stories, which help increase learner engagement and interest.
Long-Range Image Generation: Particularly suitable for creating coherent advertising stories and enhancing brand image. This capability gives StoryDiffusion a significant advantage in advertising and brand promotion.
Plug-and-Play Without Training: The research team inserted the consistent self-attention into the U-Net architecture of existing image generation models and reused the original self-attention weights to maintain the training-free and plug-and-play characteristics.
High Efficiency and Robustness: While preserving character features, StoryDiffusion also aligns well with prompt descriptions, demonstrating its robustness. This indicates that the method achieves the best performance on quantitative metrics.
Through the consistent self-attention mechanism, StoryDiffusion is not only capable of generating coherent images and videos, but can also be applied to a variety of practical scenarios such as education, advertising, and entertainment, while delivering high efficiency and robustness.
GitHub Project: The related project has gained 1k stars on GitHub, with the GitHub address at: https://github.com/HVision-NKU/StoryDiffusion.
Paper and Demo: More technical details and experimental results about StoryDiffusion can be found in the paper "StoryDiffusion: Consistent Self-Attention for long-range image and video generation", available at: https://arxiv.org/pdf/2405.01434v1














