
 Script Planner Assistant▸
 AI Apps
 AI News
PixelDance: ByteDance's Video Generation Model
PixelDance: ByteDance's Video Generation ModelIntroduction
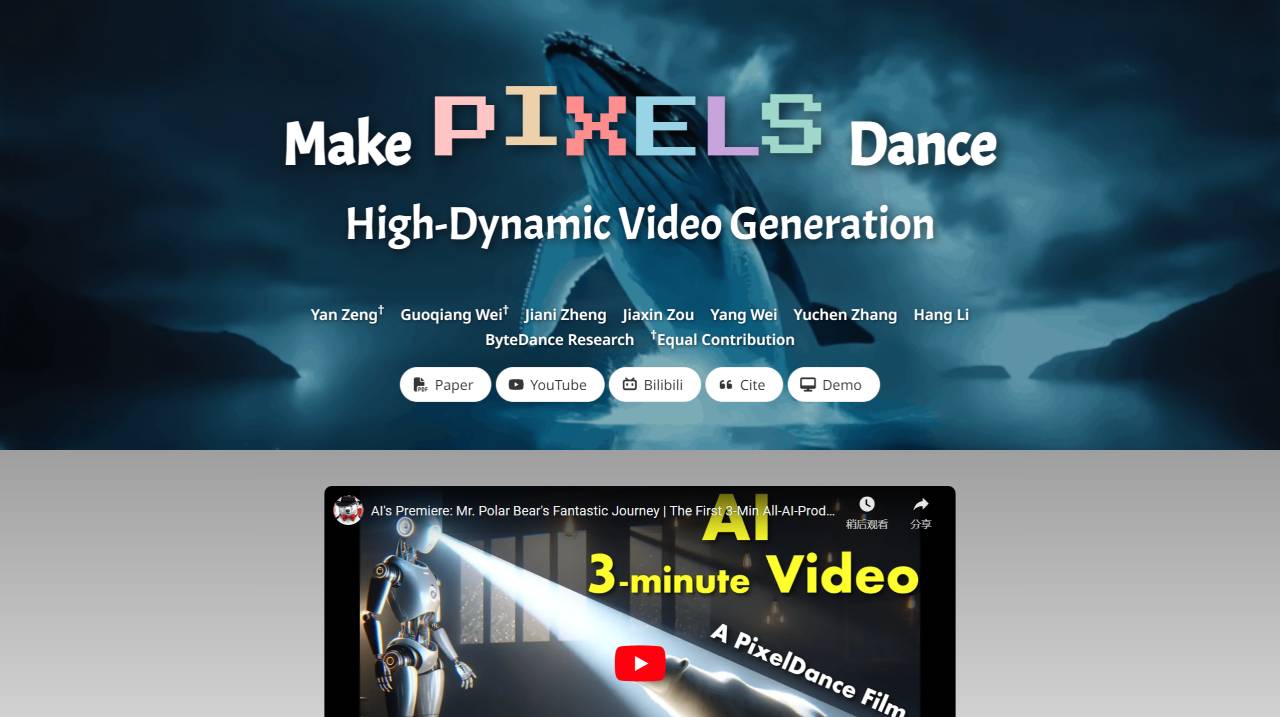
PixelDance is a video generation model developed by ByteDance. By combining textual guidance with first-frame and last-frame image guidance, it is capable of generating videos with complex scenes and motions. What makes this technology novel is that it relies not only on text instructions but also incorporates image instructions, making video generation more efficient and dynamic.
PixelDance leverages diffusion models, an advanced machine learning technique used to process image and video data, thereby enabling high-dynamic-range video generation.
In addition, PixelDance is designed to easily render complex actions and stunning visual effects, thanks to its innovative technical approach and meticulous attention to detail. Its emergence marks a major breakthrough in the field of video generation, as it not only enhances video dynamics but also enables the creation of videos rich in motion without requiring domain-specific inputs.
Technical Features of PixelDance:
Feature Space and Motion Diversity: PixelDance has a significantly larger feature space and stronger motion diversity, enabling it to excel at handling complex actions and stunning visual effects.
Performance Improvement: On the MSR-VTT and UCF-101 public datasets, PixelDance has achieved very significant performance improvements. This approach, which leverages image prior knowledge, can even enable the model to generate high-quality video content.
Temporal Consistency and Video Quality: PixelDance outperforms existing video generation techniques in producing long videos, making notable progress especially in maintaining temporal consistency and video quality.
Innovative Diffusion Model: PixelDance employs an innovative diffusion model, which is the key to its ability to effectively generate continuous video clips and surpass existing long video generation methods.
High Consistency and Rich Dynamics: Compared with other models, PixelDance has made significant progress in generating videos with high consistency and rich dynamics.
Method Based on Textual Guidance and First/Last-Frame Image Guidance: Through its method based on textual guidance and first/last-frame image guidance, PixelDance achieves video generation with high consistency and rich dynamics, without relying on complex datasets and large-scale model training.
Converting Static Images into Smooth Videos: Combined with the video conversion tool Boximator, PixelDance enables an entirely new way to convert static images into smooth videos.
Using PixelDance:
PixelDance offers two different video generation modes. One is the basic mode, in which users only need to provide one guiding image and a text description, and PixelDance will generate a video with high consistency and rich dynamics. The other is the advanced magic mode, in which users provide two guiding images and a text description, enabling better generation of more challenging video content.
Applications of PixelDance:
PixelDance can handle images in a variety of styles, including realistic, animated, anime, and fantasy styles. It also performs well in terms of character actions, facial expressions, camera viewpoint control, and special effects. In addition, based on a user-defined story, PixelDance can create every scene along with its corresponding actions. Whether the scene is realistic or fantastical, PixelDance can produce content with rich details and abundant motion.
By combining textual and image instructions and leveraging advanced diffusion models, PixelDance brings new possibilities to video generation, enabling the creation of high-quality videos with complex scenes and actions. The development of this technology not only demonstrates ByteDance's innovative capabilities in the AI field, but also provides new tools and inspiration for future video content creation.















