
 Script Planner Assistant▸
 AI Apps
 AI News
YOLO-World: Real-Time Open-Vocabulary Object Detection
YOLO-World: Real-Time Open-Vocabulary Object DetectionIntroduction
YOLO-World, a real-time object detection tool developed by Tencent's AI lab, is capable of automatically recognizing and locating various objects in images. YOLO-World outperforms many state-of-the-art methods in both speed and accuracy.
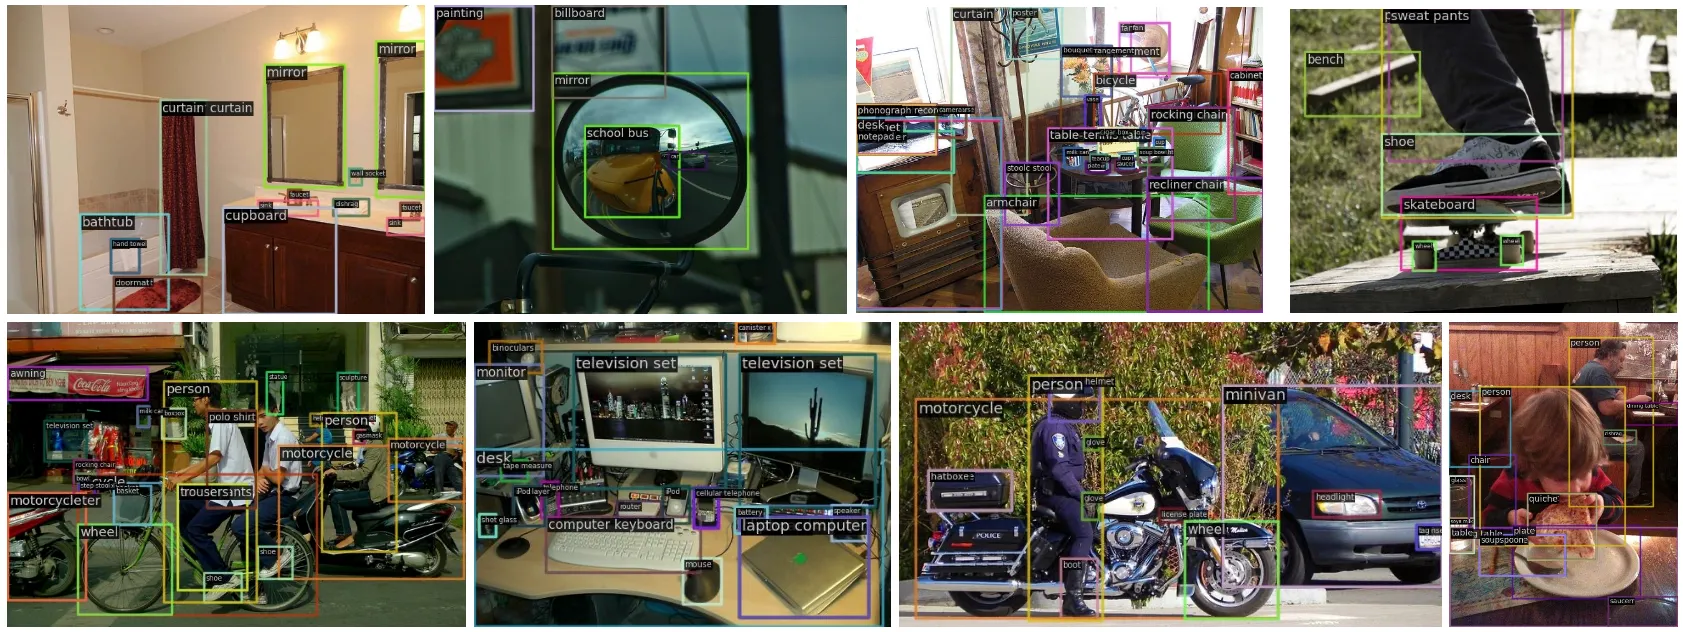
YOLO-World is the next-generation YOLO detector, designed for real-time open-vocabulary object detection. YOLO-World has been pre-trained on large-scale vision-language datasets (including Objects365, GQA, Flickr30K, and CC3M), which gives YOLO-World powerful zero-shot open-vocabulary capabilities and image grounding abilities, enabling real-time target detection without training. Even if certain objects have not been seen before, YOLO-World is suitable for object detection and open-vocabulary instance segmentation.
YOLO-World Features:
1. Large-Scale Learning: YOLO-World acquires rich visual and linguistic knowledge by learning from massive amounts of images and their corresponding descriptions (such as object names), enabling it to recognize a wide range of objects.
The project has been pre-trained on large-scale vision-language datasets including Objects365, GQA, Flickr30K, and CC3M, endowing it with strong zero-shot open-vocabulary capabilities and grounding abilities in images.
2. Fast and Accurate: YOLO-World achieves 35.4 AP in zero-shot evaluation on the LVIS dataset, and processes at 52.0 FPS on a V100, with both speed and accuracy surpassing many state-of-the-art methods. It maintains high accuracy even in images containing complex scenes. YOLO-World claims to be 20 times faster than GroundingDINO.
3. Zero-Shot Detection: Most impressively, even if YOLO-World has not seen certain objects before, it can leverage its prior learning and understanding capabilities, along with visual cues and contextual information in the image, to successfully recognize and locate these new objects. This means we don't need to train it to detect a new class of objects. We only need to provide the class name as an input text prompt, and the model will return the bounding boxes of these objects (if they exist).
4. Understanding Objects: YOLO-World relies not only on visual information but also incorporates linguistic information. It understands human language descriptions, enabling it to recognize objects even if they have not been directly seen before.
5. Compared with existing open-vocabulary detection methods, the YOLO-World model is at least 20 times faster. It can process approximately 52 frames per second.
6. Sets a new state-of-the-art on the LVIS object detection dataset.














