
 Script Planner Assistant▸
 AI Apps
 AI News
DreamActor-M1: ByteDance's Framework for Animating a Photo with Motion Video
小编 ·

DreamActor-M1: ByteDance's Framework for Animating a Photo with Motion Video
What is DreamActor-M1?
DreamActor-M1 is a human image animation framework based on diffusion transformers (DiT) launched by ByteDance. Similar to Runway's Act-One, given a reference image, DreamActor-M1 can mimic human behaviors captured from video, producing highly expressive and realistic videos at multiple scales (from portrait to full-body animation). It also addresses the issues found in other frameworks where facial expressions and movements lack subtlety, and details in long videos often become misaligned, causing inconsistencies. It supports various motion styles and outperforms Act-One, Animate Everyone, and SkyReels-A1.
Core Features of DreamActor-M1
Static Photo to Dynamic Video: By combining a single static photo with a reference motion video, the person in the photo is seamlessly placed into the video scene, generating dynamic footage with detailed expressions, natural movements, and high-definition image quality.
Fine-Grained Control: Uses a hybrid guidance mechanism that combines implicit facial representations, 3D head spheres, and 3D body skeleton control signals to achieve precise control over facial expressions and body movements.
Flexible Motion Transfer: Supports transferring only partial motion, such as facial expressions and head movements.
Facial Animation Support: Can be extended to audio-driven facial animation, achieving multilingual lip synchronization.
Shape-Aware Animation: Implements shape-adaptive animation generation through skeleton length adjustment techniques.
Diverse Style Support: Robust across various character and motion styles.
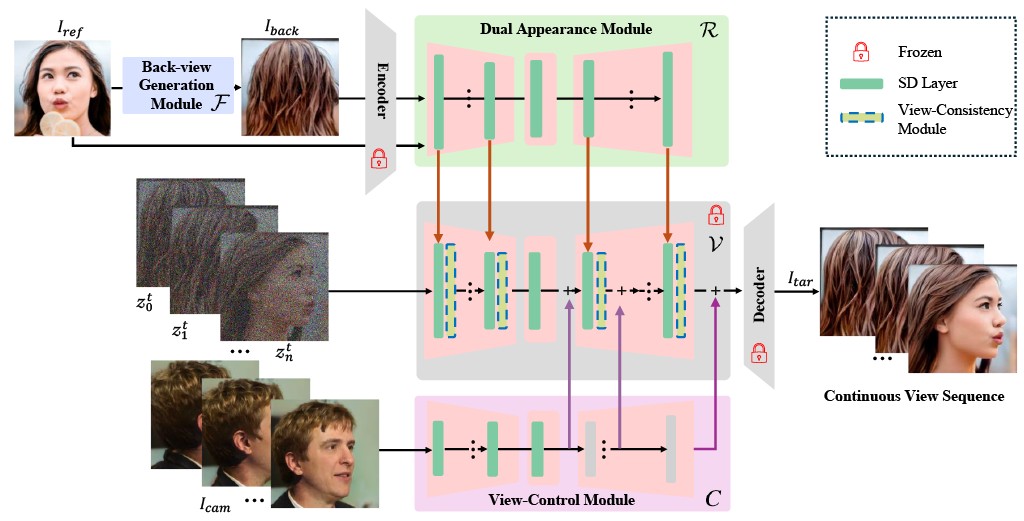
Multi-View Support: Generates animation results under different head poses.
Technical Principles of DreamActor-M1
Hybrid Guidance Mechanism: Combines implicit facial representations, 3D head spheres, and 3D body skeleton control signals to ensure generated animations are highly realistic in detail while maintaining overall coherence and smoothness.
Multi-Scale Adaptability: Through a progressive training strategy, it handles various body poses and images at different resolutions, supporting transformations from portrait to full-body views.
Long-Term Temporal Consistency: By integrating motion patterns and visual references across consecutive frames, it ensures temporal consistency in unobserved regions during complex movements.
Facial Animation and Speech Support: Supports audio-driven facial animation, achieving multilingual lip synchronization.
Application Scenarios of DreamActor-M1
Film and TV Production: Used to generate animations for virtual characters.
Advertising Industry: Create dynamic character advertisements.
Video Games: Generate character animations in games.
Virtual Streamers: Provide more natural and realistic animation effects for virtual streamers.
Education and Training: Create dynamic instructional videos where characters can perform various actions and expressions.
Social Media: Generate personalized dynamic avatars or short videos.
Project Links
Project Website: https://grisoon.github.io/DreamActor-M1/
arXiv Technical Paper: https://arxiv.org/pdf/2504.01724









