
 Script Planner Assistant▸
 AI Apps
 AI News
DreaMoving: A Diffusion-Based Human Video Generation Framework
DreaMoving: A Diffusion-Based Human Video Generation FrameworkIntroduction
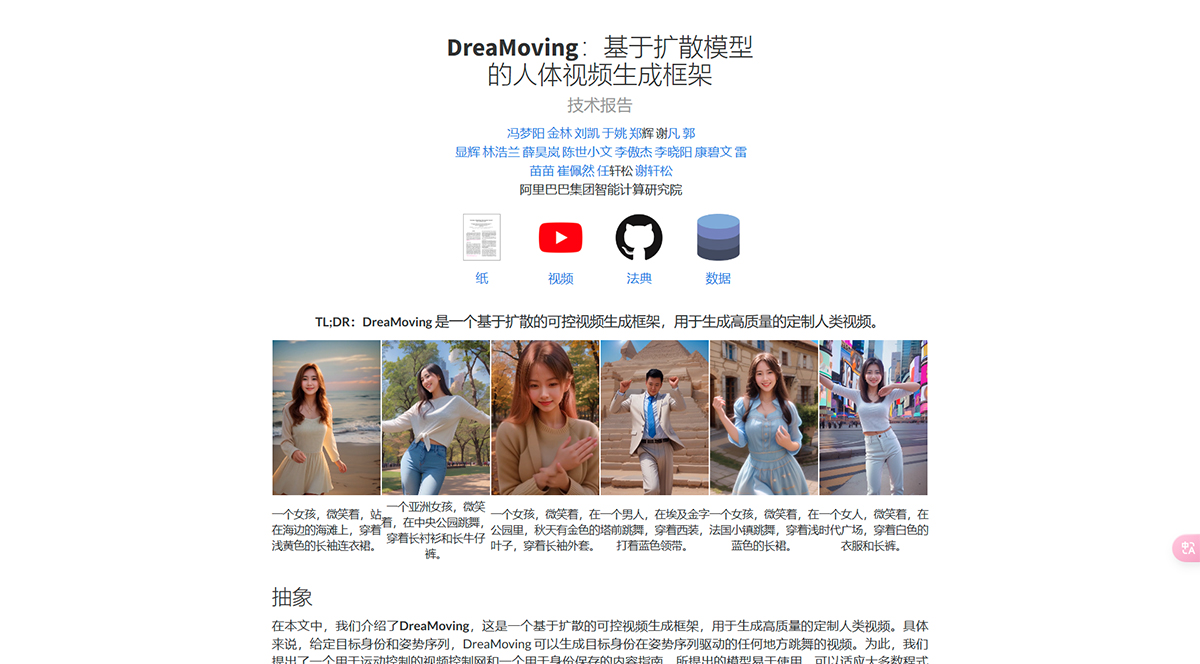
DreaMoving, a diffusion-based controllable video generation framework for producing high-quality customized human dance videos. Specifically, given a target identity and a pose sequence, DreaMoving can generate videos of the target identity dancing anywhere driven by the pose sequence. To this end, we propose a Video ControlNet for motion control and a content guider for identity preservation. The proposed model is easy to use, and can be adapted to most stylized diffusion models to generate diverse results.
DreaMoving project URL:https://dreamoving.github.io/dreamoving
DreaMoving Overview:
Video ControlNet is an image ControlNet that injects motion blocks after each U-Net block. Video ControlNet processes the control sequence (pose or depth) as additional temporal residuals. Denoising U-Net is a derived Stable-Diffusion U-Net with motion blocks for video generation. Content Guider transfers input text prompts and appearance expression (such as face (with cloth as optional)) into content embeddings for cross-attention.
Results:
DreaMoving can generate high-quality and high-fidelity videos, given guidance sequences and simple content descriptions, e.g., texts and reference images as inputs. Specifically, DreaMoving demonstrates proficiency in identity control via face reference images, precise motion manipulation through pose sequences, and holistic video appearance control prompted by specified text prompts.














