
 Script Planner Assistant▸
 AI Apps
 AI News

BrowserAct: A Powerful No-Code AI Web Scraper
BrowserAct: A Powerful No-Code AI Web ScraperIntroduction
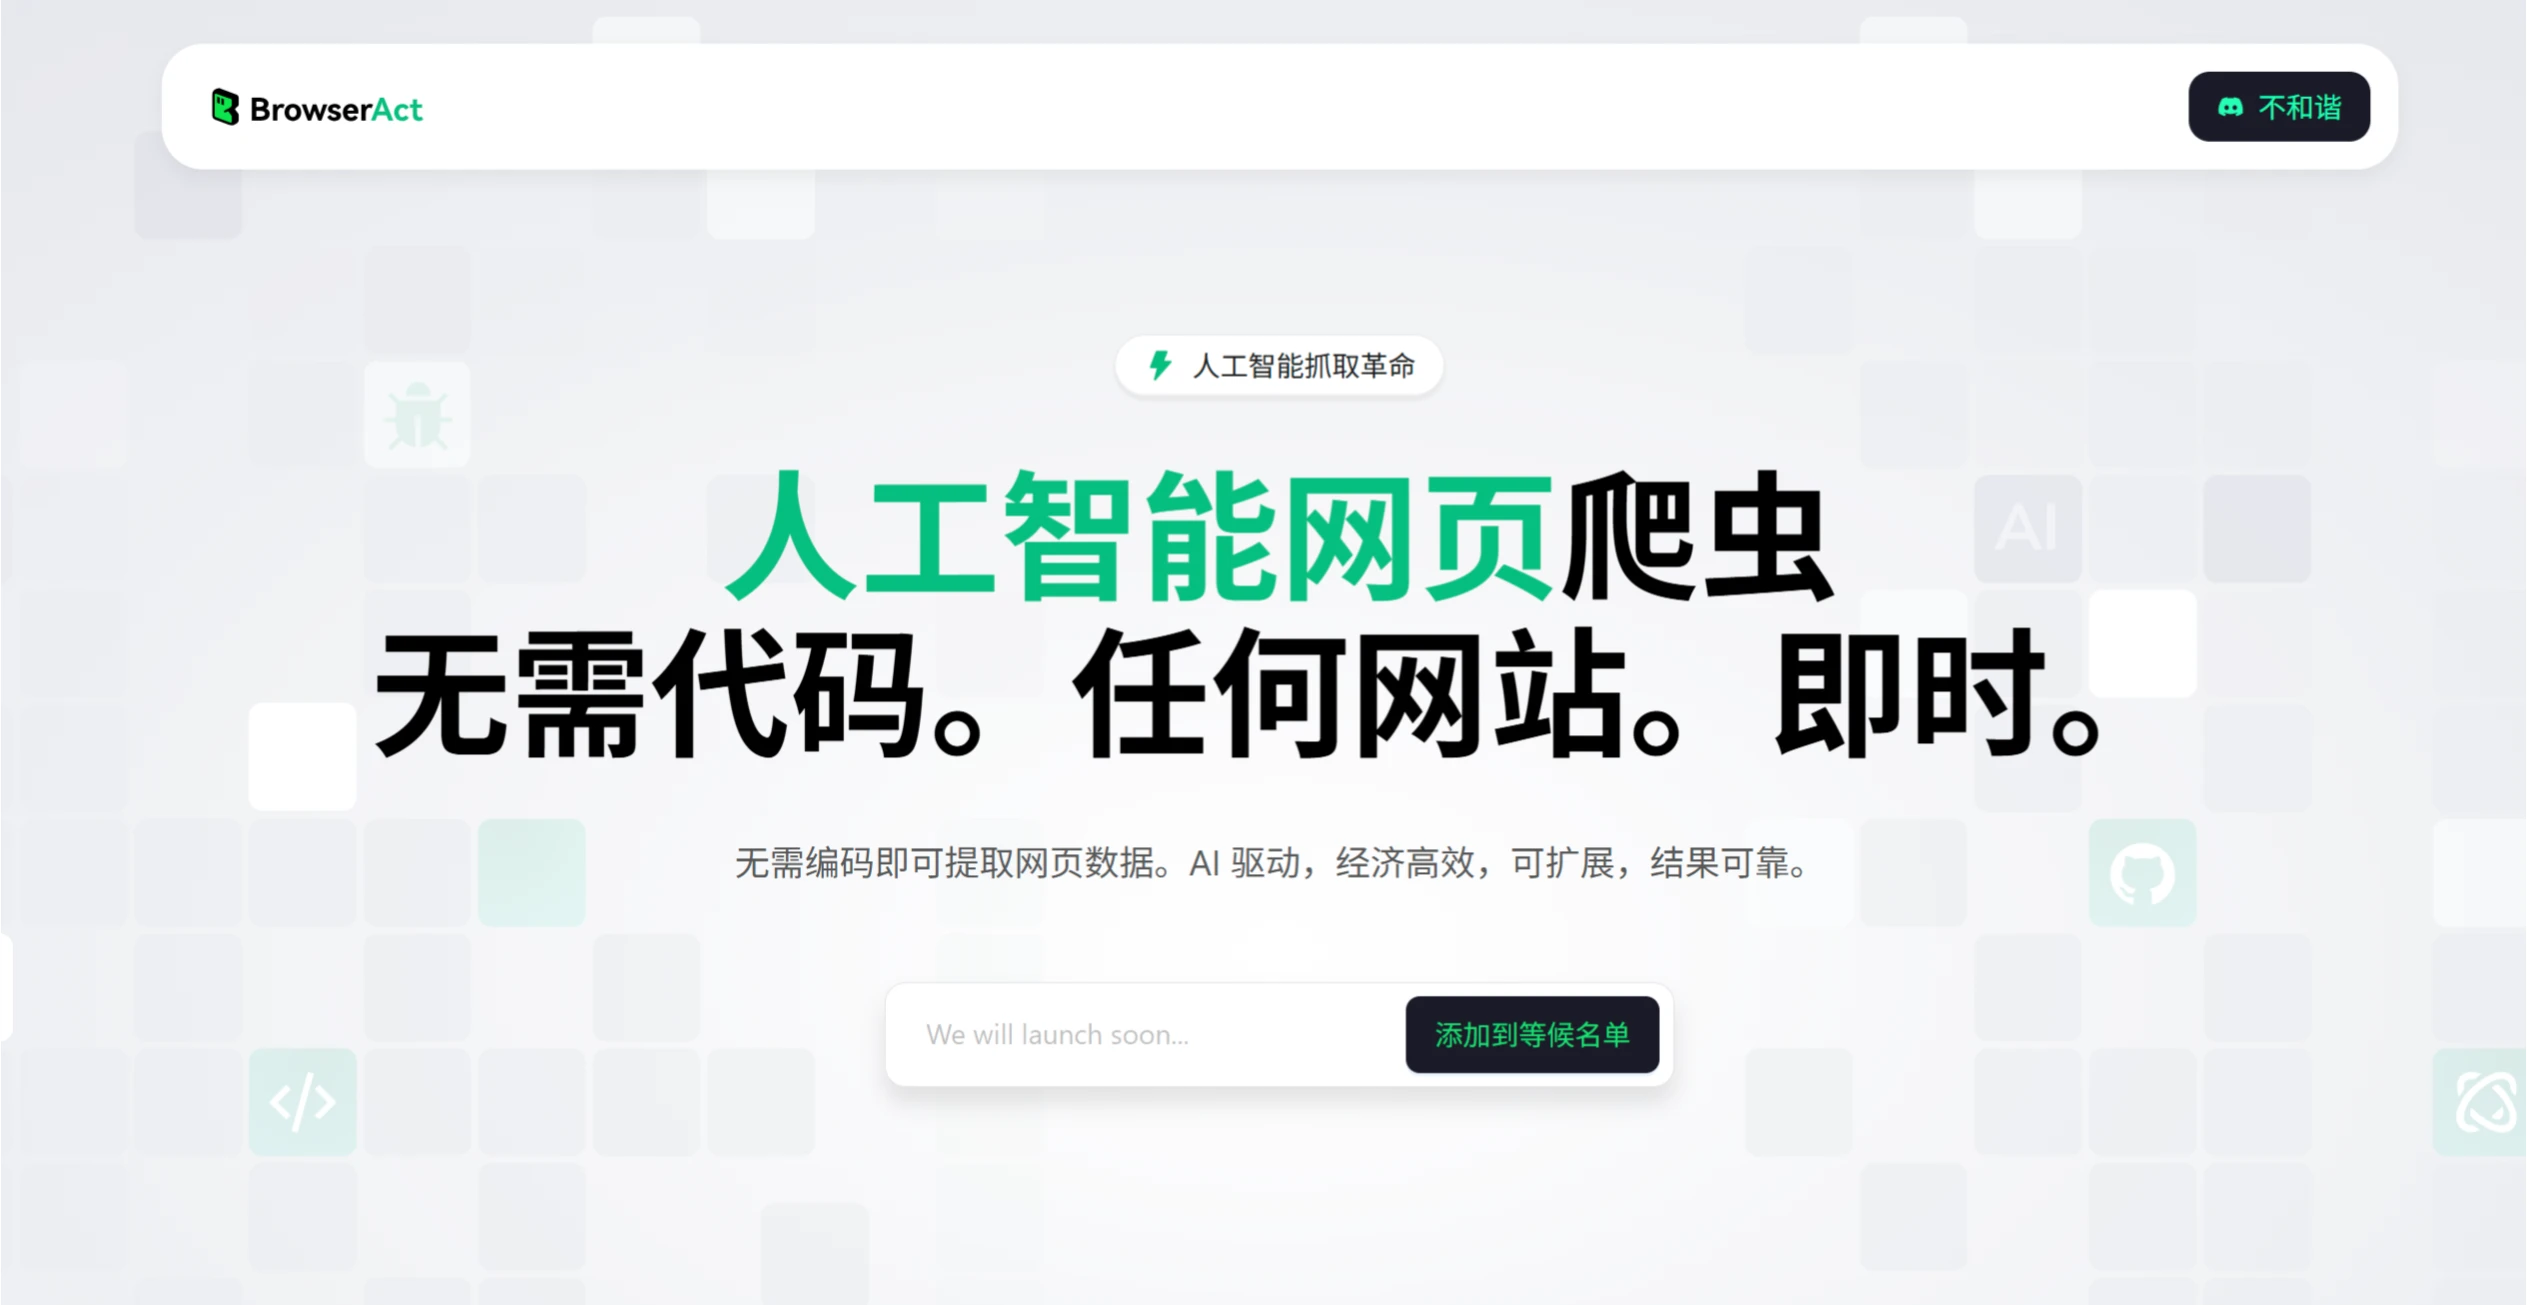
BrowserAct is a cloud-based browser automation tool that enables no-code data extraction and task automation through natural language instructions. It can collect structured data from any website, monitor industry content, and train ai agents. With features such as a global residential IP network, automatic verification bypass, and real-time data access, it is suitable for providing data support to large language models, market research, and AI assistant interaction automation.
Core Features
No-code web data extraction: No programming knowledge required. Simple operations allow you to scrape data from any website, suitable for e-commerce, social media, news, forums, and many other types of sites.
Smart optimization: Automatically identifies and extracts key data (such as prices, product information, article content, etc.), filtering out non-essential content like ads, navigation bars, and pop-ups, improving data purity.
Anti-scraping bypass: Simulates human browsing behavior (such as mouse movement, scrolling, clicking) to avoid being detected as a bot, and automatically handles CAPTCHAs, IP blocks, behavioral verification, and other anti-scraping measures.
Real-time & batch scraping
Real-time scraping: Dynamically obtain the latest data (such as price changes, inventory updates).
Scheduled/batch scraping: Supports long-term data storage, with options to update periodically or scrape large volumes of data at once.
High success rate & stability: Optimized scraping strategies reduce the risk of IP or account bans, support proxy IP rotation, and improve scraping efficiency and stealth.
Use Cases
E-commerce monitoring: Competitor pricing, inventory, and review scraping
Market research: Industry data and user review analysis
News & social media monitoring: Sentiment analysis and trend tracking
Academic research: Papers and public data collection
Automated data collection: Replace manual copy-paste
Advantages Summary
No programming required: Drag-and-drop operations, suitable for non-technical users.
Smart optimization: Automatically filters out interference, improving data quality.
Anti-scraping bypass: Simulates real-user behavior, reducing ban risks.
Flexible scraping: Supports both real-time & batch data acquisition.
High cost-performance: Easier to use and more stable than traditional scraper tools.
FAQ
Q: Can non-technical users use BrowserAct?
A: Absolutely. The tool emphasizes no-code, natural language interaction. Users only need simple instructions or workflow configurations to complete data extraction, making it suitable for marketers, researchers, and small-to-medium business users without a technical background.
Q: How does it handle a website's anti-scraping strategies?
A: A three-layer mechanism provides protection: ① A global residential IP pool simulates real-user access, reducing the risk of being identified as a bot; ② Automated verification bypass technology (such as CAPTCHA recognition); ③ AI-driven intelligent routing dynamically adjusts scraping strategies.
Q: How does BrowserAct work with large language models (such as GPT)?
A: You can directly feed the extracted data into the model, or provide the model with real-time web browsing capabilities (such as calling the BrowserAct API to retrieve information from specified web pages), helping the model overcome training data timeliness limitations and enabling dynamic information interaction.















