
 Script Planner Assistant▸
 AI Apps
 AI News
Spark-TTS: Efficient Text-to-Speech System with Zero-Shot Voice Cloning and Multilingual Synthesis
Spark-TTS: Efficient Text-to-Speech System with Zero-Shot Voice Cloning and Multilingual SynthesisIntroduction
What is Spark-TTS?
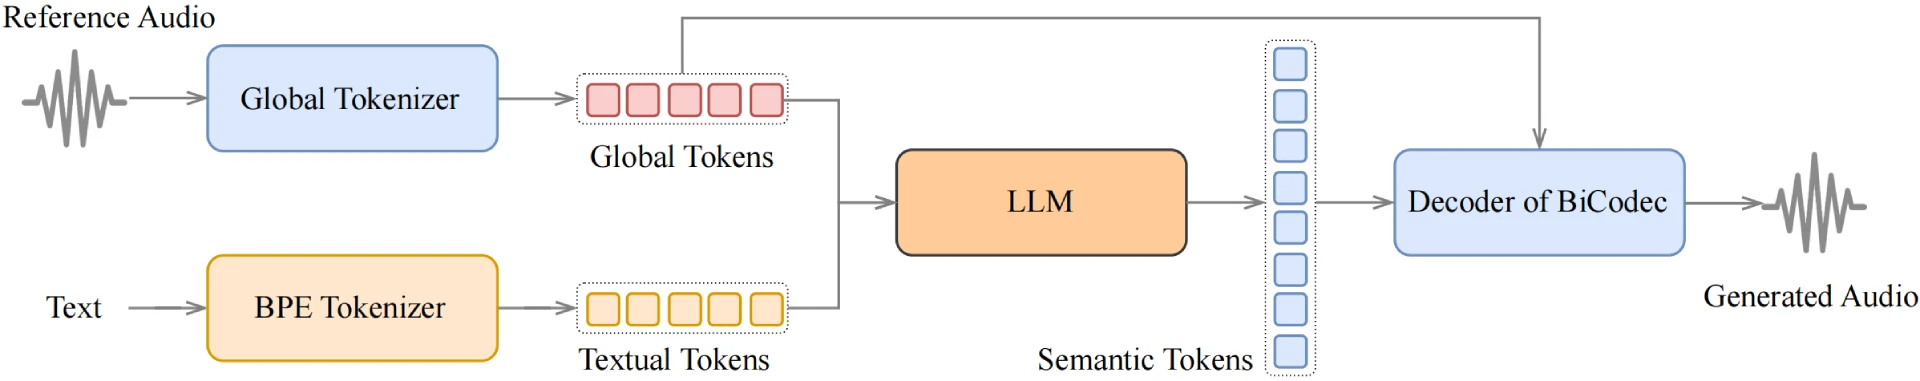
Spark-TTS is a text-to-speech (TTS) system developed by the SparkAudio team, built on Qwen2.5. It directly controls pitch, speed, and speaker style from text, and supports zero-shot voice cloning, multilingual synthesis, fine-grained voice control, and voice generation through a Web UI. It can quickly convert text into natural, high-quality speech. Unlike traditional TTS systems, it reconstructs audio directly from the encodings predicted by the LLM, simplifying the speech generation pipeline and improving efficiency.
Core Features of Spark-TTS
Zero-shot voice cloning: Spark-TTS supports zero-shot voice cloning, meaning it can replicate a speaker's voice even without training data for that specific speaker. In cross-lingual and code-switching scenarios, it seamlessly switches between different languages and speakers with excellent performance.
Multilingual support: The system supports both Chinese and English, maintaining a high degree of naturalness and accuracy in cross-lingual synthesis. Users can input text in one language and get speech output in another.
Fine-grained voice control: Users can customize the virtual speaker's voice by adjusting parameters such as gender, pitch, and speech rate, meeting the diverse speech content needs of scenarios such as virtual broadcasters and audiobooks.
Efficient speech synthesis: Spark-TTS is fully based on the Qwen2.5 architecture, requires no additional generative models, and reconstructs audio directly from the encodings predicted by the LLM, simplifying the pipeline and reducing complexity.
Virtual speaker creation: Users can create their own virtual speakers and give them a unique voice style by adjusting parameters.
Technical Architecture of Spark-TTS
The technical foundation of Spark-TTS is the BiCodec single-stream speech codec, which decomposes speech into low-bitrate semantic tokens (responsible for linguistic content) and fixed-length global tokens (responsible for speaker attributes). This separation enables flexible adjustment of voice characteristics, and combined with Qwen2.5's Chain-of-Thought technology, it further improves the quality and controllability of speech generation.
Application Scenarios of Spark-TTS
Audiobook production: Its natural speech quality makes it especially suitable for audiobooks.
Virtual broadcasting: By adjusting voice parameters, it generates virtual speakers that meet specific needs.
Cross-lingual speech synthesis: Supports multiple languages, extending its applicability worldwide.
Installation and Usage of Spark-TTS
1. Environment Preparation
Install Python: Make sure Python 3.12 is installed.
Install Conda: Used to manage virtual environments; you can download and install it from the Miniconda official website.
2. Clone the Repository
git clone https://github.com/SparkAudio/Spark-TTS.git
cd Spark-TTS
3. Install Dependencies
conda create -n sparktts -y python=3.12
conda activate sparktts
pip install -r requirements.txt
If you are in mainland China, you can use the Alibaba Cloud mirror:
pip install -r requirements.txt -i https://mirrors.aliyun.com/pypi/simple/ --trusted-host=mirrors.aliyun.com
4. Download the Pre-trained Model
Download the pre-trained model with the following command:
from huggingface_hub import snapshot_download
snapshot_download("SparkAudio/Spark-TTS-0.5B", local_dir="pretrained_models/Spark-TTS-0.5B")
5. Basic Usage
Run the following command for speech synthesis:
python -m cli.inference \
    --text "text to synthesis." \
    --device 0 \
    --save_dir "path/to/save/audio" \
    --model_dir pretrained_models/Spark-TTS-0.5B \
    --prompt_text "transcript of the prompt audio" \
    --prompt_speech_path "path/to/prompt_audio"
6. Web UI Usage
python webui.py --device 0
GitHub Repository:https://github.com/SparkAudio/Spark-TTS
HuggingFace Model Hub: https://huggingface.co/spaces/Mobvoi/Offical-Spark-TTS
Paper: https://arxiv.org/pdf/2503.01710
Demo: https://sparkaudio.github.io/spark-tts/
Related News:
Llasa: A Llama-based text-to-speech (TTS) system with natural, fluent, and expressive output
Octave: A TTS model released by Hume AI, featuring context awareness and emotional adaptation
Zonos-TTS: A multilingual text-to-speech model supporting voice cloning and emotion control
llasa 3B TTS: A text-to-speech (TTS) model based on the LLaMA architecture














