
 Script Planner Assistant▸
 AI Apps
 AI News
Step-Audio: First Open-Source Voice Interaction Model by Stepfun
Step-Audio: First Open-Source Voice Interaction Model by StepfunIntroduction
Step-Audio, as the industry's first product-level open-source voice interaction model, is capable of generating diverse voice expressions based on scenario requirements, covering emotions, dialects, languages, singing, and personalized styles, with natural and smooth interaction. In the HSK Level 6 evaluation, Step-Audio performed outstandingly and was praised as the open-source model that best understands Chinese. This AI model was jointly developed by StepFun and Geely Auto Group, and was officially open-sourced on February 18, 2025.
Step-Audio Features:
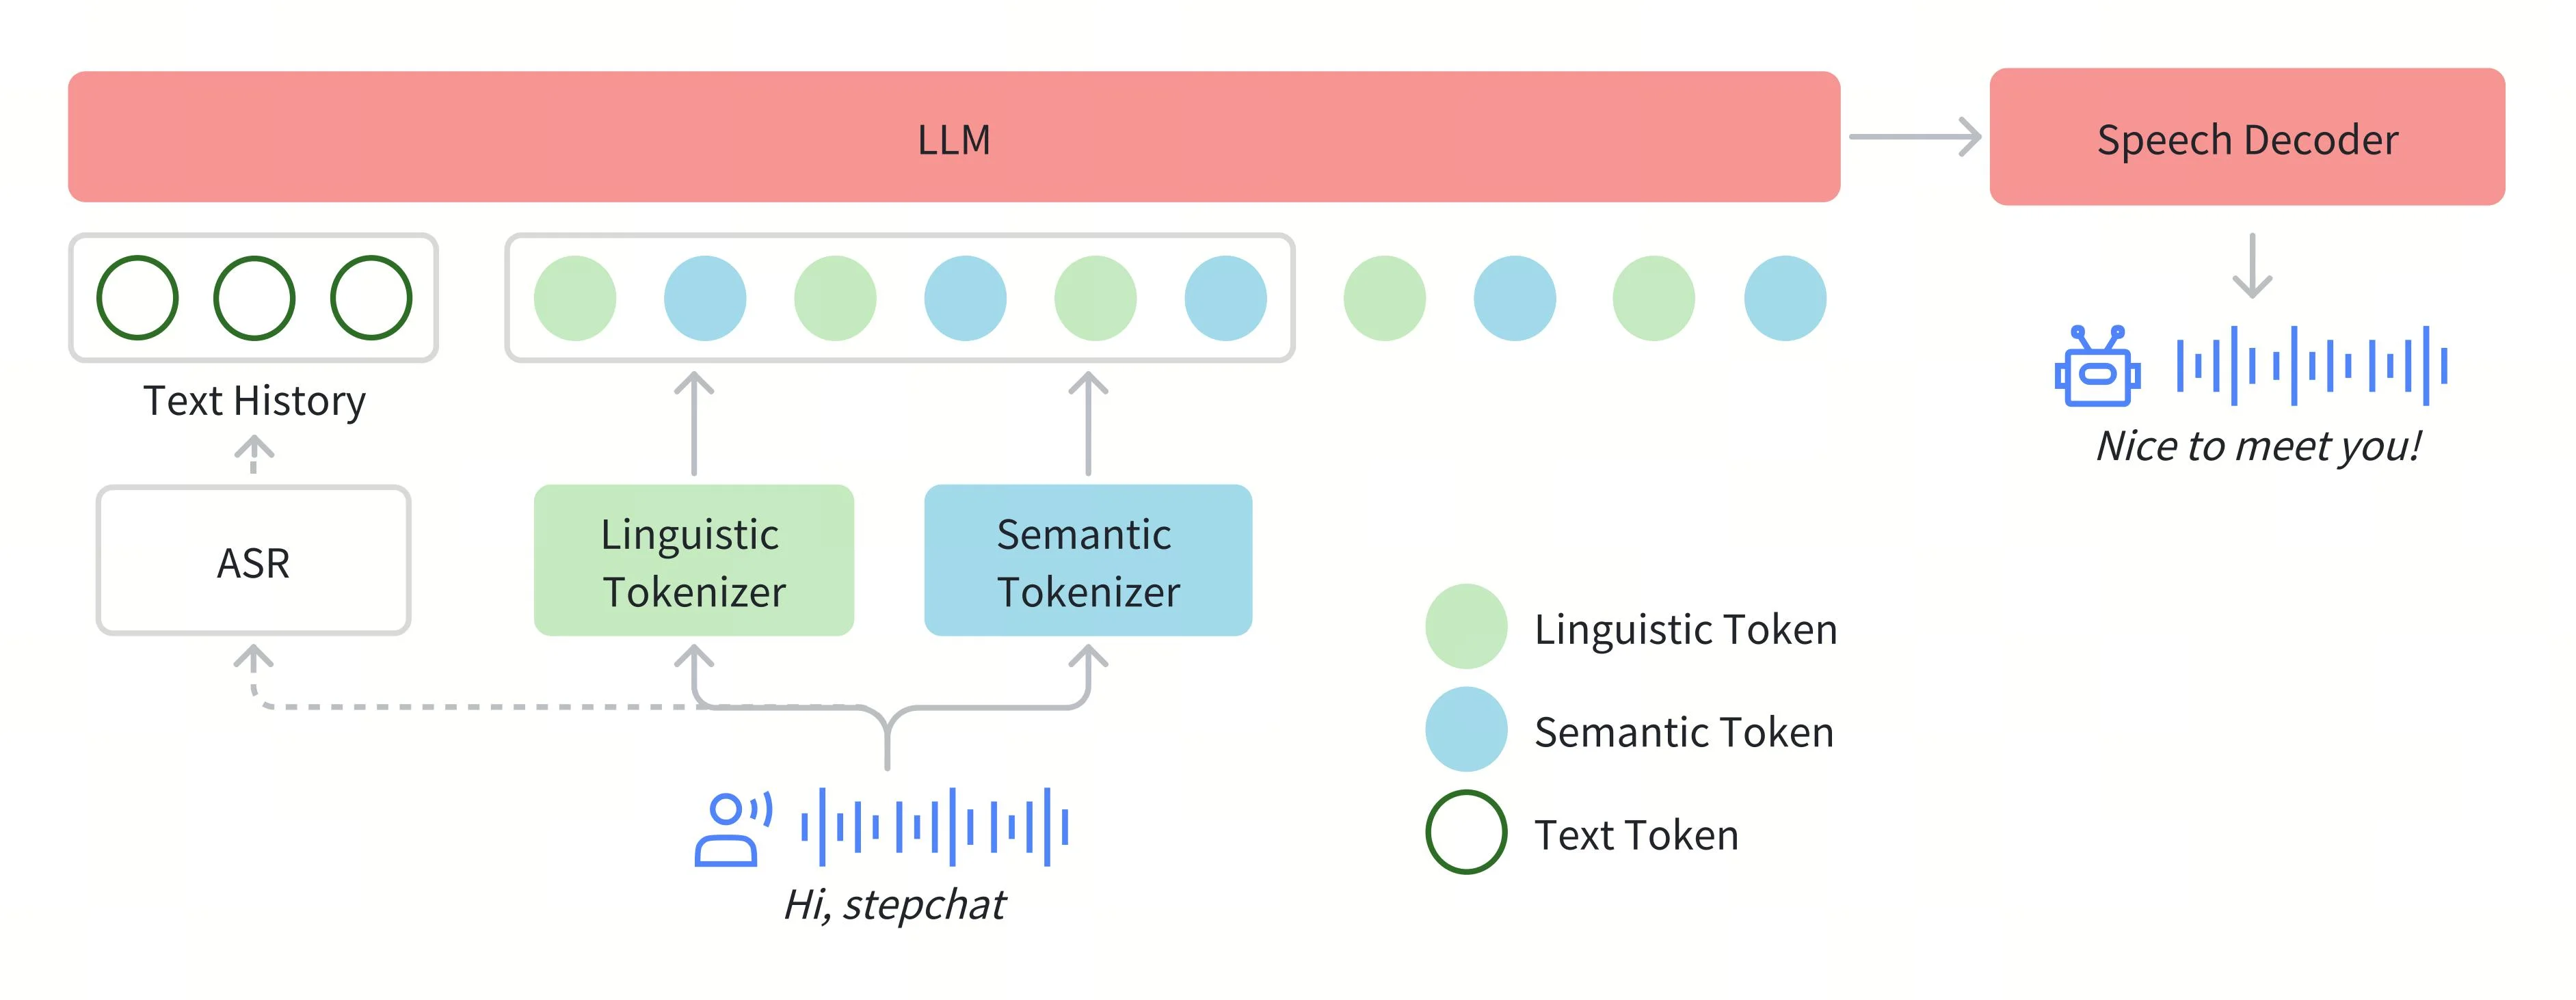
Unified Model: Based on a 13-billion-parameter multimodal model, it unifies voice understanding and generation, and can simultaneously handle speech recognition, semantic understanding, dialogue, voice cloning, audio editing, and synthesis.
Diverse Emotions and Styles: Generates voices with different emotions (angry/happy/sad), dialects (Cantonese/Sichuanese, etc.), languages, singing (RAP/humming), and personalized styles as needed, with precise control over emotion, dialect, language, and singing.
High-Quality Dialogue: Provides a natural, high-quality conversational experience with interaction as smooth as a real person.
Intelligent Interaction: Features advanced interaction capabilities including logical reasoning, creation, instruction control, language, role-playing, and word games.
Step-Audio Application Scenarios:
Intelligent Customer Service: Provides personalized, emotional service to enhance user experience.
Audio Reading: Generates emotional narration to enhance the immersive experience of audiobooks.
Audio-Video Creation: Automatically generates video dubbing or animation character voiceovers.
Game NPCs: Provides natural and smooth voice interaction for game characters.
Meeting Records: Converts voice to text in real time and provides voice feedback.
Education Assistance: Personalized teaching assistant that adjusts teaching style and tone.
Step-Audio Technical Features:
High Compression Ratio Technology: Adopts efficient compression technologies such as Video-VAE to optimize data processing.
Bilingual Processing Capability: Uses Hunyuan-CLIP and Step-LLM to handle Chinese and English prompts.
DIT Architecture and Video-DPO Algorithm: Optimizes the processing of complex video and audio data.
Large-Scale Dataset Training: Builds large datasets to ensure model generalization and detail performance.
How to Use Step-Audio:
Get the Model: Visit the Yuewen APP or platforms like Hugging Face for the open-source version of Step-Audio.
Technical Report: Read the technical report on arxiv.org or GitHub for details.
API Interface: Implement voice interaction via API calls, following the MIT open-source license.
Integration Development: Integrate into applications according to official documentation or sample code.
Customized Training: Advanced users can fine-tune the model to adapt to specific scenarios or improve performance.
How to Obtain Step-Audio
GitHub: https://github.com/stepfun-ai/Step-Audio
ModelScope: [Click to Visit]
Technical Report: [Click to Visit]
Supports one-click deployment via PAI Model Gallery [Click to Visit]














