
 Script Planner Assistant▸
 AI Apps
 AI News
FireRedASR – Xiaohongshu's Open-Source Speech Recognition Model
FireRedASR – Xiaohongshu's Open-Source Speech Recognition ModelIntroduction
FireRedASR is an open-source large-model-based speech recognition model released by the Xiaohongshu FireRed team on February 9, 2025. It achieves a new SOTA in Mandarin Chinese speech recognition (Character Error Rate of 3.05%) and supports dialects, English, and lyrics recognition.
Main Features of FireRedASR:
High-Precision Speech Recognition: FireRedASR-LLM (8.3B parameters) achieves a Character Error Rate (CER) of 3.05% on public test sets, setting a new SOTA, with an 8.4% reduction in error rate compared to the previous SOTA model Seed-ASR (12B+ parameters).
Efficient Inference: FireRedASR-AED (1.1B parameters) significantly improves inference efficiency while maintaining high accuracy, with a CER of 3.18%.
Multi-Scenario Adaptation: FireRedASR performs exceptionally well in various daily scenarios such as short videos, live streaming, voice input, and intelligent assistants. Compared to industry-leading ASR service providers and Paraformer-Large, it achieves a relative CER reduction of 23.7%~40.0%.
Lyrics Recognition Capability: In scenarios requiring lyrics recognition, FireRedASR-LLM achieves a relative CER reduction of 50.2%~66.7%, demonstrating strong adaptability.
Multilingual Support: FireRedASR supports Mandarin and performs excellently in Chinese dialect and English speech recognition, further broadening its application scope.
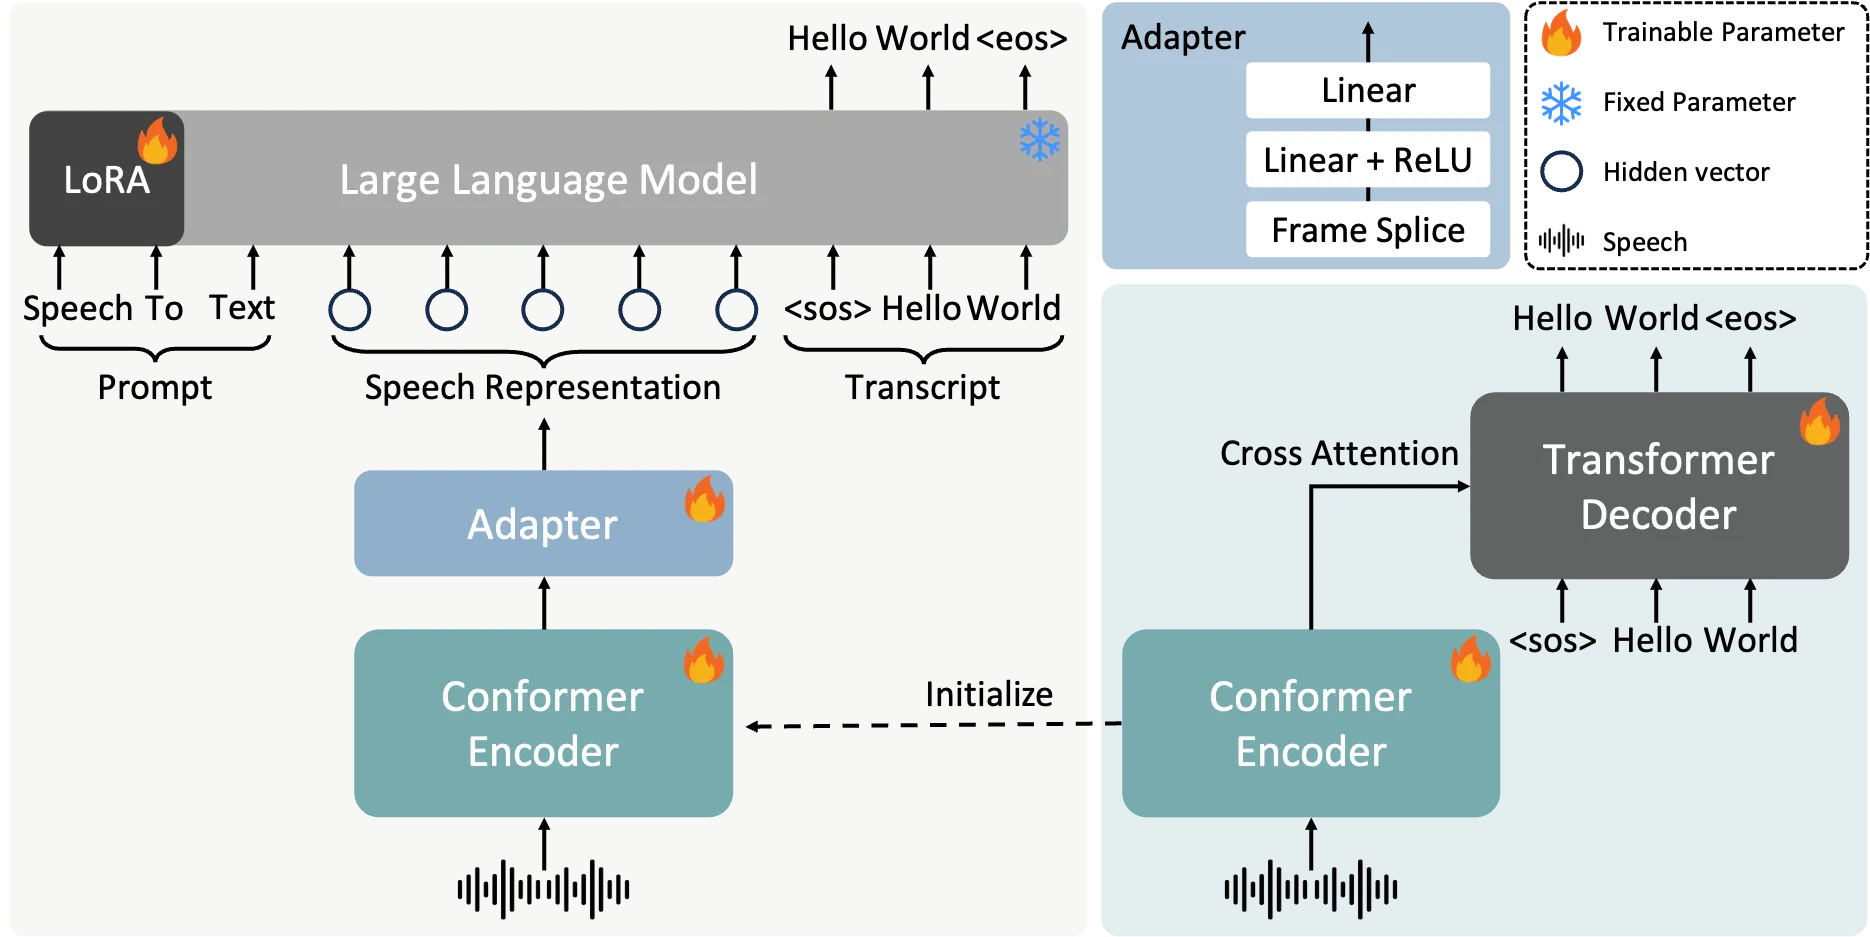
Two Core Versions of the FireRedASR Model:
FireRedASR-LLM
Architecture: Adopts an Encoder-Adapter-LLM framework, combined with the large language model Qwen2-7B-Instruct, achieving end-to-end speech interaction through LoRA fine-tuning.
Performance: Achieves a CER of 3.05% on Mandarin benchmarks, an 8.4% reduction in error rate compared to the previous SOTA model; a relative CER reduction of 50.2%~66.7% in lyrics recognition scenarios.
Features: 8.3B parameters, focused on ultimate precision, suitable for demanding scenarios such as professional subtitle generation.
FireRedASR-AED
Architecture: Based on an attention encoder-decoder (Conformer encoder + Transformer decoder), with 1.1B parameters.
Performance: CER of 3.18%, outperforming Seed-ASR with 12B parameters, with higher inference efficiency.
Features: Balances accuracy and computational efficiency, suitable for real-time applications such as live streaming subtitles and voice assistants.
Technical Highlights of FireRedASR:
Multi-Scenario Adaptation: Achieves a relative CER reduction of 23.7%~40.0% in daily scenarios such as short videos and live streaming; supports Chinese dialects and English.
Open-Source Ecosystem: The model and code are open-sourced (GitHub), adopting an industrial-grade design, supporting secondary development by the community.
Training Strategy: The LLM version fixes most parameters and only trains the encoder and adapter, retaining pre-training capabilities.
Application Scenarios of FireRedASR
Intelligent Voice Interaction: FireRedASR can be applied in scenarios such as intelligent voice assistants and voice input methods, offering high-precision speech recognition services.
Multimedia Content Understanding: FireRedASR performs exceptionally well in multimedia content understanding scenarios such as video subtitle generation and lyrics recognition.
Daily Scenario Applications: FireRedASR performs exceptionally well in various daily scenarios such as short videos, live streaming, voice input, and intelligent assistants. Compared to industry-leading ASR service providers and Paraformer-Large, it achieves a relative CER reduction of 23.7%~40.0%.
Related Links for FireRedASR:
Project URL: https://github.com/FireRedTeam/FireRedASR
Paper URL: https://arxiv.org/abs/2501.14350














