
 Script Planner Assistant▸
 AI Apps
 AI News

PengChengStarling: Multilingual Speech Recognition System Open-Sourced by Pengcheng Laboratory
PengChengStarling: Multilingual Speech Recognition System Open-Sourced by Pengcheng LaboratoryIntroduction
PengChengStarling is an open-source multilingual speech recognition system from Peng Cheng Laboratory. It supports real-time speech recognition, transcribing as you speak. It is ideal for use in scenarios like converting international conference recordings to text, automatically generating subtitles for multilingual videos, and cross-language customer service systems.
PengChengStarling is developed based on the icefall project. Its model size is only 20% of Whisper-Large v3, yet its inference speed is 7 times faster. It supports 8 languages, including Chinese, English, Russian, Vietnamese, Japanese, Thai, Indonesian, and Arabic, and is capable of handling multilingual speech input within a unified framework, greatly improving the efficiency of speech recognition.
PengChengStarling Features:
Model Size and Performance: The model size of PengChengStarling is only 20% of Whisper-Large v3, making it more efficient in terms of storage and computational resources.
Inference Speed: The inference speed of the PengChengStarling system is 7 times faster than Whisper-Large v3, enabling it to process speech input in a shorter time and making it suitable for real-time application scenarios.
Multilingual Support: PengChengStarling supports up to 8 languages, including Chinese, English, Russian, Vietnamese, Japanese, Thai, Indonesian, and Arabic, meeting the needs of different users.
Model Architecture: It adopts the RNN-T architecture, composed of three modules: Encoder, Decoder, and Joiner, with Zipformer as the speech encoder.
Performance Improvement: Compared to Whisper-Large v3, PengChengStarling achieves comparable or better performance across 6 languages, with a Real-Time Factor (RTF) of 0.016 and an inference speed nearly 7 times faster.
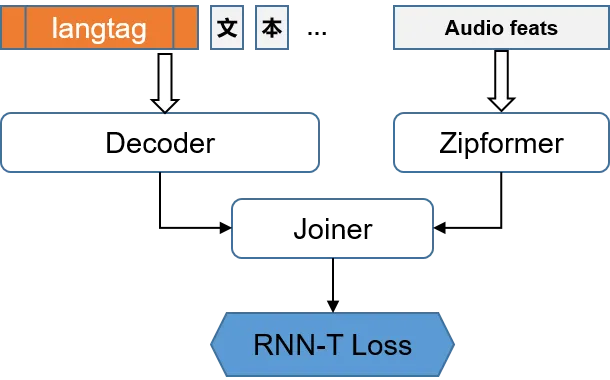
PengChengStarling Application Scenarios:
Intelligent Assistants: It can be integrated into intelligent assistants to enable the recognition and response of voice commands.
Customer Service: In customer service centers, it leverages speech recognition technology to improve the response speed and accuracy of customer inquiries.
Education Sector: In language learning and educational applications, it helps students with pronunciation practice and language communication.
Meeting Records: In conferences, it transcribes spoken content in real time, enhancing meeting efficiency.
Multilingual Translation: Combined with translation systems, it enables real-time multilingual communication.
PengChengStarling has demonstrated outstanding performance in evaluations, particularly in comparisons with Whisper-Large v3. PengChengStarling achieves comparable or superior streaming speech recognition performance across six languages. In addition, the training data volume for each language is approximately 2,000 hours, primarily sourced from open datasets, providing a very solid foundation for its multilingual support.
In practical applications, PengChengStarling can also be used for adaptive speech recognition technology, making personalized adjustments based on the user's speech characteristics to improve recognition accuracy, especially in noisy environments.
Github:https://github.com/yangb05/PengChengStarling
HuggingFace:https://huggingface.co/stdo/PengChengStarling














