
 Script Planner Assistant▸
 AI Apps
 AI News
Kokoro TTS – Open-Source, High-Performance Text-to-Speech Model
Kokoro TTS – Open-Source, High-Performance Text-to-Speech ModelIntroduction
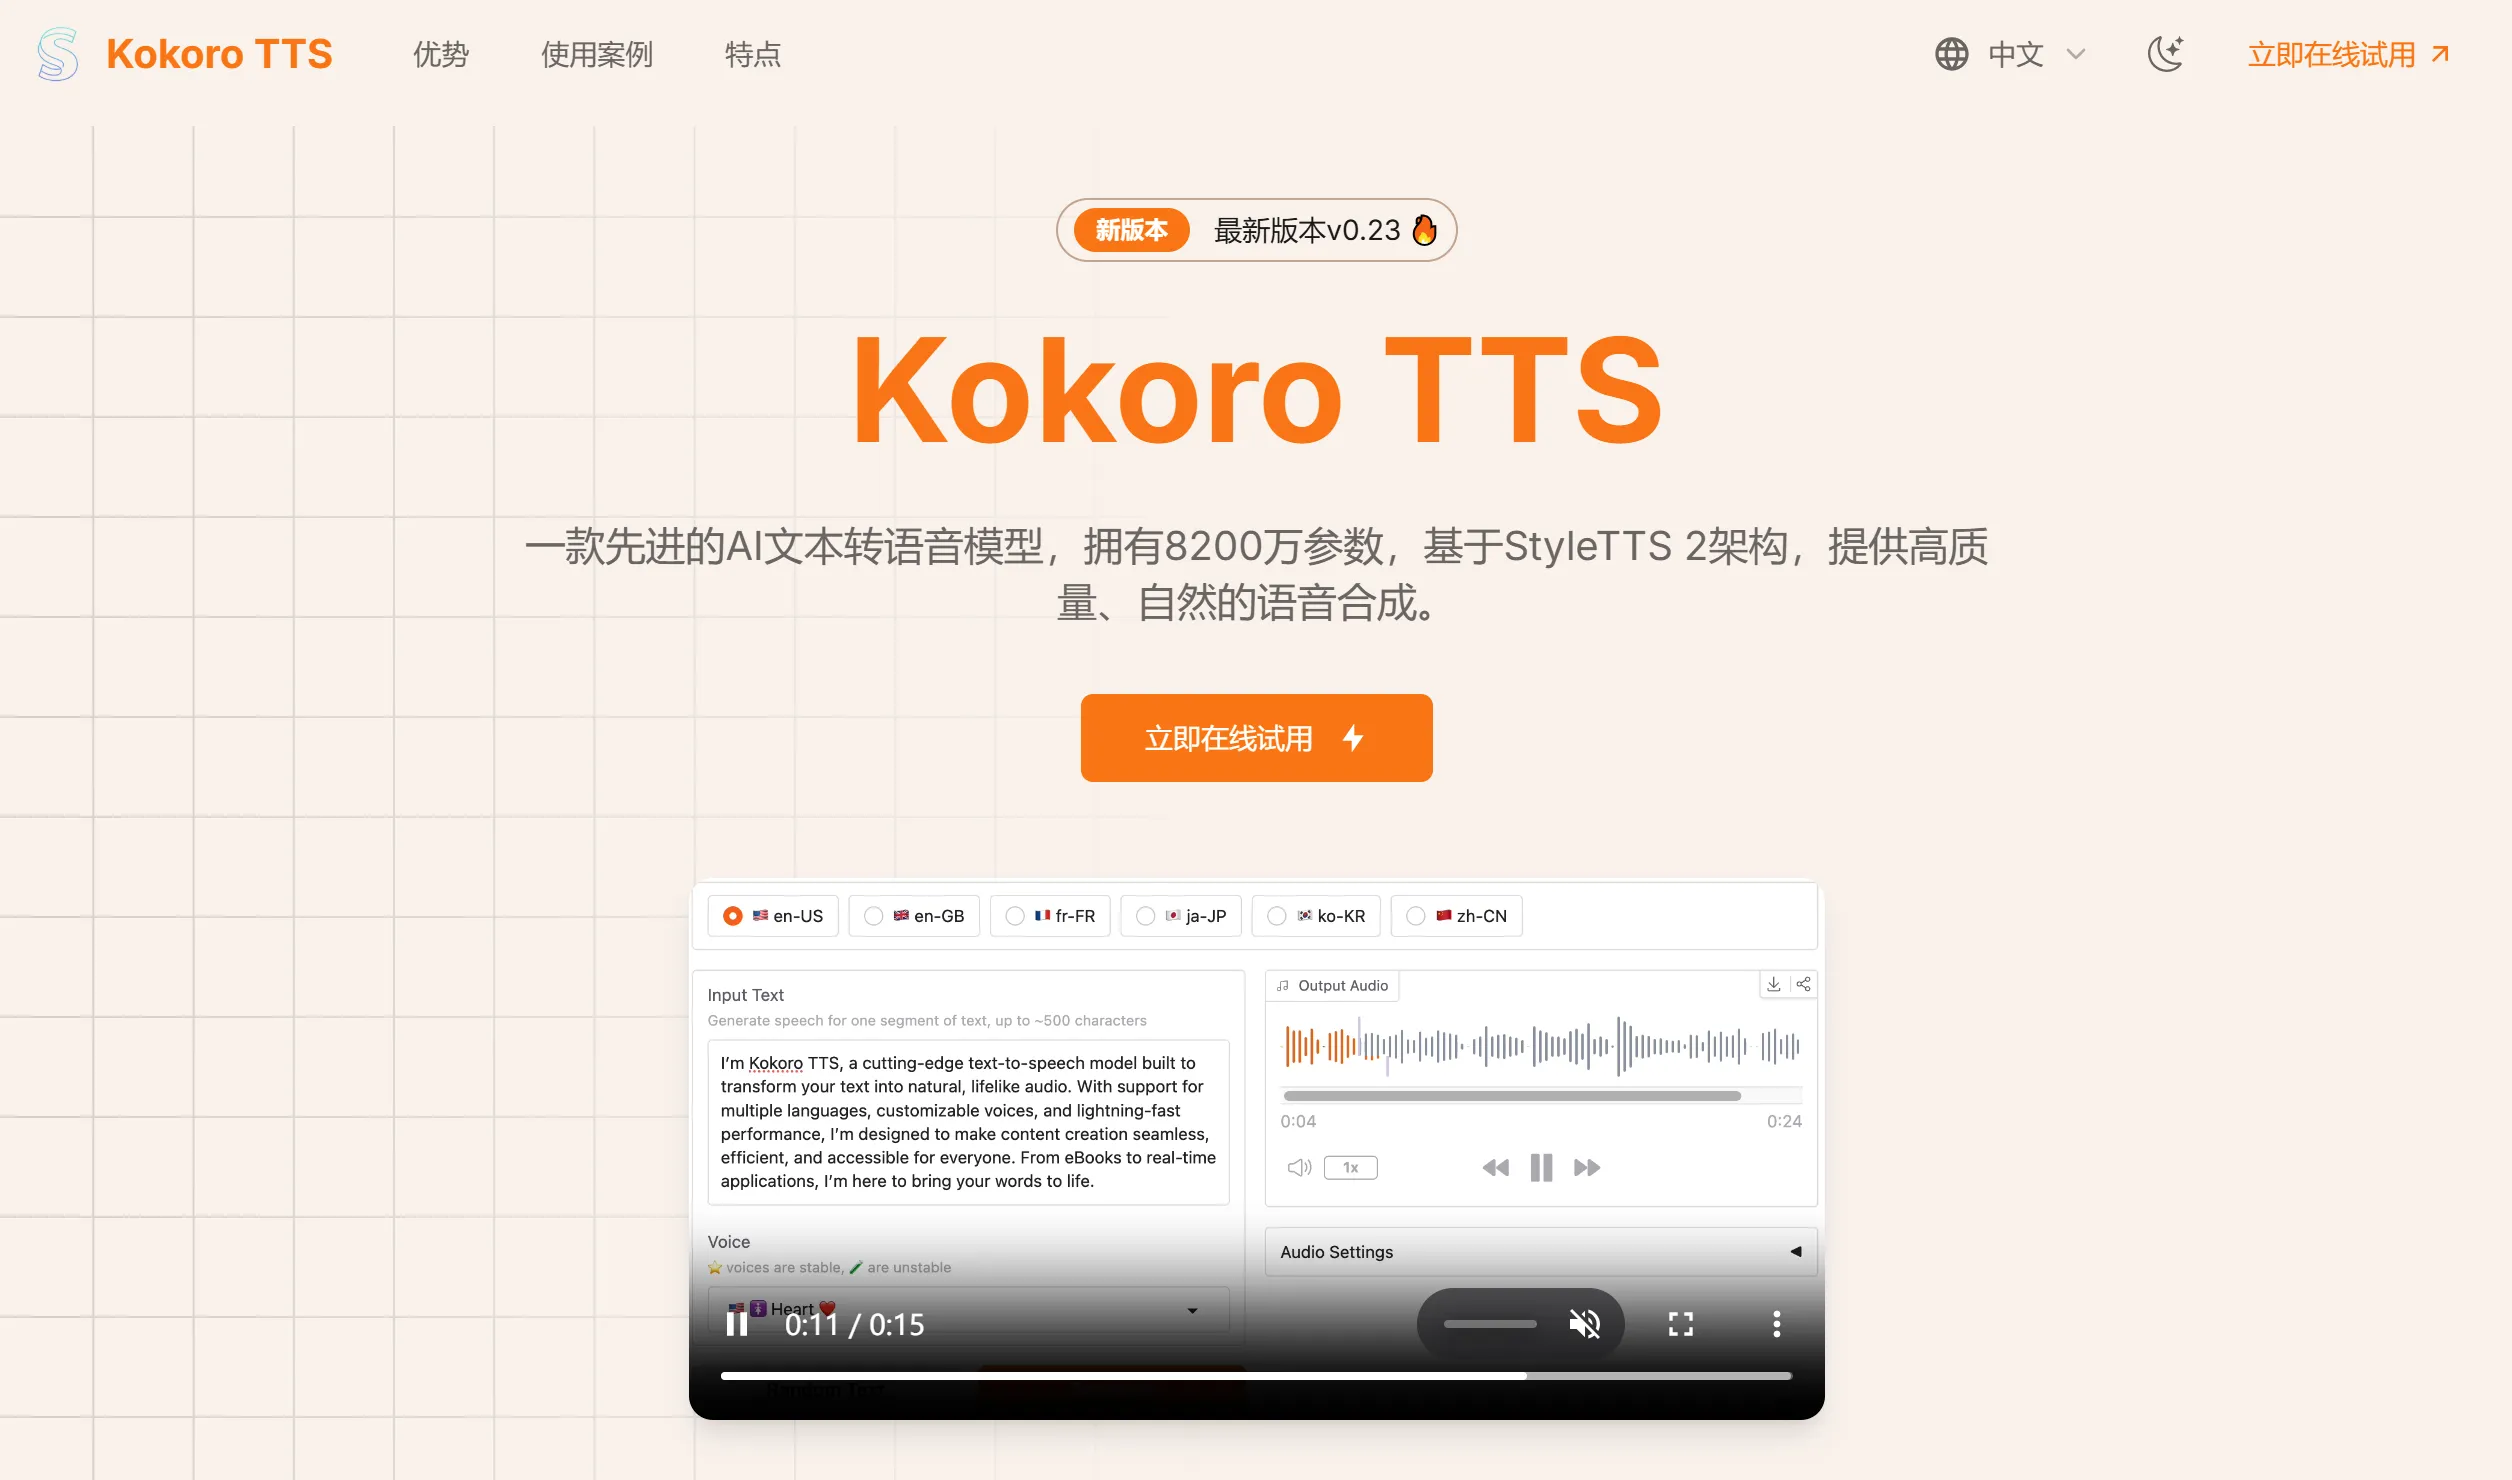
Kokoro TTS is an open-source, lightweight, high-performance text-to-speech (TTS) model with 82 million parameters, built on the StyleTTS 2 architecture. It delivers high-quality, natural speech synthesis suitable for audiobooks, podcasts, and more, making it a standout product in the TTS field.
Kokoro TTS Features
High-Quality Speech Synthesis: Kokoro TTS can convert text into natural, fluent speech, supporting multiple languages including American and British English, French, Japanese, Korean, and Chinese.
Multilingual Support: Supports languages such as American English, British English, French, Korean, Japanese, and Mandarin Chinese.
Voice Style Diversity: Kokoro TTS not only generates natural, fluent speech but also supports special styles such as whispering, along with 10 different voice packs covering different genders and characteristics.
Low Resource Consumption: With only 82M parameters, Kokoro TTS consumes fewer resources compared to many mainstream TTS models and can run efficiently on ordinary computers.
Real-Time Generation: Kokoro TTS supports real-time speech generation, allowing users to instantly obtain the desired voice output.
Support for Multiple Input Formats: This tool supports various input formats, including text files and e-books (such as EPUB).
Kokoro TTS Core Features:
Lightweight and High Performance
With only 82 million parameters, Kokoro TTS achieves voice quality comparable to large models with billions of parameters (such as MetaVoice and XTTS) through an optimized hybrid architecture of StyleTTS 2 and ISTFTNet37. Its decoder-only design abandons the traditional encoder structure, reducing computational complexity and enabling near real-time synthesis on CPU and accelerated processing on GPU710.
Speed and Efficiency: Synthesis speed is under 100ms, supporting edge computing and deployment on low-resource devices.
Multilingual Support: Currently focuses on English (American/British), but the architecture supports future expansion to Chinese, French, Japanese, and other languages.
Open Source and Commercial Use
Licensed under Apache 2.0, it allows free commercial use and secondary development, making it suitable for individual developers and enterprise integration. The Hugging Face platform provides model weights and deployment documentation, lowering the barrier to entry.
Diverse Voice Styles
Provides 10+ pre-trained voice packs (such as Bella, Adam, Sarah), covering different genders and accents, supporting special styles like whispering to enhance expressive diversity.
kokoroTTS Technical Advantages:
Architectural Innovation:Combining the prosody control of StyleTTS 2 and the efficient spectrum generation of ISTFTNet, it eliminates the need for diffusion models, reducing computational resource consumption while maintaining high-fidelity audio quality.
Training and Data Compliance:Based on a curated 100-hour dataset, with data sources including public domain audio and compliant synthetic content, ensuring copyright safety.
Deployment Flexibility:Supports ONNX runtime optimization, can be deployed locally or in the cloud, requires no GPU dependency, is compatible with tools such as Docker and FastAPI, and provides a REST API interface.
kokoroTTS Application Scenarios:
Real-Time Interactive Systems: Such as voice assistants and customer service responses, leveraging low-latency characteristics to achieve instant voice feedback710.
Content Creation: Audiobooks, advertising voiceovers, game character voice generation, supporting personalized voice selection712.
Accessibility Services: Providing text-to-speech support for visually impaired users, offering text reading services to help them access information.
Education and Media: Online course explanations, podcast production, generating multilingual training videos or educational audio content.
Games and Virtual Reality: In games and VR applications, Kokoro TTS can provide natural voices for characters.
Converting E-books into Kokoro Audiobooks: Easily transform your e-book library into high-quality audiobooks. Even for niche titles, Kokoro's natural multilingual voices can handle it.
Quick Start
Download from Github and install dependencies via pip or npm;
Clone the Kokoro TTS model from Hugging Face and load voice packs;
Call the API to generate 24kHz audio, supporting local or edge device operation.
Thanks to its open-source and commercial-friendly license, Kokoro TTS holds a competitive advantage in the market, especially in commercial applications requiring high-quality speech synthesis.
Related News:
llasa 3B TTS: A Text-to-Speech (TTS) Model Based on the LLaMA Architecture
10 Recommended Excellent Open-Source TTS Voice Models
Seed-TTS: A High-Quality Text-to-Speech TTS Model Developed by ByteDance














