
 Script Planner Assistant▸
 AI Apps
 AI News
ChatTTS-Forge: An All-in-One TTS Toolkit
ChatTTS-Forge: An All-in-One TTS ToolkitIntroduction
ChatTTS-Forge is a project built around TTS (Text-to-Speech) generation models, offering users flexible TTS generation capabilities. It supports multiple voice timbres, style control, long-text inference, and other features. ChatTTS-Forge provides various APIs (Application Programming Interfaces) that developers can leverage to easily convert text into speech.
ChatTTS-Forge is a project built around TTS (Text-to-Speech) generation models. It provides users with flexible TTS generation capabilities, supporting multiple voice timbres, style control, and long-text inference.
ChatTTS-Forge offers various APIs (Application Programming Interfaces) that developers can use directly to easily convert text into speech. In addition, it provides an easy-to-use web interface (WebUI), allowing users to input text and generate speech directly on the web without programming.
Key Features of ChatTTS-Forge:
TTS Generation: Supports inference with multiple TTS models, including ChatTTS, CosyVoice, FishSpeech, GPT-SoVITS, etc., allowing users to freely choose and switch voices.
Voice Timbre Management: Comes with multiple built-in voice timbres and supports uploading custom voice timbres. Users can create and use custom voices by uploading audio or text.
Style Control: Provides a variety of style control options, including adjusting speech speed, pitch, and volume, as well as adding voice enhancement (Enhancer) to improve output quality.
Long-Text Processing: Supports automatic segmentation and inference of extremely long texts, capable of generating audio content for long-form text.
SSML Support: Uses the XML-like SSML syntax for advanced TTS synthesis control, suitable for more detailed voice generation scenarios.
ASR (Automatic Speech Recognition): Integrates the Whisper model to support speech-to-text functionality.
Technologies and Methods of ChatTTS-Forge:
API Server: An API server built with Python that provides efficient TTS services, supporting multiple concurrent requests and custom configurations.
WebUI: A user interface based on Gradio, allowing users to experience TTS features through a simple operational interface.
Docker Support: Offers Docker containerized deployment options to simplify the deployment process on both local machines and servers.
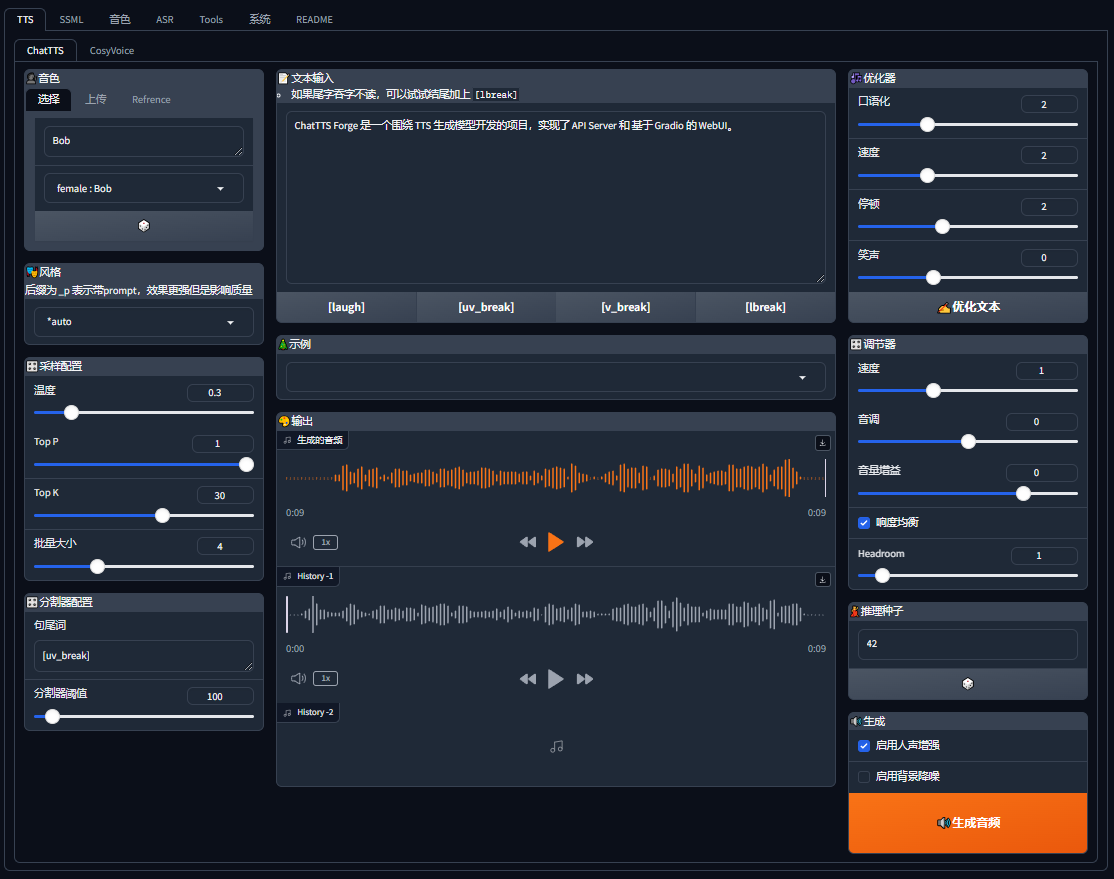
Features of ChatTTS-Forge WebUI:
TTS (Text-to-Speech): Through the WebUI, users can input text and generate speech using various TTS models.
Voice Timbre Switching: Supports switching between multiple preset voice timbres, allowing users to choose different voices to generate speech.
Custom Voice Upload: Users can upload their own voice files to generate personalized voices on the fly.
Style Control: You can adjust the style of the speech, including parameters such as speech speed, pitch, and volume, to produce voices that meet specific needs.
Long-Text Processing: Supports handling very long texts, automatically splitting long texts into smaller segments and generating speech in sequence—ideal for producing long-form audio content.
Batch Processing: Users can set the batch size to improve inference speed for long texts.
Refiner: This tool allows you to fine-tune the text to optimize the generated speech, which is particularly useful for handling texts of unlimited length.
Voice Enhancement: Integrates an enhancement model to improve the quality of generated speech and make it sound more natural.
Generation History: Saves the latest 3 generation results, making it easy for users to compare voice effects under different settings.
Multi-Model Support: The WebUI supports multiple TTS models, including ChatTTS, CosyVoice, FishSpeech, GPT-SoVITS, etc., allowing users to choose the model that best suits their needs.
SSML Support: Uses the XML-like SSML syntax to control the speech synthesis process, suitable for scenarios requiring more complex controls.
Podcast Tool: Helps users create long-form, multi-character audio content from blog scripts.
Subtitle Generation: Creates SSML scripts from subtitle files to generate various voice content.
GitHub: https://github.com/lenML/ChatTTS-Forge
Online Experience: https://huggingface.co/spaces/lenML/ChatTTS-Forge














