
 Script Planner Assistant▸
 AI Apps
 AI News
CosyVoice: Natural, Human-Like Speech
CosyVoice: Natural, Human-Like SpeechIntroduction
CosyVoice is a speech generation large model based on speech quantization encoding, a new speech synthesis technology that deeply integrates text understanding and speech generation.It performs discrete encoding on speech and, relying on large model technology, achieves a natural and smooth speech generation experience. Compared with traditional speech generation technologies, CosyVoicecan accurately parse and interpret various types of text content, converting it into natural speech that sounds like a real person.
You only need to provide 3~10s of original audio, and CosyVoice can generate a simulated voice, including details such as prosody and emotion, and supports cross-lingual speech generation.
CosyVoice Project Website:https://www.modelscope.cn/studios/iic/CosyVoice-300M
CosyVoice Source Code Address:https://github.com/FunAudioLLM/CosyVoice
CosyVoice API Address:https://help.aliyun.com/zh/model-studio/developer-reference/cosvoice-large-model-for-speech-synthesis/?spm=a2c4g.11186623.0.0.56f01751Ke29mh
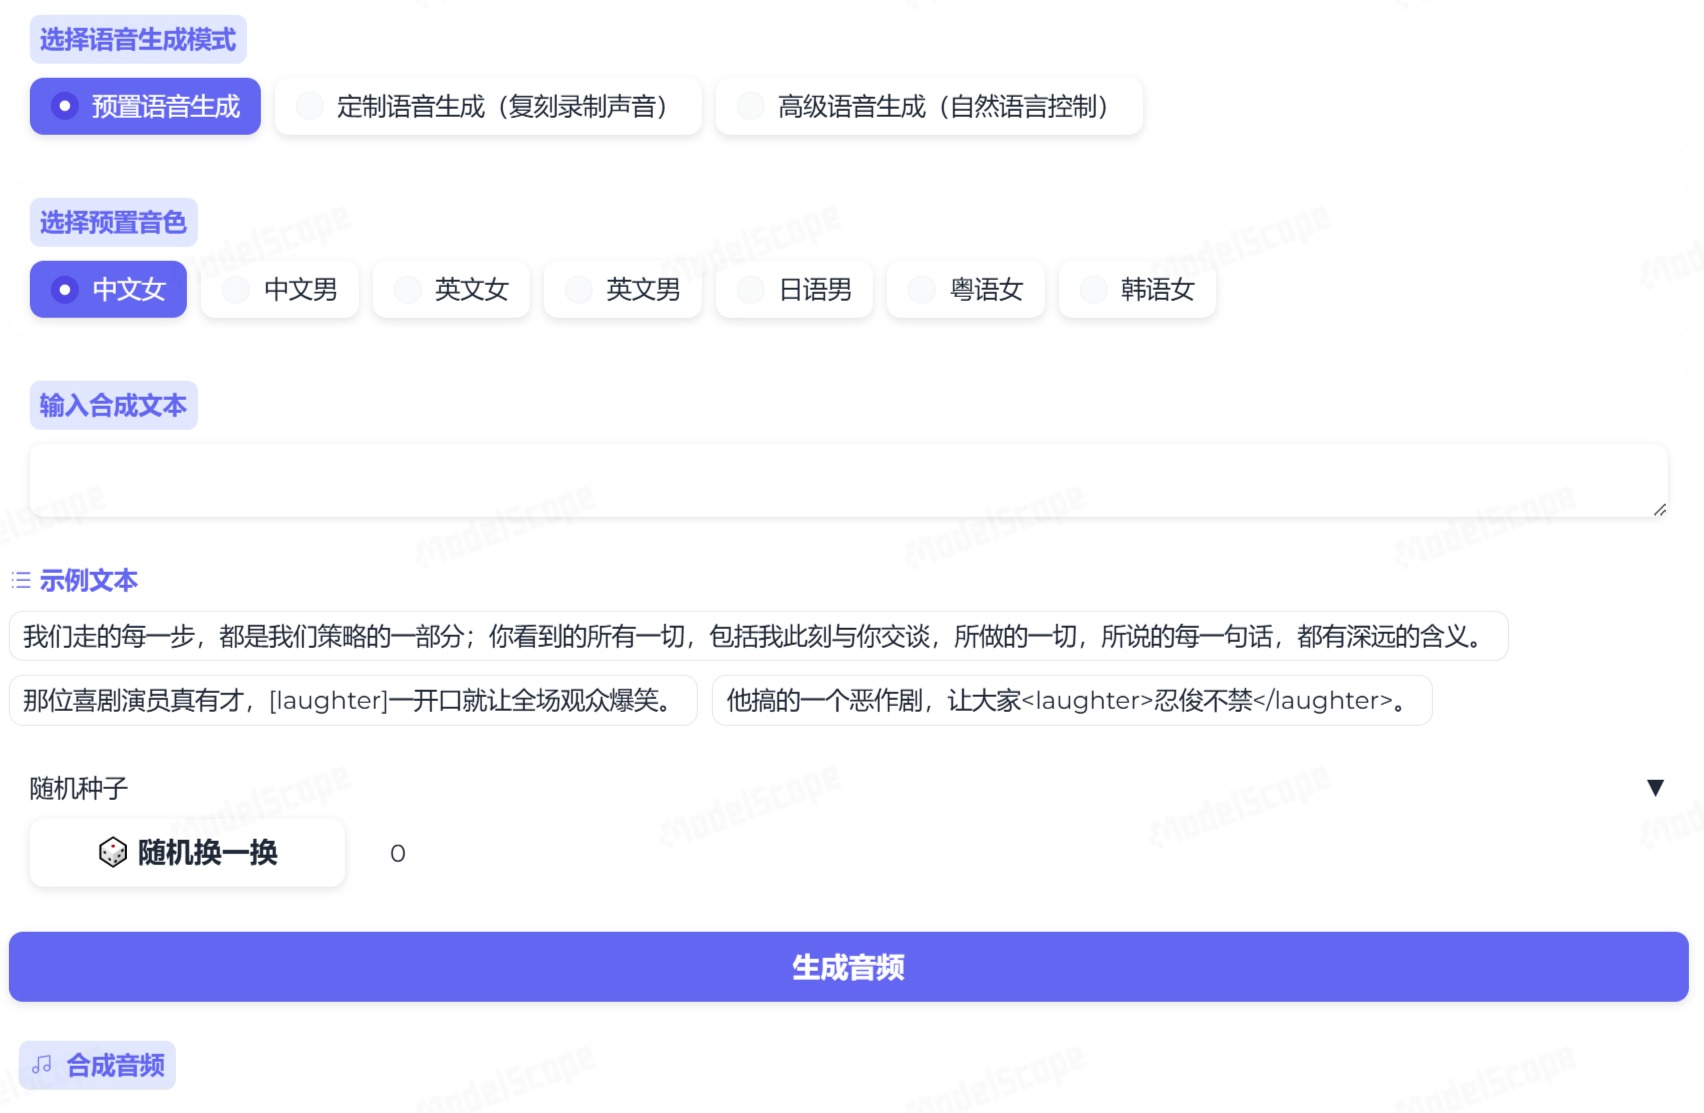
CosyVoice Features:
Highly Human-like: Adopting the CosyVoice generative neural network speech large model algorithm independently developed by Alibaba Tongyi Speech Laboratory, the generated speech achieves an ultra-human-like level in terms of intonation, prosody, and emotional expression.
Multilingual: CosyVoice supports generation in 5 languages including Chinese, English, Japanese, Cantonese, and Korean. Focused on natural speech generation, it supports multi-language, voice, and emotion control, with effects significantly superior to traditional speech generation models.
Diverse Voice Options: Provides a massive amount of high-quality voice library resources, including different genders, ages, dialects, and various characteristic voices, meeting the personalized needs of users in different scenarios. Whether it is the solemnity of news broadcasting or the emotional richness of story narration, it can handle them with ease.
Real-time Efficient Synthesis: The system has excellent response speed and streaming speech synthesis processing capabilities, enabling fast and accurate real-time speech synthesis for both long documents and short sentence commands.
Emotion and Prosody Control: CosyVoice supports rich linguistic sound events and multi-emotion highly human-like speech generation, such as laughter, interjections, etc., as well as highly human-like speech generation with different emotional expressions.
Voice Cloning: You only need to provide 3~10s of original audio, and CosyVoice can clone and generate a simulated voice, including details such as prosody and emotion, and supports cross-lingual speech generation.
CosyVoice Applications:
CosyVoice is suitable for a variety of application scenarios, such as intelligent customer service, audiobooks, in-car navigation, educational tutoring, etc.
Voice content broadcast by smart devices/robots, such as intelligent customer service robots, smart speakers, digital humans, voice assistants, etc.
Scenarios where text needs to be converted to speech broadcasting in audio and video creation, such as novel reading, news broadcasting, film and television commentary, script dubbing, etc.
CosyVoice greatly expands the possibilities of voice interaction, enhances user experience, and also provides strong support for enterprise intelligent transformation.
Compared with the recently popular ChatTTS, it can be found that CosyVoice's synthesized audio has higher content consistency. CosyVoice performs fine-grained control over the emotion and prosody of generated speech, significantly improving the emotional expressiveness of the generated audio, and there are very few hallucination issues with extra characters. CosyVoice models the semantic information in the synthesized text well, surpassing humans in content consistency and speaker similarity.














