
 Script Planner Assistant▸
 AI Apps
 AI News

VASA-1: Transform Photos into Videos
VASA-1: Transform Photos into VideosIntroduction
A single portrait photo + voice audio = real-time generated hyper-realistic talking face video, with precise lip-sync, lifelike facial behavior, and natural head movement. VASA-1 is a cutting-edge artificial intelligence technology developed by Microsoft Research Asia, capable of converting a single static image and a voice audio clip into lifelike conversational facial animations. This technology achieves the generation of videos with rich expressions and dynamic facial behaviors through precise audio-to-lip synchronization and the capture of a large number of subtle facial expressions and natural head movements.
VASA-1 can combine a single static image with an audio file to generate videos with dynamic facial expressions and head movements, making the person in the picture appear to "come alive." This technology can use not only AI-generated portrait images but also real photos, such as images of the U.S. president, to animate them and make them speak.
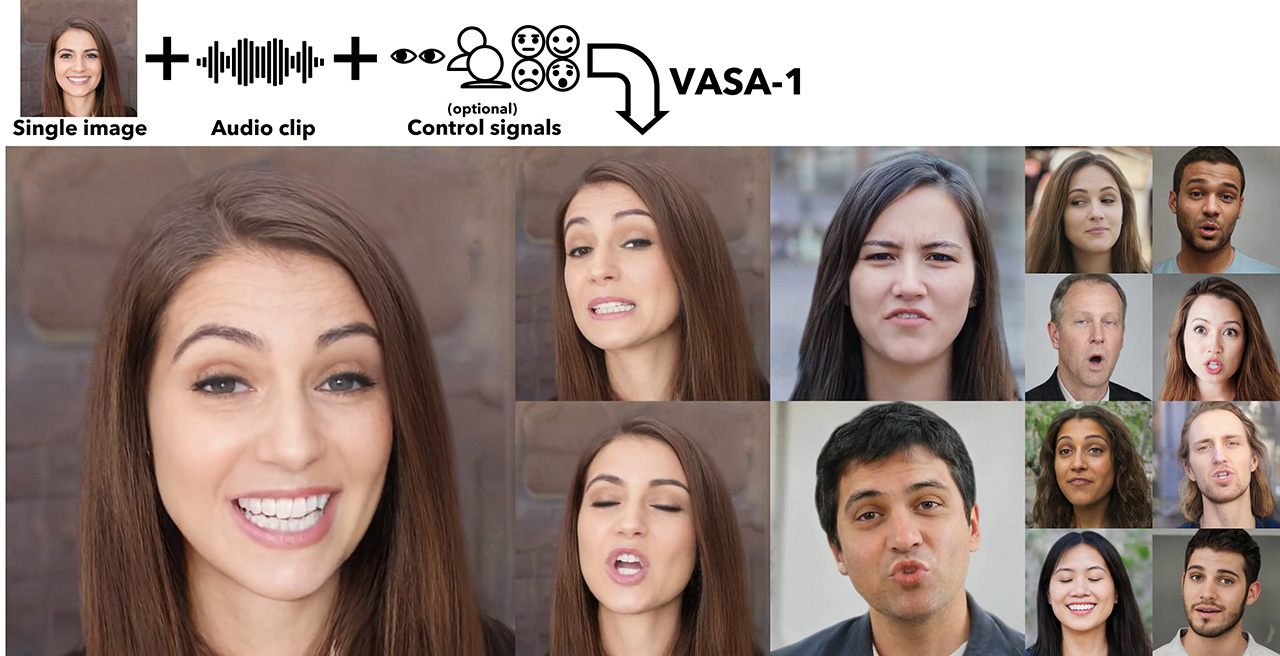
Key Features of VASA-1:
Lifelike lip synchronization: VASA-1 can generate lip movements precisely synchronized with the input voice audio, providing highly realistic talking effects.
Disentanglement capability: VASA-1 has the ability to independently control facial dynamic features such as lip movements, expressions, and eye gaze direction.
Security and surveillance: VASA-1 technology can also be applied in the security and surveillance field.
Facial latent space construction: Generates dynamic facial expressions and head movements by constructing a facial latent space.
High image generation quality and efficient runtime: VASA-1 achieves realistic real-time talking faces, with high image generation quality and efficient runtime.
3D technology-assisted facial landmarking: Microsoft also uses 3D technology to assist in marking facial features and designs additional loss functions, which enables VASA-1 not only to generate high-quality facial videos but also to effectively capture and reproduce the 3D facial structure.
Through its advanced deep learning architecture and the application of multiple cutting-edge technologies, VASA-1 achieves highly realistic audio-driven conversational facial animations, including but not limited to lip synchronization, rich facial expressions, disentanglement capability, security and surveillance applications, high image generation quality and efficient runtime, as well as effective facial 3D structure capture and reproduction.
VASA-1 is an innovative AI tool that ultimately generates lifelike videos by combining static images or paintings with audio files. This process leaves almost no artificial traces, making the generated videos look very natural. Although the researchers acknowledge that, like all other models, VASA-1 currently cannot properly handle non-rigid elements such as hair, its overall performance is superior to other similar models.
The powerful capabilities of VASA-1 also bring potential risks, especially the possibility of being misused to create deepfake videos that can convincingly impersonate real people, making it difficult to distinguish truth from falsehood. Microsoft Research Asia has taken a cautious approach before releasing VASA-1. They have not disclosed any online demos, APIs, products, or related implementation details, to ensure that the technology will not be misused, and they are actively researching how to prevent bad actors from using VASA-1 for improper activities.












