
 Script Planner Assistant▸
 AI Apps
 AI News
Etna: A Text-to-Video AIGC Model
Etna: A Text-to-Video AIGC ModelIntroduction
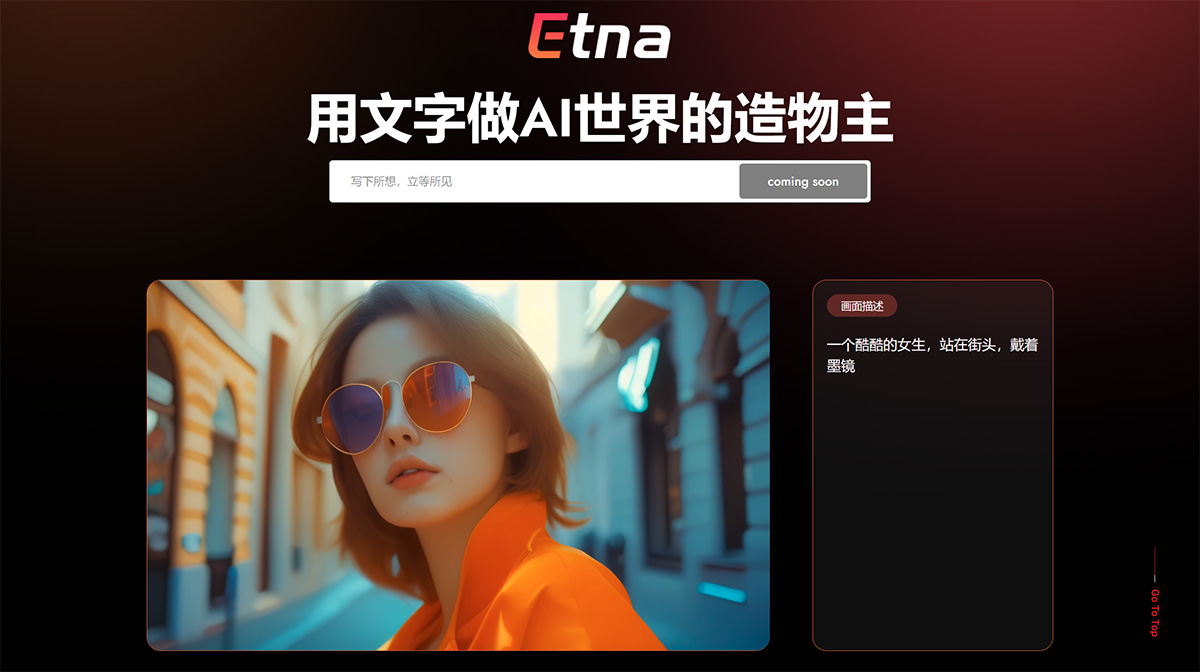
The Etna model is an advanced text-to-video model software developed by 7Volcanoes, featuring in-depth research and applications in natural language processing, generative adversarial networks, and computer vision technologies.
The Etna model adopts the latest neural network architecture, cleverly integrating the semantic understanding capabilities of the Transformer model with the content generation strategy of the Diffusion model, achieving efficient conversion from text to video. This model supports generating videos with a duration of 8-15 seconds, with extremely high video fluency, reaching up to 60 frames per second.
Technical Features of the Etna Model:
Uses the latest neural network architecture
Integrates the semantic understanding capabilities of the Transformer model with the content generation strategy of the Diffusion model
Supports efficient conversion from text to video
Application Scenarios of the Etna Model:
The application scenarios of the Etna model are very broad, including but not limited to video content creation, game development, art and entertainment, as well as education and training.
Video Content Creation: Films, animations, advertisements, and social media platforms
Game Development: Creating in-game animations and scenes
Art and Entertainment: Creating unique visual art works
Education and Training: Producing educational videos to enhance learning interest and effectiveness
These application scenarios demonstrate the broad application potential and innovative capabilities of the Etna model across different fields.
Etna Model FAQs:
What can Etna do?
The Etna model from 7Volcanoes is a text-to-video AIGC model that can generate corresponding video content based on brief textual descriptions.
What technical architecture does Etna adopt?
The current backbone network of the Etna model uses the Diffusion architecture, while simultaneously experimenting with and adapting a Sora-like Diffusion+Transformer architecture on a larger dataset.
What is the technical principle behind Etna?
The Etna model inserts spatiotemporal convolution and attention layers between the language model and the image model, enabling it to process video data by considering the temporal continuity in image sequences. This means that Etna possesses a certain degree of spatiotemporal understanding capability, allowing it to understand and generate video content with a temporal dimension.
How is the Etna model trained?
The Etna model is fully trained on a large-scale video dataset using advanced deep-learning technology strategies, including large-scale LDS training, complex HPO hyperparameter optimization, and DPO fine-tuning, ensuring the model's powerful performance and generation capabilities.
As an important innovative achievement of 7Volcanoes in the field of AI video technology, the Etna model achieves efficient conversion from text to high-quality video by combining the latest neural network architecture and technical strategies, demonstrating broad application scenarios and commercial potential.












