
 Script Planner Assistant▸
 AI Apps
 AI News
DreamTalk: Open-Source Framework for Making Portrait Photos Talk
DreamTalk: Open-Source Framework for Making Portrait Photos TalkIntroduction
DreamTalk is a framework developed jointly by Tsinghua University, Alibaba, and Huazhong University of Science and Technology. Based on a diffusion model, it can make portrait photos talk and supports various sounds for matching the portrait head to speak, including songs, multilingual speech, and noisy audio.
DreamTalk demo URL:https://dreamtalk-project.github.io
DreamTalk project URL:https://dreamtalk-project.github.io/
DreamTalk paper URL:https://arxiv.org/abs/2312.09767
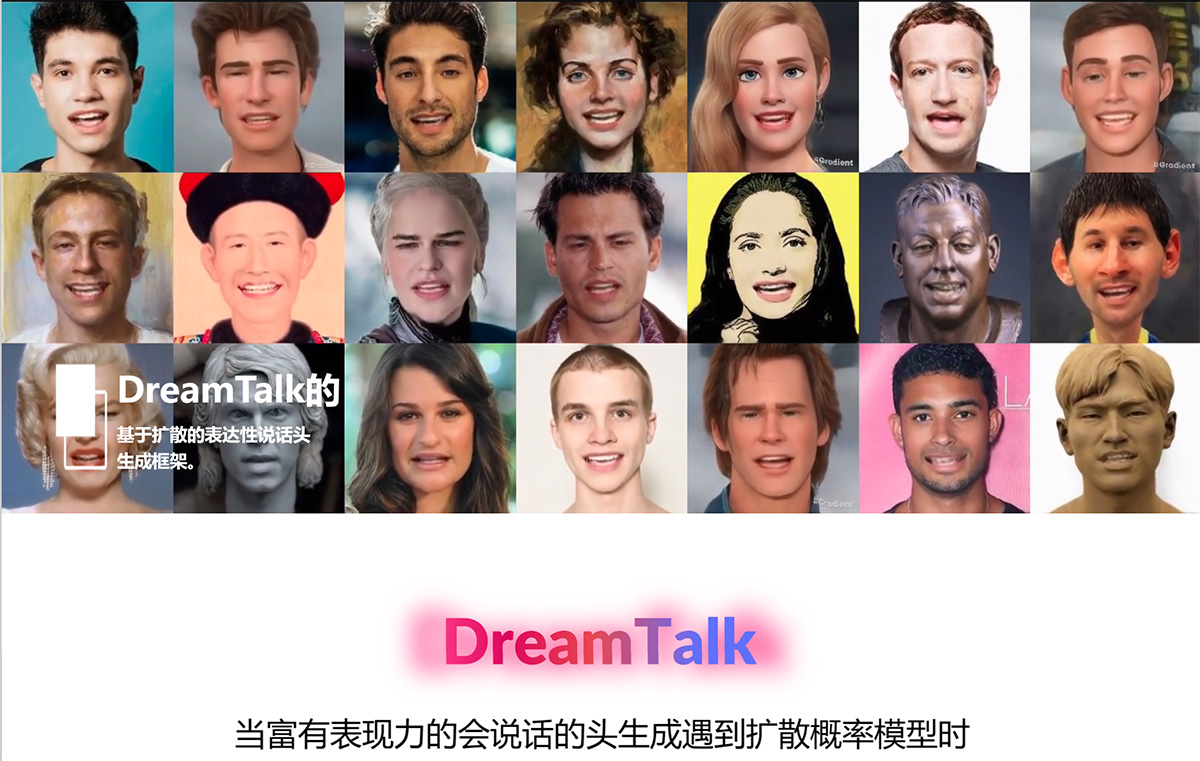
DreamTalk use cases:
Use DreamTalk to generate talking faces with diverse languages and expression styles
Apply DreamTalk in film and television production to achieve realistic virtual character expressions and movements
Use DreamTalk to achieve natural facial expressions and lip movements in human-computer interaction scenarios
DreamTalk features:
Specifically, DreamTalk consists of three key components: a denoising network, a style-aware lip expert, and a style predictor. The diffusion-based denoising network is capable of consistently synthesizing high-quality audio-driven facial motions across different expressions. To improve the expressiveness and accuracy of lip movements, we introduce a style-aware lip expert that can guide lip synchronization while attending to speaking style. To eliminate the need for expression reference videos or text, an additional diffusion-based style predictor is used to directly predict the target expression from audio.
1. Denoising network: This is one of the core components, responsible for generating audio-driven facial motions. The denoising network uses a diffusion model to progressively remove noise, thereby generating clear, high-quality facial expressions. This process involves progressively restoring clear facial motions from noisy data.
2. Style-aware lip expert: This component focuses on improving the expressiveness and accuracy of lip movements. It guides lip synchronization by analyzing speaking style, ensuring that the generated animation is both natural and consistent with the speaker's style.
3. Style predictor: To eliminate the dependence on expression reference videos or text, DreamTalk introduces a diffusion-based style predictor. This predictor can directly predict the target expression from audio, without the need for additional expression reference videos or text.
4. Audio and video processing: It processes audio input, extracts key audio features, and uses these features to drive facial animation. At the same time, it can also process video input to extract and mimic specific expressions and styles.
5. Data and model training: To achieve these features, DreamTalk requires a large amount of data to train its models, including facial animation data with different expressions and speaking styles. Through this data, the model learns how to accurately generate facial motions that match the input audio.
DreamTalk can leverage the powerful diffusion model to effectively generate expressive faces while reducing the dependence on expensive style references. Experimental results show that DreamTalk is able to generate realistic talking faces with different speaking styles and achieve accurate lip movements, surpassing existing state-of-the-art counterparts.
DreamTalk can not only handle and generate the facial types and expressions it has seen during training, but also effectively handle and generate facial types and expressions from different datasets that it has not seen before.
Including portraits of people of different races, ages, and genders, as well as a variety of different expressions and emotions.














