
 Script Planner Assistant▸
 AI Apps
 AI News
Zidong Taichu Large Model
Zidong Taichu Large ModelIntroduction
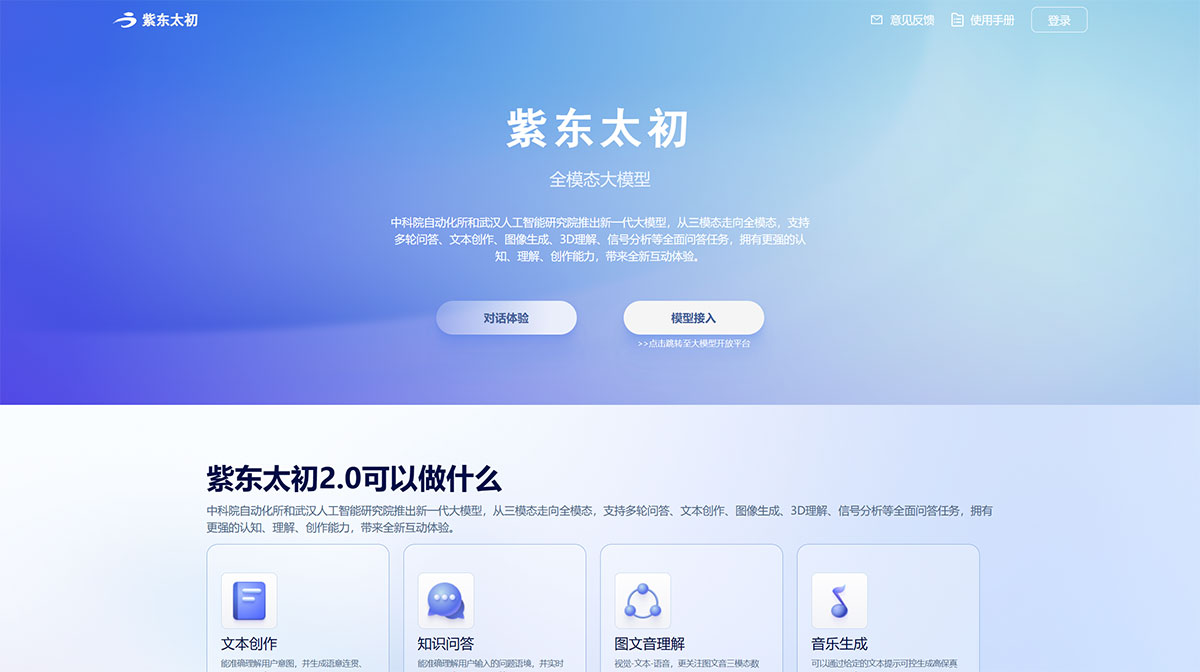
Taichu (Purple East Taichu), launched by the Institute of Automation of the Chinese Academy of Sciences and the Wuhan Artificial Intelligence Research Institute, is a new-generation large model that evolves from tri-modal to fully omni-modal capabilities. It supports comprehensive Q&A tasks such as multi-turn dialogue, text creation, image generation, 3D understanding, and signal analysis, offering stronger cognition, understanding, and creative capabilities to deliver a brand-new interactive experience.
What Can Taichu Large Model 2.0 Do
The Institute of Automation of the Chinese Academy of Sciences and the Wuhan Artificial Intelligence Research Institute have launched a new-generation large model that evolves from tri-modal to fully omni-modal capabilities. It supports comprehensive Q&A tasks such as multi-turn dialogue, text creation, image generation, 3D understanding, and signal analysis, offering stronger cognition, understanding, and creative capabilities to deliver a brand-new interactive experience.
Text Creation
It can accurately understand user intent and generate coherent, logically smooth text content. It covers common text creation scenarios such as: writing article reflections, job descriptions (JDs), letters, emails, invitation letters, itinerary planning, and more.
Knowledge Q&A
It can accurately understand the context of user-asked questions and provide real-time knowledge-based answers, including: everyday life knowledge, work skills, medical knowledge, history and humanities, and more.
Image, Text, and Audio Understanding
Vision–text–speech: with greater focus on the relational characteristics among image, text, and audio data, providing a foundational model for a wider and more diverse range of downstream tasks.
Music Generation
It can controllably generate high-fidelity music based on given text prompts, and supports improvised creation of music in multiple styles performed by multiple instruments.
3D Understanding
Provides 3D scene understanding and object perception capabilities based on point cloud data.
Signal Analysis
Supports radar signal identification and knowledge interaction, enabling users to quickly grasp the basic source and parameters of signals with model assistance.
Overview of Taichu Large Model Features
"Taichu 2.0" aims to pursue more comprehensive Q&A capabilities, richer expression capabilities, and multi-turn multi-modal Q&A capabilities, to meet dialogue and creation needs in more complex business scenarios.
1. Image Capabilities
Image DescriptionCapability Description: "Taichu 2.0" can accurately understand and answer image recognition questions based on user-uploaded image materials. Specifically, it can identify the subject, background, actions, colors, etc. of an image. It also supports contextual information understanding and multi-turn dialogue.
Example Commands:
Upload an image, then send "Please describe what is in this image"
Upload an image, then send "Please describe what colors are present in this image"
2. Object Detection
Capability Description: "Taichu 2.0" supports object detection tasks across a rich variety of categories, and can determine the object type, quantity, and corresponding location information.
Example Commands:
Upload an image, then send "How many people are in the image"
Upload an image, then send "Help me see how many types of animals are in the image"
3. Image Retrieval
Capability Description: "Taichu 2.0" has a massive library of high-quality image materials, and can search for refined images with high relevance to the user.
Example Commands:
"Help me find an image of cherry blossoms in full bloom"
"Help me find a picture of Shanghai's night view"
"What does a car look like? Show me an image"
4. Image Generation
Capability Description: "Taichu 2.0" can generate refined images based on user instructions, and can fine-tune image content by modifying the description. Prompt Tip: Adding concrete descriptions of the subject's features helps anchor the core scene content; adding style or other feature descriptors helps adjust the overall effect of the image.
Example Commands:
"Draw an image of cherry blossoms in full bloom in a beautiful style"
"Generate a photo of a puppy playing on the grass"
"Help me draw an image of a tiger swimming"
5. Text Recognition
Capability Description: "Taichu 2.0" supports text detection and recognition services across multiple scenarios and languages with high accuracy. Specific business scenarios include: card and certificate text recognition, receipt text recognition, document image processing, and more.
Example Commands:
Upload an image, then send "What text is in the image"
Upload an image, then send "Help me recognize all the text in the image"
6. Language Capabilities
Chinese Q&A
Capability Description: "Taichu 2.0" can accurately understand the context of user-asked questions and provide accurate knowledge-based answers, including: everyday life knowledge, work skills, medical knowledge, history and humanities, and more.
Example Commands:
"Let me quiz you, what are the Four Great Classical Novels"
"Excuse me, what is the highest mountain in the world"
"What is stomach disease, what are the common types, and what are the treatment methods?"
"How should personal finances and budget planning be arranged?"
7. Text Summarization
Capability Description: "Taichu 2.0" can quickly grasp the core point of an article and extract a concise and accurate summary from long-form text.
Example Commands:
"Help me extract a summary of the article" + input article content
"Help me condense this article" + input article content
8. Text Continuation
Capability Description: "Taichu 2.0" can automatically continue and enrich story content based on user-provided story prompts.
Example Commands:
"Please continue the story: Once upon a time, there were 3 old monks living on a mountain"
9. Text Creation
Capability Description: "Taichu 2.0" can accurately understand user intent and generate coherent, logically smooth text content. It covers common text creation scenarios such as: writing article reflections, job descriptions (JDs), letters, emails, invitation letters, itinerary planning, and more.
Example Commands:
"Help me write a 200-word press release for an AI large model launch event"
"Write a job description (JD) for an Internet AI Product Manager"
"Write a reflection on 'The Three-Body Problem'"
"Please help me make a 3-day itinerary for a trip to Wuhan"
"Write a thank-you letter to the Wuhan Municipal Government"
10. Title Generation
Capability Description: "Taichu 2.0" can quickly aggregate and generate concise, summarizing title copy based on its understanding of an article or long-form text.
Example Commands:
"Please generate a title for this article:" + input article content
11. Grammar Analysis
Capability Description: "Taichu 2.0" can accurately understand and analyze the grammar of Chinese and English text material uploaded by users, alerting them to grammar errors and correcting them.
Example Commands:
Please correct this sentence into proper grammatical form: "General Manager Zhang and Chief Engineer Li are discussing a technical retrofit project, he agrees with his view."
Please identify the errors in the sentence and rewrite it correctly: "A number of students is going to learn a foreign language."















