
 Script Planner Assistant▸
 AI Apps
 AI News
DeepSeek V4 Pro vs Kimi K3: Which Is China’s Best AI Model in 2026?
小编 ·

DeepSeek V4 Pro vs Kimi K3: Which Is China’s Best AI Model in 2026?
On the evening of August 12, DeepSeek-V4-Pro was released. DeepSeek-V4-Pro and Kimi K3 are currently two top representatives among domestic large models. DeepSeek-V4-Pro pursues the ultimate in cost-effectiveness and speed, while Kimi K3 aims to push the performance ceiling, truly earning its reputation as a "performance beast." The following is based on the latest third-party evaluations and official data from August 2026.
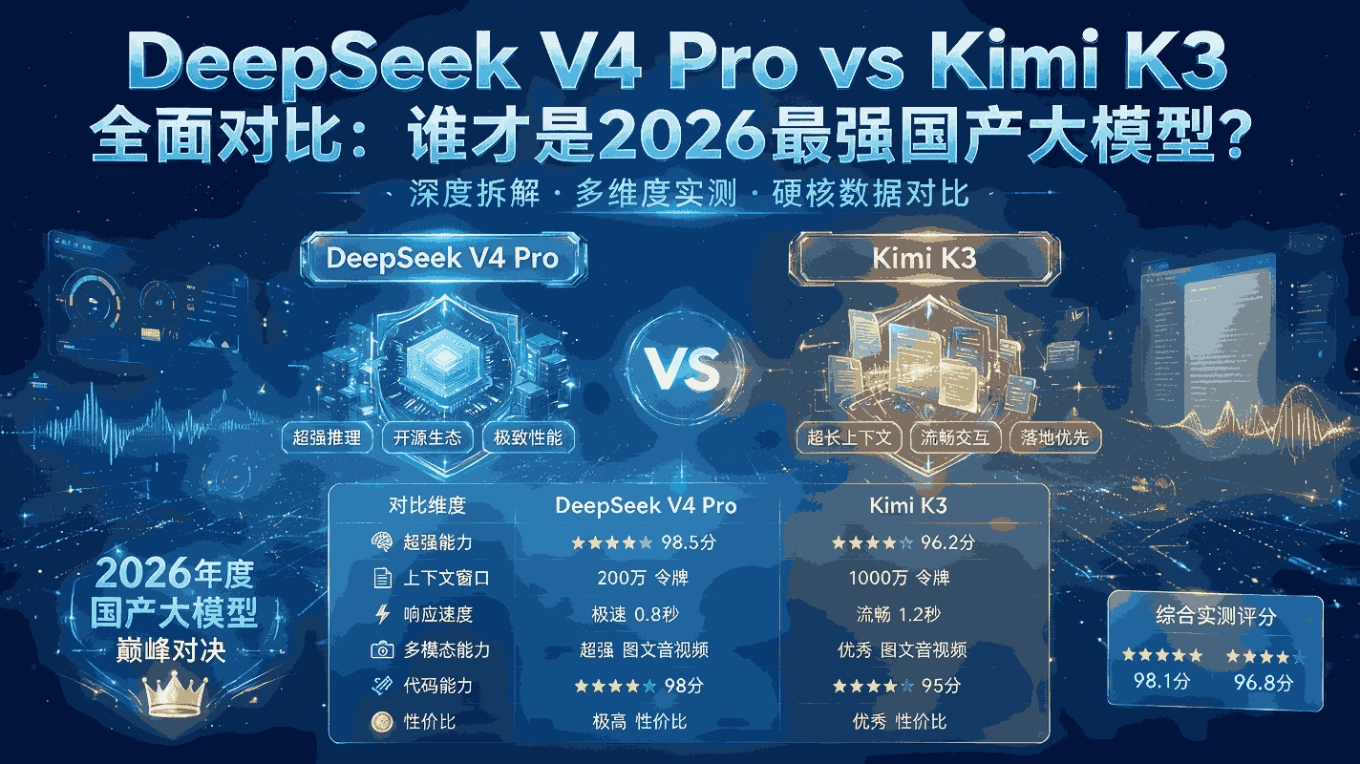
Core Specifications Comparison
| Dimension | DeepSeek V4 Pro | Kimi K3 |
|---|---|---|
| Publisher | DeepSeek | Moonshot AI |
| Release Date | April 24, 2026 (Preview) | July 16, 2026 |
| Total Parameters | 1.6 trillion | 2.8 trillion (world's largest open-source model) |
| Activated Parameters | ~49 billion | ~104 billion (select 16 from 896) |
| Context Window | 1 million tokens | 1.048 million tokens |
| Max Output | 384,000 tokens | Not disclosed (typically limited by context) |
| Architecture | MoE (Mixture of Experts) | MoE + KDA Hybrid Linear Attention + Attention Residuals |
| Multimodal | ❌ Text only | ✅ Native text/image/audio/video |
| Open Source Status | Pro weights not disclosed (closed source) | ✅ MIT license, full weights released |
| Reasoning Mode | Thinking / Non-thinking optional | Thinking always enabled (maximum effort) |
| Concurrency Limit | 500 | Not disclosed |
Benchmark Performance Comparison
Cross-validated data from third-party platforms LMSpeed and BenchLM is as follows:
| Evaluation Dimension | Kimi K3 | DeepSeek V4 Pro | Gap |
|---|---|---|---|
| Overall Average Score (LMSpeed) | 63.4 | 47.4 | K3 leads by 16 points |
| Agentic Tasks | 68.9 | 51.4 | K3 leads by 17.5 |
| Coding Capability | 59.6 | 48.0 | K3 leads by 11.6 |
| Knowledge Reasoning | 61.9 | 43.6 | K3 leads by 18.3 |
| Reasoning Capability | 58.8 | 53.8 | K3 leads by 5.0 |
| GPQA Diamond | 93.5% | 90.5% | K3 leads by 3.0% |
| Terminal-Bench 2.1 | 88.3 | 64.0 | K3 leads by 24.3 |
| AA Coding Index | 76.2 | 59.4 | K3 leads by 16.8 |
| BenchLM Total Score | 83.0 (#2/93) | 65.0 (#25/93) | K3 leads by 18 points |
| Artificial Analysis Intelligence Index | 57.1 (Global #4) | 44.3 (#21) | K3 leads by 12.8 |
| Hallucination Rate (lower is better) | 50.9% | 94.0% | V4 Pro is more reliable |
| Frontend Coding (Code Arena) | 1679 Elo (#1) | Not top-ranked | K3 leads |
As shown above, Kimi K3 significantly leads in the vast majority of dimensions including coding, Agent, and knowledge reasoning; DeepSeek V4 Pro's advantage lies in better hallucination control (higher knowledge accuracy) and faster response speed.
API Pricing Comparison
This is where the gap between the two is the largest:
| Pricing Item | DeepSeek V4 Pro | Kimi K3 | K3 Premium Multiple |
|---|---|---|---|
| Cache Hit Input | $0.003625 | $0.30 | ~83× |
| Cache Miss Input | $0.435 | $3.00 | ~7× |
| Output | $0.87 | $15.00 | ~17× |
Typical Workload Cost Estimates, from BenchLM
| Scenario | DeepSeek V4 Pro | Kimi K3 |
|---|---|---|
| Simple Chat (1K input + 500 output) | $0.00087 | $0.0105 |
| Codebase Review (50K input + 3K output) | $0.024 | $0.195 |
| Agent Loop (200K cache + 20K input + 10K output) | $0.018 | $0.27 |
Speed and Experience
| Metric | DeepSeek V4 Pro | Kimi K3 |
|---|---|---|
| Time to First Token | 1.22 seconds | 2.11 seconds |
| Output Speed | 55.9 tok/s | 40.1 tok/s |
V4 Pro is faster at inference, which is related to its smaller activated parameters and text-only architecture.
How to Choose: Recommendations
If you have the following situations, choose Kimi K3:
You need native multimodal capabilities, such as image understanding, video understanding, audio reading;
You're tackling high-difficulty software engineering, such as FrontierSWE, Terminal-Bench, and similar scenarios;
You need self-hosting or data to stay on-premises;
You're pursuing frontier capabilities and have a relatively ample budget;
You're doing frontend development.
If you have the following needs, choose DeepSeek V4 Pro:
You're cost-sensitive (price is only 1/7 to 1/17 of K3);
You need high-frequency Agent workflow calls;
You have requirements for response speed;
Your tasks are primarily text-based;
You need knowledge Q&A with a low hallucination rate.









