
 Script Planner Assistant▸
 AI Apps
 AI News
DeepSeek-V4 Performance Explosion: 1M Context + Huawei Ascend Support
小编 ·

DeepSeek-V4 Performance Explosion: 1M Context + Huawei Ascend Support
DeepSeek-V4 is a large language model series officially released and open-sourced on April 24, 2026, including two versions: DeepSeek-V4-Pro and DeepSeek-V4-Flash. The series features million-level (1M) ultra-long context, achieving leading performance in both China and the open-source community in Agent capabilities, world knowledge, and reasoning performance. The model has been deeply adapted for Huawei Ascend chips.
🚀 Core Highlights
Million-level context as standard: Both versions support 1 million tokens of ultra-long context, offered as a standard configuration in the official service. This is made possible by a new attention mechanism (hybrid attention CSA+HCA), which reduces computational and memory requirements.
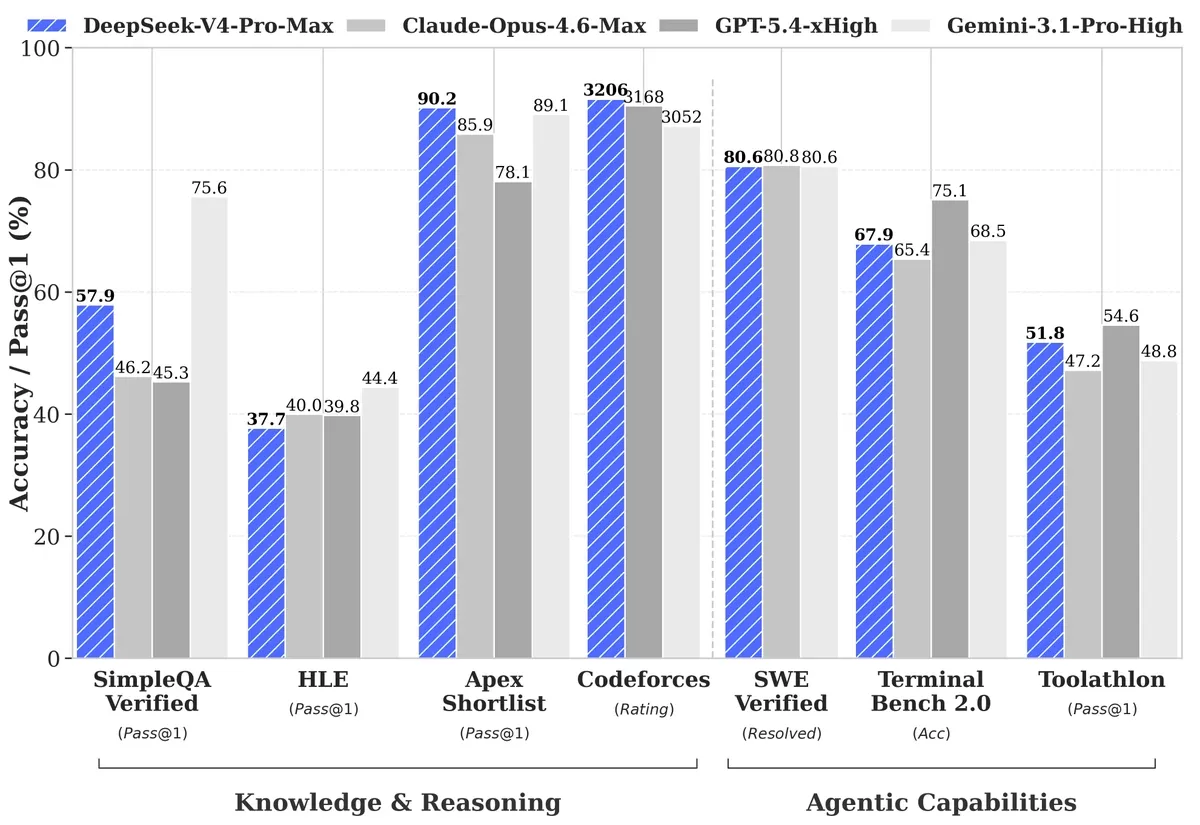
Outstanding reasoning and knowledge performance: DeepSeek-V4-Pro surpasses all publicly benchmarked open-source models in math, STEM, and competitive coding evaluations, with performance approaching that of top-tier closed-source models. Its world knowledge reserves also clearly lead among open-source models.
Enhanced Agent capabilities: V4-Pro's Agent capability reaches the best level among open-source models in Agentic Coding evaluations, with a user experience superior to Sonnet 4.5 and delivery quality approaching the non-thinking mode of Opus 4.6. The model has also been specially optimized for mainstream Agent products such as Claude Code and OpenClaw.
Adapted for domestic hardware: DeepSeek-V4 will run on Huawei's latest Ascend chips, with engineers having completed the underlying migration from NVIDIA CUDA to Huawei's CANN architecture. Cambricon has also completed adaptation for the V4 series.
🤔 How to Choose Between the Two Versions?
The DeepSeek-V4 series offers two versions for different scenarios:
DeepSeek-V4-Pro - Expert Mode
Positioning: Pursuing ultimate performance, benchmarked against top-tier closed-source models.
Features: Richer world knowledge and stronger reasoning capabilities, suitable for complex reasoning, code generation, and Agent tasks.
Parameters: Total parameters 1.6T, activated parameters 49B.
DeepSeek-V4-Flash - Quick Mode
Positioning: A faster and more economical choice
Features: Reasoning capability close to the Pro version, with smaller parameter and activation scales, lower API pricing, and faster response. Performs on par with Pro on simple Agent tasks.
Parameters: Total parameters 284B, activated parameters 13B.
💻 How to Get and Use It?
Open-source weights: Open-sourced simultaneously on Hugging Face and ModelScope.
API calls: The API service has been updated simultaneously. Developers can change the model parameter to deepseek-v4-pro or deepseek-v4-flash to make calls.
Direct use: Log in to the DeepSeek official website or official App to chat directly.
API Pricing
The following is the pricing per million tokens:
| Model Version | Input (cache hit)¥/MTok | Input (cache miss)¥/MTok | Output¥/MTok |
|---|---|---|---|
| DeepSeek-V4-Flash | 0.2 元 | 1 元 | 2 元 |
| DeepSeek-V4-Pro | 1 元 | 12 元 | 24 元 |









