
 Script Planner Assistant▸
 AI Apps
 AI News
ThinkSound: A Multimodal AI Audio Tool from Alibaba's Tongyi Lab
小编 ·

ThinkSound: A Multimodal AI Audio Tool from Alibaba's Tongyi Lab
ThinkSound is a multimodal AI audio tool released by Alibaba's Tongyi Lab. It can generate high-fidelity sound effects and ambient sounds based on video, text, or audio input.
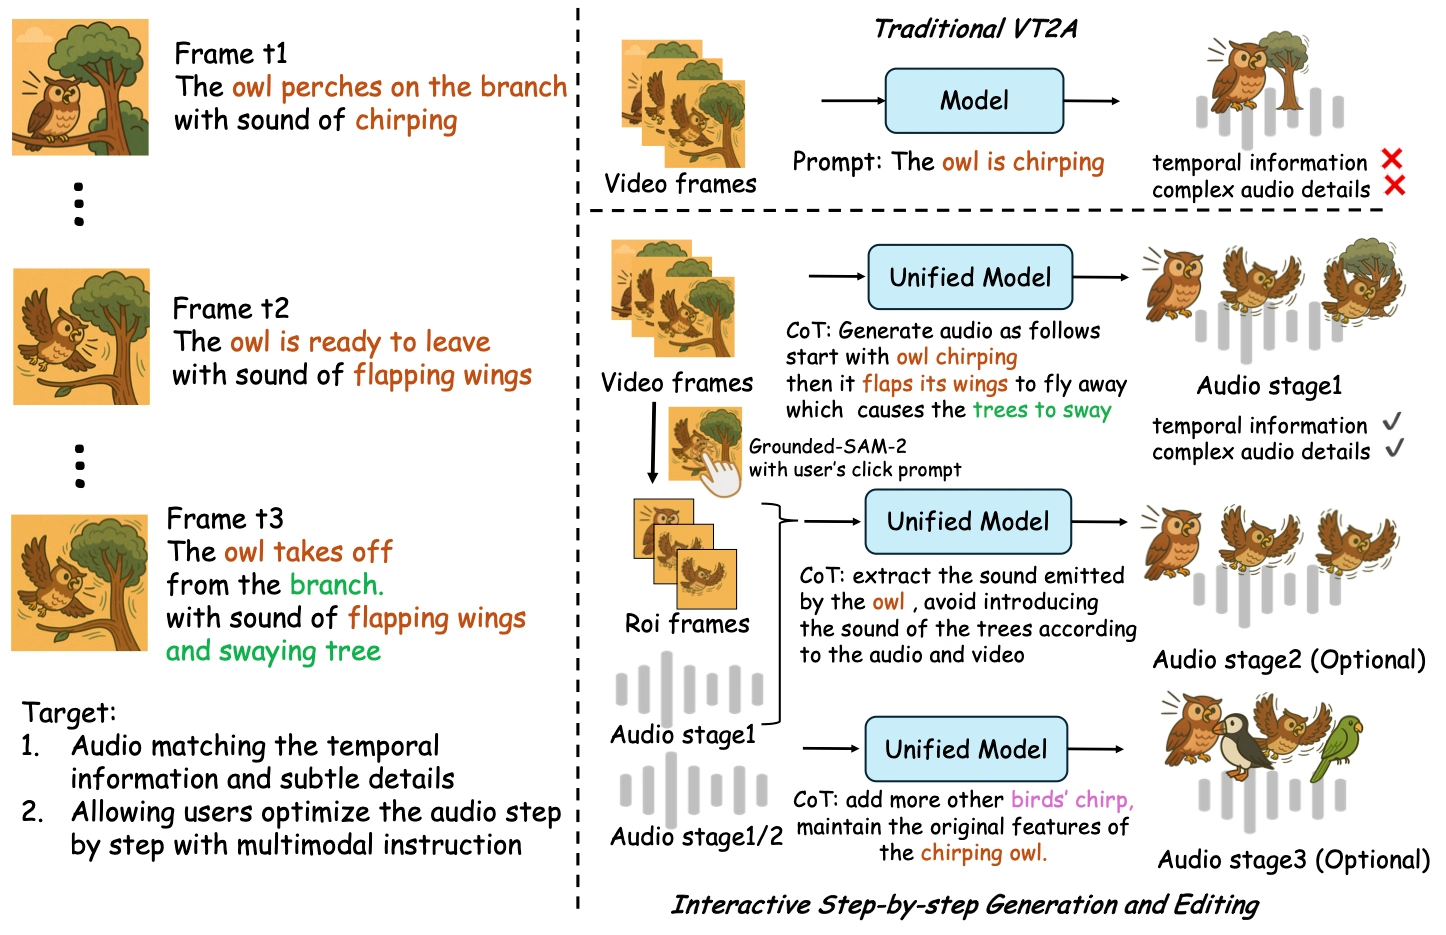
Core Features
✅ Video-to-Audio: Converts any video into rich sound effects that match the visuals. By analyzing frame-by-frame visual elements, motion trajectories, and environmental context, it generates synchronized background sounds and spatial audio effects.
✅ Intelligent Voice Synthesis: Generates natural dialogue and narration based on video content. The AI can recognize facial expressions, lip movements, and emotional context, producing voice output with precise lip-sync, natural intonation, and authentic emotion.
✅ Multimodal Sound Design: Combines video and text instructions, reference sound effects, and style preferences to precisely control sound details, ensuring natural integration with the visuals—suitable for professional production in film, gaming, and more.
✅ Interactive Audio Editing: Users can refine specific sounds by clicking on target objects within the video or by directly entering natural language commands.
Technical Principles
Three-Stage Interactive Framework:
✅ Base Sound Generation: The system first analyzes the video as a whole, using logical reasoning to identify sound events, environmental elements, acoustic characteristics, and temporal relationships, producing an initial coherent background sound scene.
✅ Object Refinement: After the user clicks on a target object, the system extracts the region through localization technology and tracks the object's motion, generating targeted sound logic for that object to refine audio details while maintaining harmony with the overall track.
✅ Instruction Editing: The user enters natural language commands (such as "add bird chirping" or "remove car noise"), and the system converts them into precise audio operations, making adjustments based on the visuals and the current sound state.
✅ Multimodal Large Language Model (MLLM): The core capability is to simultaneously understand video visuals, text descriptions, and sound context, fusing the information to progressively generate natural and realistic sound effects.
Strengths & Features
✅ High audio realism, outstanding performance in video-to-audio generation tests, with strong scene adaptability.
✅ Supports creative customization through detailed prompts while ensuring natural audio-visual synchronization.
✅ Compatible with mainstream video formats (MP4/MOV/AVI/MKV), supports resolutions from SD to 4K and various frame rates.
✅ Designed specifically for professional scenarios (film, advertising, gaming, etc.), with commercial usage licenses included in all versions.
Application Scenarios
✅ Film & Video Post-Production: Quickly generate ambient sound, dialogue, or music for silent footage, boosting production efficiency.
✅ Game Sound Effects: Create dynamic ambient audio to enhance immersion in virtual scenes.
✅ Interactive Media & Education: Achieve multilingual dialogue through voice synthesis, combined with precise lip-sync and emotional expression to make virtual characters more vivid.
Project Links
✅ Github: https://github.com/FunAudioLLM/ThinkSound
✅ Official Website: https://thinksound-demo.github.io/
✅ HuggingFace: https://huggingface.co/spaces/FunAudioLLM/ThinkSound









