
 Script Planner Assistant▸
 AI Apps
 AI News
FantasyPortrait: Emotion-Driven Multi-Character Facial Animation from a Single Image
小编 ·

FantasyPortrait: Emotion-Driven Multi-Character Facial Animation from a Single Image
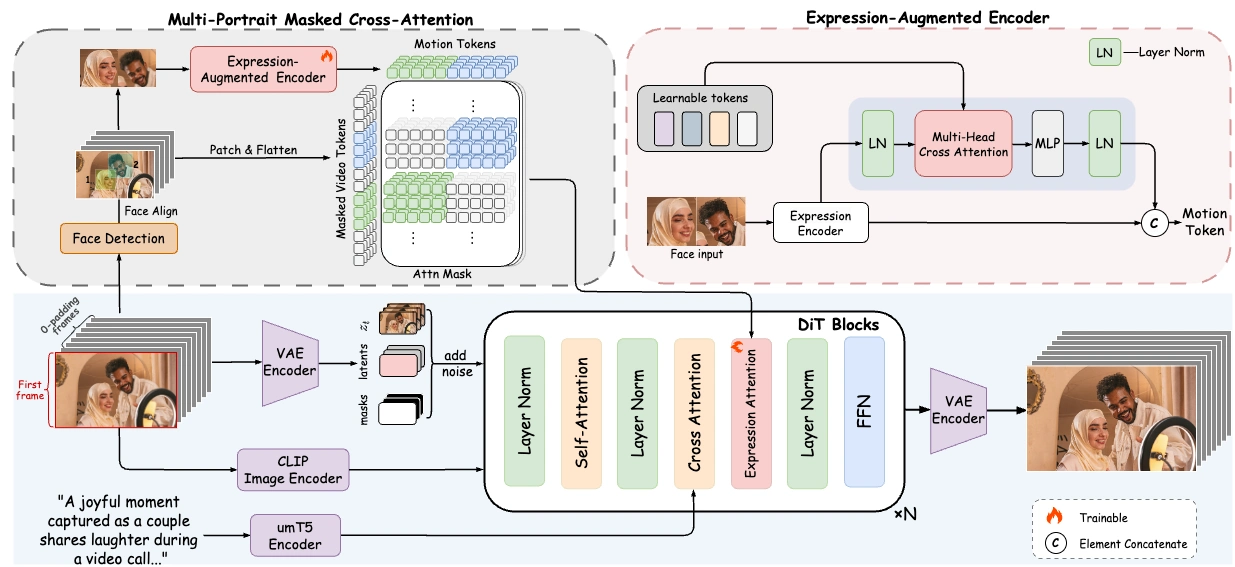
FantasyPortrait is a framework jointly developed by Alibaba's Amap team and Beijing University of Posts and Telecommunications. It can generate emotional facial animations for multiple characters from a single static image. It extracts complex expressions through implicit features, replacing traditional geometric priors to enhance cross-identity transfer capabilities, and uses a masked cross-attention mechanism to avoid feature interference between multiple characters. In addition, it supports multi-style character adaptation, zero-shot animal animation generation, and low-resource audio-driven functionalities, applicable to fields such as digital humans, virtual idols, and game NPCs. The code is open-sourced on GitHub.
Core Features
✅ Implicit Expression Enhancement Learning: Extracts complex expressions such as lip movements and emotional expressions through implicit features, replacing traditional explicit geometric priors to enhance cross-identity transfer capabilities.
✅ Masked Cross-Attention Mechanism: Creates independent expression control regions for multiple characters, avoiding feature interference and achieving coordinated animation with a "one-character-one-channel" approach.
✅ Multimodal Scalability: Supports text and audio driving, such as using Whisper to encode audio for lip-sync animation generation, and can adapt to multiple languages with only a small amount of data fine-tuning.
✅ Datasets and Evaluation Benchmarks: Built the Multi-Expr dataset (30,000+ high-quality multi-character videos) and the ExprBench benchmark, promoting industry standardization.
Method Design Aspects:
✅ Two-Stage Training Strategy: First, expression features are encoded through a UNet, and then animation sequences are decoded through a diffusion transformer.
✅ Multi-Character Control Module: Isolates driving signals of different characters through feature masks, maintaining temporal consistency.
Datasets and Evaluation Benchmarks:
✅ Multi-Expr Dataset: Contains over 500,000 frames of multi-view expression data, making it the first multi-character animation dataset.
✅ ExprBench Evaluation Benchmark: Used for training and evaluating multi-character portrait animation.
Experimental Results Show:
✅ Cross-Driver Reenactment Task: Compared with methods such as StyleHEAT and PIRender, the FID metric is improved by 41.7%.
✅ Multi-Character Animation Generation Scenarios: User preference rate reaches as high as 83.5%, capable of accurately generating subtle expressions such as eye micro-tremors and asymmetric mouth corner movements.
Application Scenarios Include:
✅ Multi-Character Animation: Supports driving multiple characters with multiple single-person videos or a single multi-person video, generating detailed expressions and realistic portrait animations.
✅ Diverse Character Styles: Capable of generating dynamic, expressive, and naturally realistic animations in various styles.
✅ Animal Animation: Although not explicitly trained on animal datasets, it demonstrates strong generalization capabilities in animal animation tasks.
✅ Audio-Driven Portrait Animation: Maps audio features to latent driving representations through audio encoding and a Transformer-based network, enabling audio-driven portrait animation with good audio-visual alignment achievable with a small number of training samples.
Key Questions Answered:
What are the technical breakthroughs?
Answer: First, enhanced implicit expression control, which learns fine-grained expression features through implicit facial representations to improve mouth movement and emotional expression modeling capabilities; second, multi-character masked cross-attention, an innovative masked cross-attention mechanism that achieves independent control and collaborative generation of multiple characters, solving the problem of feature interference between characters.
What are the functional features?
Answer: Includes multi-character synchronous driving, supporting synchronous driving of multiple characters with a single or multiple single-person videos and a multi-person video; multi-style character adaptation, capable of generating dynamic, smooth, vivid, natural, and stylistically unified videos for characters in different artistic styles; zero-shot animal animation, with excellent generation capabilities even without specialized training; low-resource audio driving, extensible to an audio-driven framework that utilizes Whisper to encode audio and maps audio features to latent driving space through a lightweight Transformer network.
What are the application values?
Answer: In film and television production, it enables independent animators to easily generate group performance scenes; in the gaming field, it allows NPCs to display thousands of unique micro-expressions; in virtual live streaming, it makes multi-character interactions more vivid and natural.
Open Source Information:
GitHub Repository: https://github.com/Fantasy-AMAP/fantasy-portrait
Project Official Website: https://fantasy-amap.github.io/fantasy-portrait/









