
 Script Planner Assistant▸
 AI Apps
 AI News
MultiTalk: Meituan's Open-Source Audio-Driven Multi-Person Conversation Video Generator
小编 ·

MultiTalk: Meituan's Open-Source Audio-Driven Multi-Person Conversation Video Generator
MultiTalk is an audio-driven multi-person conversation video generation tool open-sourced by Meituan's Visual Intelligence team. It can generate digital human conversation videos with lip-sync and natural body movements based on multi-person audio, reference images, and text prompts, delivering excellent results. Users only need to upload audio, reference images, and prompts to generate conversation videos with matching lip movements, and it can also generate singing scenarios and cartoon characters.
This project comes with several practical features: highly accurate audio-driven lip-sync, the ability to use prompts to control virtual character actions, support for outputting videos at different resolutions, and the generation of conversation scenes up to 15 seconds long. In addition, it integrates text-to-speech capabilities and incorporates several optimizations to enhance generation efficiency. It supports a low-VRAM mode and multi-GPU inference, and can run on a single RTX 4090 graphics card.
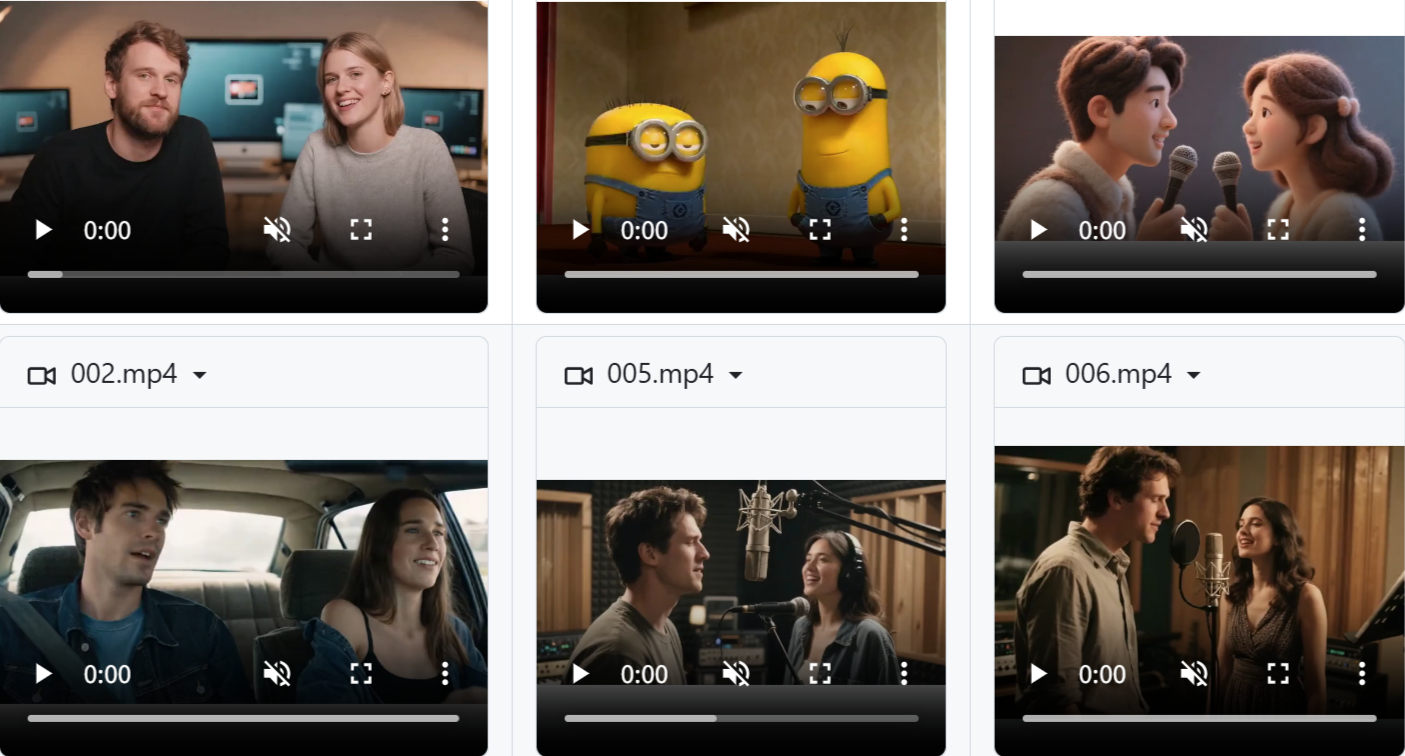
Features
✅ Audio-driven: Input multi-person audio to generate natural lip-sync and body movements
✅ Single photo input: Generate multi-person interactive videos with just one reference image
✅ Complex motion following: Support complex text prompts to generate movements and scenes that match the descriptions
✅ Multi-language support: Handle multi-language audio for accurate lip synchronization
✅ Long video generation: Use autoregressive methods to generate coherent long-form videos
✅ Efficient training strategy: Improve model performance through two-stage training, partial parameter training, and multi-task training
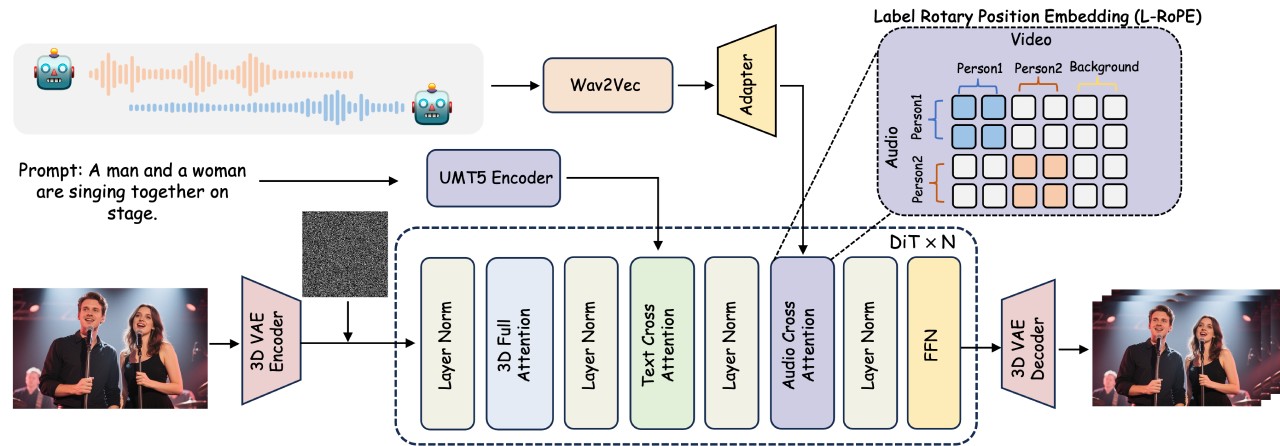
✅ L-RoPE technology: Use labeled rotary position embeddings to achieve precise binding between multi-stream audio and characters
✅ High-quality output: Generated videos are natural and smooth, with virtually no visual artifacts
Technical Highlights
✅ Pioneering L-RoPE technology: Uses labeled rotary position embeddings to address the misalignment problem between multi-audio streams and characters, enabling precise audio-character correspondence
✅ Audio-driven video generation: Input multi-person audio, reference images, and text prompts to generate interactive videos with lip-sync and natural body movements
✅ Partial parameter training + multi-task learning strategy: Preserves the ability to follow complex motion instructions while enabling adaptive positioning of dynamic characters
✅ Multi-scenario support: Applicable to film and TV production, live-streaming e-commerce, and many other scenarios
Technical Framework
✅ Base model architecture: Built on a DiT video diffusion model, integrated with a 3D variational autoencoder for efficient video data processing
✅ Single-person audio integration: Adds an audio cross-attention mechanism after the text cross-attention layer in each DiT block, extracts audio features using Wav2Vec, and resolves the mismatch in temporal granularity between video and audio through an audio adapter
✅ Multi-person audio processing: Relies on L-RoPE technology to achieve precise binding between multi-stream audio and multiple characters, avoiding "everyone speaking in unison"
Training Strategy:
✅ Two-stage training: First train single-person video generation capabilities, then train multi-character interaction and binding
✅ Partial parameter training: Only update the network parameters of the audio cross-attention layer and audio adapter, while freezing other base model parameters
✅ Multi-task training: Combines audio + image-to-video and image-to-video training approaches to enhance the model's instruction-following ability
Performance
✅ Quantitative evaluation: In head and body motion generation tasks, it outperforms several state-of-the-art methods in lip-sync (Sync-C, Sync-D) and video quality (FID, FVD) metrics
✅ Qualitative evaluation: Performs well when handling complex interaction scenarios, capable of generating videos that accurately respond to complex text prompts with few visual artifacts and natural, realistic visuals
✅ Long video generation: Uses an autoregressive approach, taking the ending portion of previously generated videos as a condition to generate new video segments, ensuring temporal coherence and continuity
Applicable Scenarios
Film and TV production: Virtual character interactions, animation dubbing, special effects compositing, short film creation
Live-streaming e-commerce: Virtual host interactions, product demonstrations and explanations, multi-language live streaming
Education: Virtual teacher interactions, language learning, historical reenactment
Game development: Virtual character dialogue, NPC interactions, multiplayer online games
Advertising and marketing: Virtual spokespersons, product promotion, social media advertisements
Virtual social: Virtual social platform interactions, virtual meetings
Entertainment and creativity: Music videos, virtual concerts, creative short films
Public services: News broadcasting, public service announcements
Corporate training: Virtual training scenarios, situational simulations
International communication: Multi-language dialogue, cultural exchange
Project Links
Project Homepage:https://meigen-ai.github.io/multi-talk/
Open Source Code:https://github.com/MeiGen-AI/MultiTalk
Paper:https://arxiv.org/abs/2505.22647









