
 Script Planner Assistant▸
 AI Apps
 AI News
HunyuanVideo-Avatar: Tencent Hunyuan's Audio-Driven Digital Human Model
小编 ·

HunyuanVideo-Avatar: Tencent Hunyuan's Audio-Driven Digital Human Model
What is HunyuanVideo-Avatar?
HunyuanVideo - Avatar is an open-source audio-driven digital human model released by Tencent Hunyuan, built on top of Tencent Hunyuan's video foundation model (HunyuanVideo). Driven by audio, HunyuanVideo-Avatar technology can generate dynamic character videos that showcase talking, body movements, head motions, and facial expressions, and it supports interactive scenes with multiple characters. Its goal is to address three key challenges in the field of audio-driven character animation: generating highly dynamic videos while maintaining character consistency, achieving precise emotional alignment between characters and audio, and supporting multi-character audio-driven animation.
Features of HunyuanVideo - Avatar
Multi-shot Support: Supports head-and-shoulders, half-body, and full-body shots, allowing users to choose the appropriate filming perspective based on their needs.
Multi-style and Multi-species Scenes: Supports multiple styles (such as cyberpunk, 2D anime, Chinese ink painting, etc.), multiple species (including robots, animals, etc.), as well as two-person scenes.
High-Consistency, High-Dynamic Video Generation: Automatically understands the content of input character images and audio, such as the character's surrounding environment and the emotions conveyed in the audio, allowing the character in the image to naturally speak or sing. It generates videos featuring natural expressions, lip synchronization, and full-body movements while ensuring subject consistency throughout the video and maintaining overall dynamism.
Wide Range of Application Scenarios: Suitable for short video creation, e-commerce, advertising, and many other application scenarios. It can generate clips of characters speaking, conversing, and performing in different settings, enabling the rapid production of product introduction videos or multi-person interactive advertisements, effectively reducing production costs.
Precise Multi-character Driving: In multi-person interactive scenes, it can accurately drive multiple characters, ensuring that lip movements, expressions, and actions stay in sync with the audio for natural interactions.
Technical Innovations of HunyuanVideo - Avatar
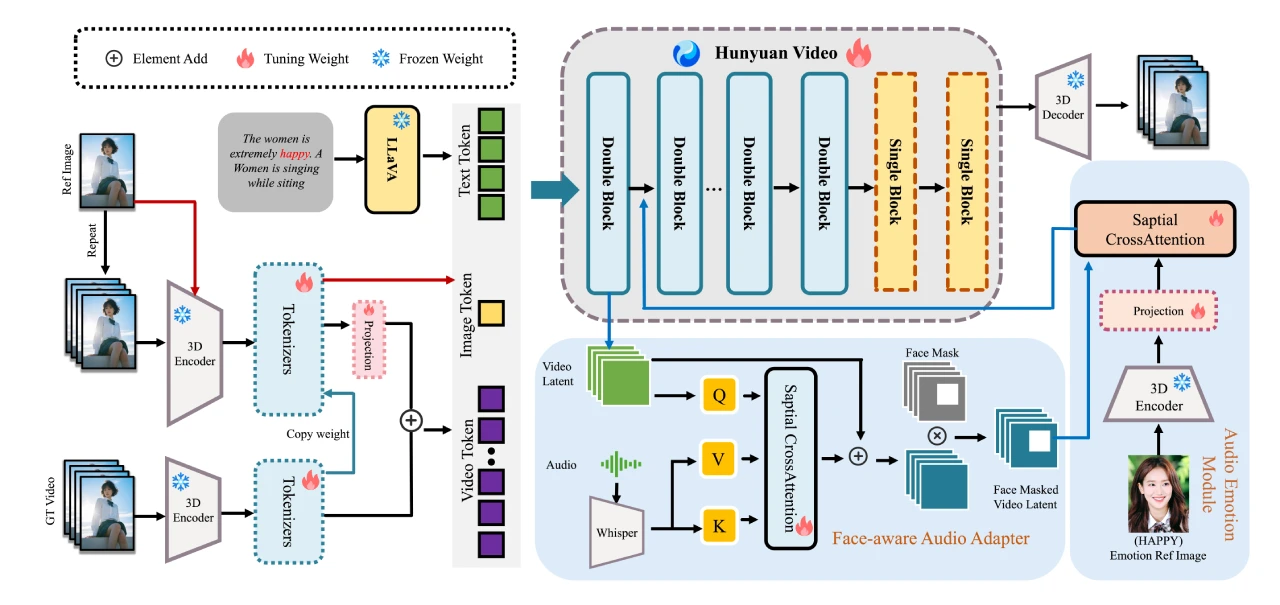
Character Image Injection Module: Built on the Multimodal Diffusion Transformer (MM - DiT) architecture, it ensures character consistency and video dynamism, addressing the challenge of maintaining a high degree of character consistency while enabling fluid and natural character movements during video generation.
Audio Emotion Module (AEM): Extracts emotional information from both audio and reference images to generate nuanced facial expressions and body movements, enabling the digital human to display facial expressions that match the emotions conveyed by the audio.
Face-aware Audio Adapter (FAA): Uses face masking technology to isolate each character's audio, enabling precise driving in multi-person scenes. It can independently drive the lip movements and expressions of different characters, preventing the actions of one character from interfering with others.
How to Use HunyuanVideo - Avatar
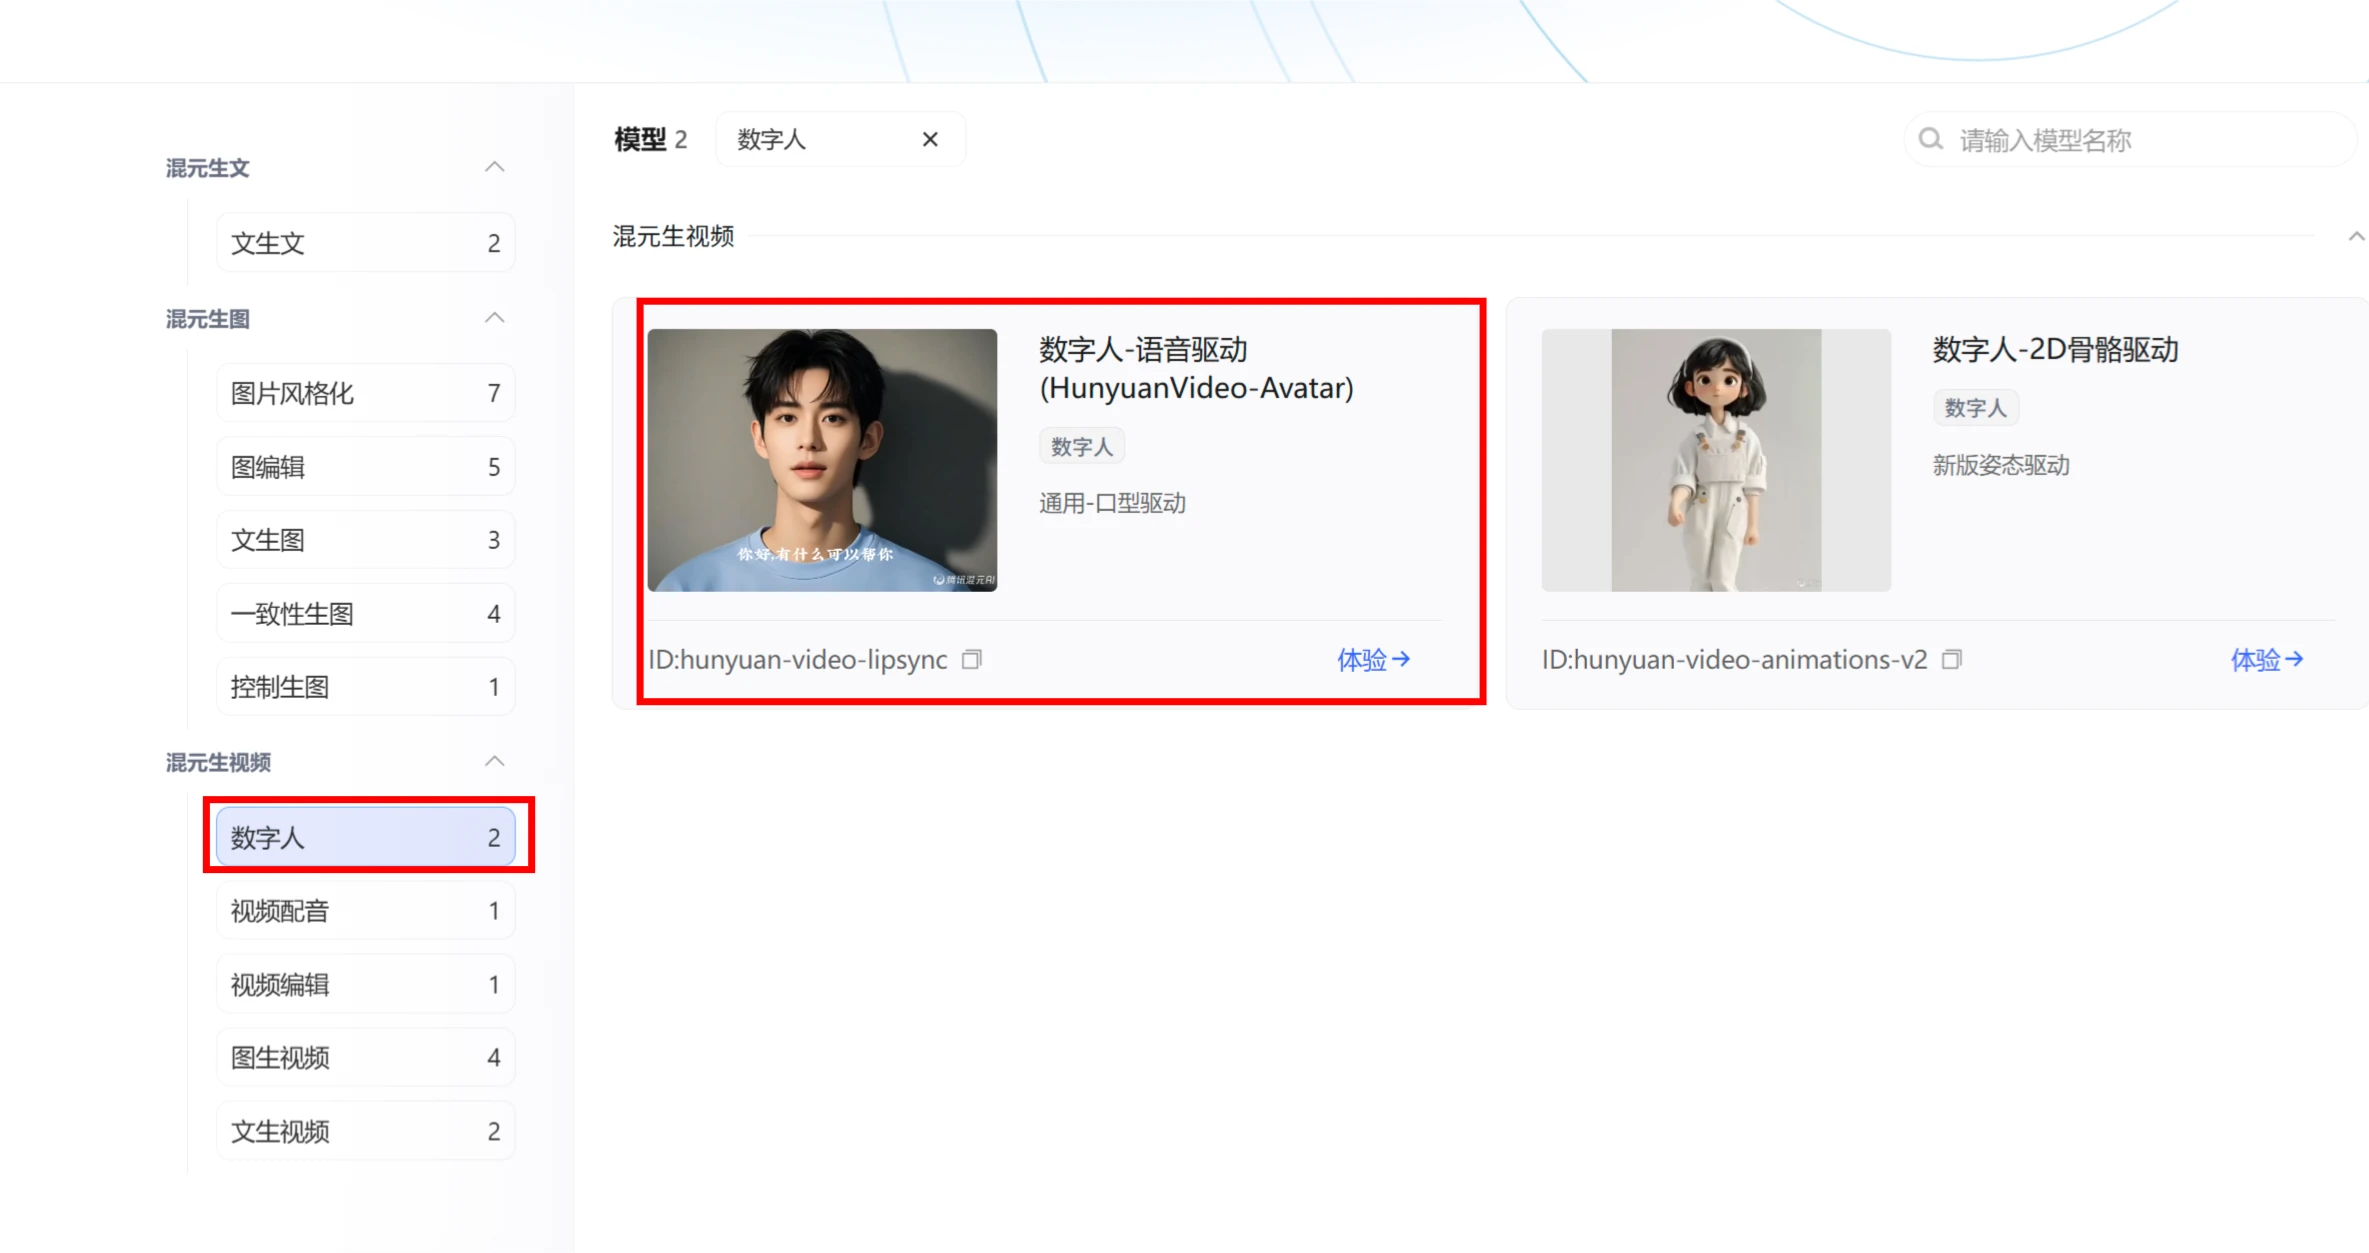
You can try it out on the Tencent Hunyuan official website (https://hunyuan.tencent.com/) under "Model Gallery - Hunyuan Video Generation - Digital Human - Audio-Driven - HunyuanVideo - Avatar". Currently, it supports uploading audio of no more than 14 seconds for video generation.
Application Scenarios of HunyuanVideo - Avatar
Short Video Creation: Quickly generate video clips featuring conversations, performances, and more across various scenarios.
E-commerce Advertising: Used for producing product introduction videos, multi-person interactive advertisements, and more.
Virtual Assistants or Games: Create animated avatars to enhance interactive experiences.
Project Links
Project Homepage: https://hunyuanvideo-avatar.github.io
GitHub Repository: https://github.com/Tencent-Hunyuan/HunyuanVideo-Avatar









