
 Script Planner Assistant▸
 AI Apps
 AI News
Alibaba Releases QwenLong-L1-32B: An LLM for Long-Context Reasoning
小编 ·

Alibaba Releases QwenLong-L1-32B: An LLM for Long-Context Reasoning
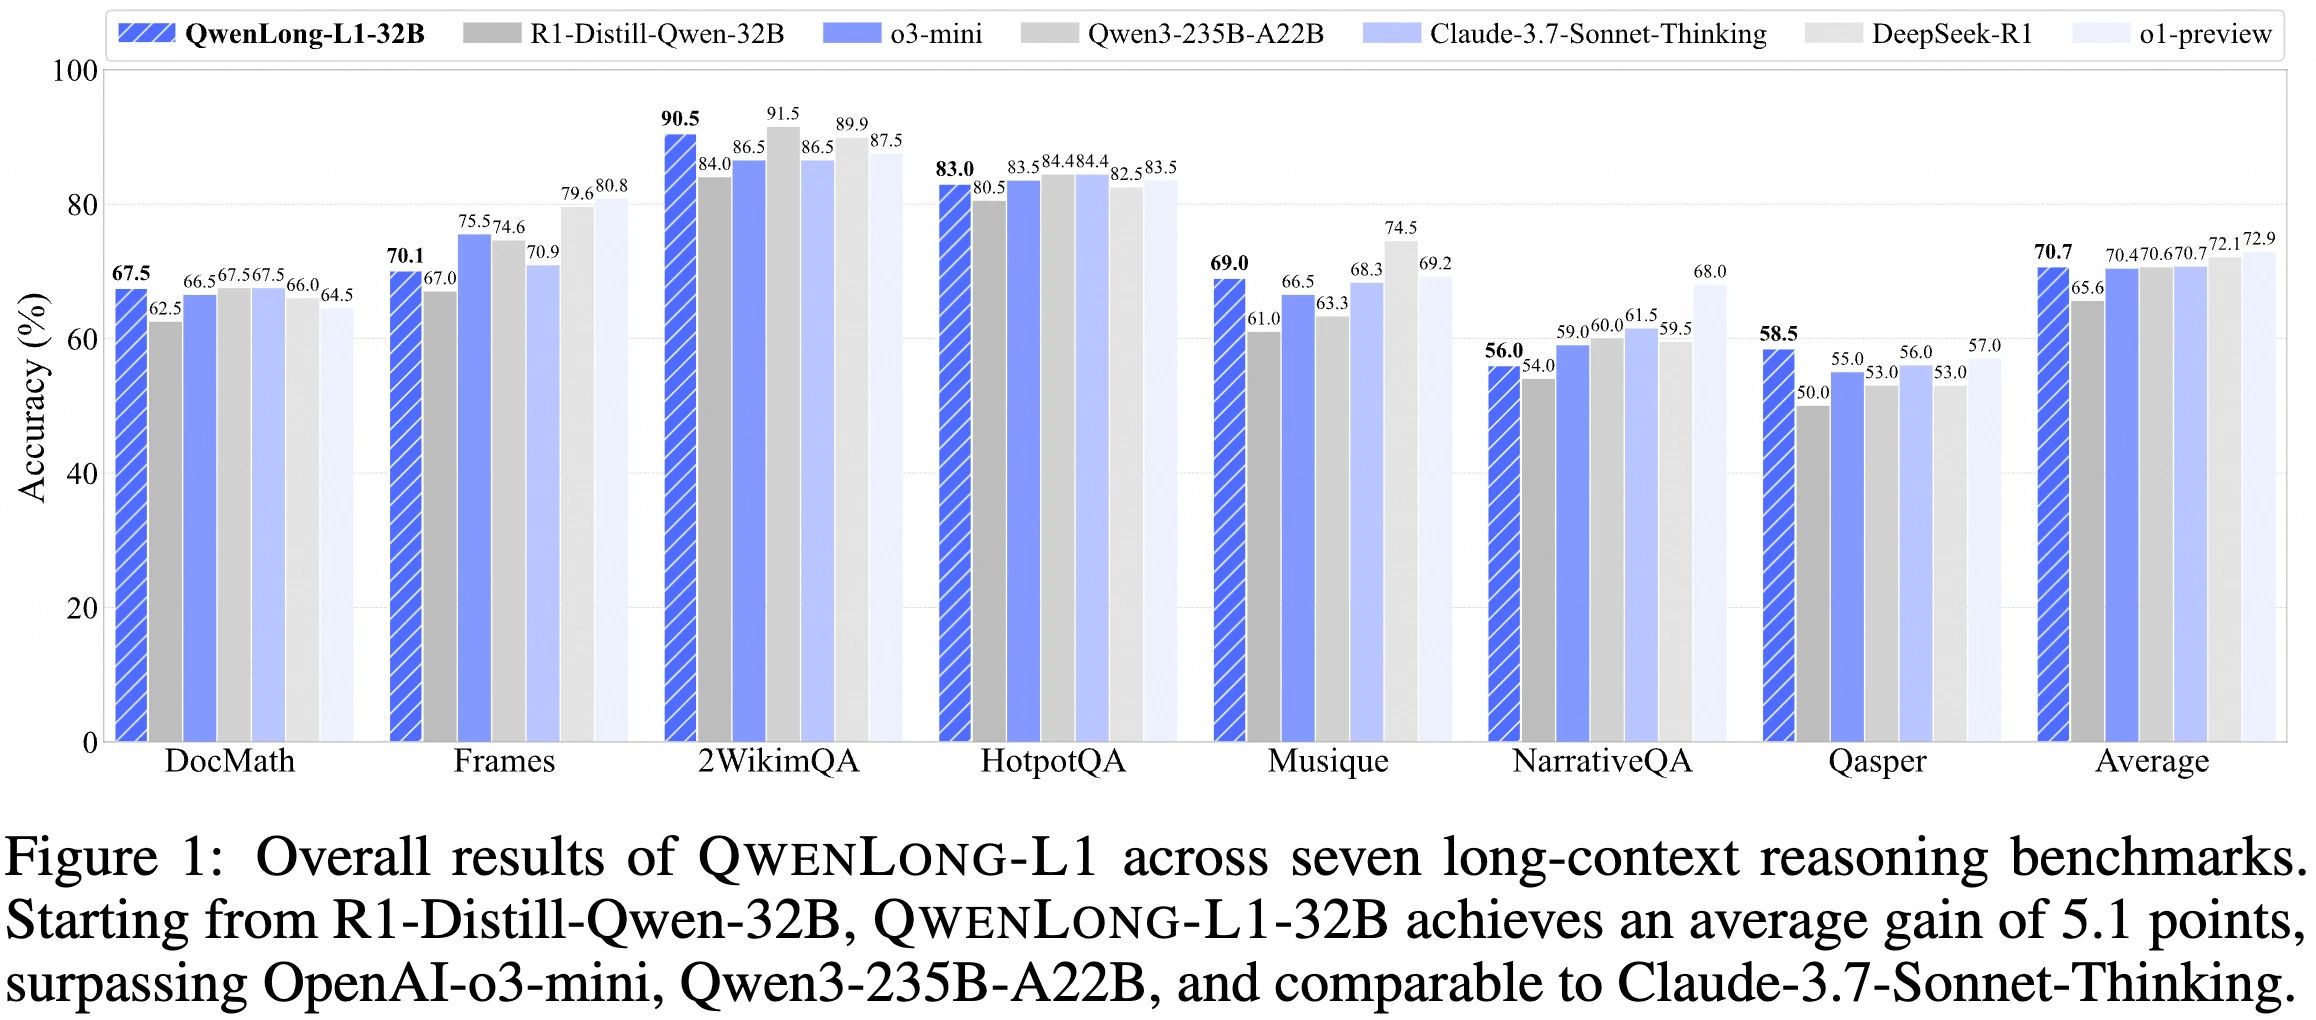
On May 26, 2025, the Alibaba team released QwenLong-L1-32B, the first long-context large reasoning model trained based on reinforcement learning, along with the DocQA-RL-1.6K dataset (containing 1,600 document question answering questions spanning mathematics, logic, and multi-hop reasoning). Its framework addresses the challenges of low training efficiency and unstable optimization processes in long-context reasoning reinforcement learning through warm-up supervised fine-tuning, curriculum-guided reinforcement learning, and difficulty-aware retrospective sampling mechanisms. It outperforms Openai-o3-mini and Qwen3-235B-A22B across 7 long-context DocQA benchmarks, achieving performance on par with Claude-3.7-Sonnet-Thinking.
Model Framework
Core concept: Adapt short-context large reasoning models (LRMs) to long-context scenarios through reinforcement learning (RL).
Main Components:
Warm-up Supervised Fine-Tuning (SFT) stage: Establishes a robust initial policy.
Curriculum-based staged reinforcement learning technique: Stabilizes policy evolution.
Difficulty-aware retrospective sampling strategy: Encourages policy exploration.
Training Data
A specialized reinforcement learning training dataset called DocQA-RL-1.6K was used, containing 1,600 document question answering questions covering the fields of mathematics, logic, and multi-hop reasoning.
Performance
Across seven long-context document question answering benchmarks, QwenLong-L1-32B outperformed flagship LRMs such as OpenAI-o3-mini and Qwen3-235B-A22B, achieving performance comparable to Claude-3.7-Sonnet-Thinking, demonstrating leading performance among current state-of-the-art LRMs.
Experimental Design
A specialized RL training dataset DocQA-RL-1.6K was constructed, containing 1,600 document question answering questions covering the fields of mathematics, logic, and multi-hop reasoning.
The mathematical reasoning portion used 600 questions from the DocMath dataset, with 75% used for training and 25% used for evaluation.
The logical reasoning portion synthesized 600 multiple-choice questions through DeepSeek-R1, covering real-world documents in the legal, financial, insurance, and production fields.
The multi-hop reasoning portion sampled 200 examples each from MultiHopRAG and Musique, emphasizing cross-document reasoning.
Evaluations were conducted on seven long-context DocQA benchmarks, including 2WikiMultihopQA, HotpotQA, Musique, NarrativeQA, Qasper, Frames, and DocMath.
Results and Analysis
QwenLong-L1-32B performed excellently across seven long-context DocQA benchmarks, outperforming flagship LRM models such as OpenAI-o3-mini and Qwen3-235B-A22B, with performance comparable to Claude-3.7-Sonnet-Thinking.
On the mathematical reasoning benchmark DocMath, QwenLong-L1-32B achieved 85.3% in both exact match and LLM-judged accuracy.
On the multi-hop reasoning benchmark HotpotQA, the model achieved 87.6%, significantly outperforming existing models.
Project Links
Github:https://github.com/Tongyi-Zhiwen/QwenLong-L1
Huggingface:https://huggingface.co/Tongyi-Zhiwen/QwenLong-L1-32B
Modelscope:https://www.modelscope.cn/models/iic/QwenLong-L1-32B









