
 Script Planner Assistant▸
 AI Apps
 AI News
AniSora: Bilibili's Open-Source Anime Video Generation Model
小编 ·

AniSora: Bilibili's Open-Source Anime Video Generation Model
What is AniSora?
AniSora is an AI animation video generation system open-sourced by Bilibili on May 12, 2025. It can easily generate anime videos in various styles, such as anime episode clips, Chinese original animation, comic adaptations, VTuber content, anime PVs, and remixed (guichu) videos. The system performs well in maintaining character appearance and smooth motion, and can be considered the most advanced animation video generation model available today.
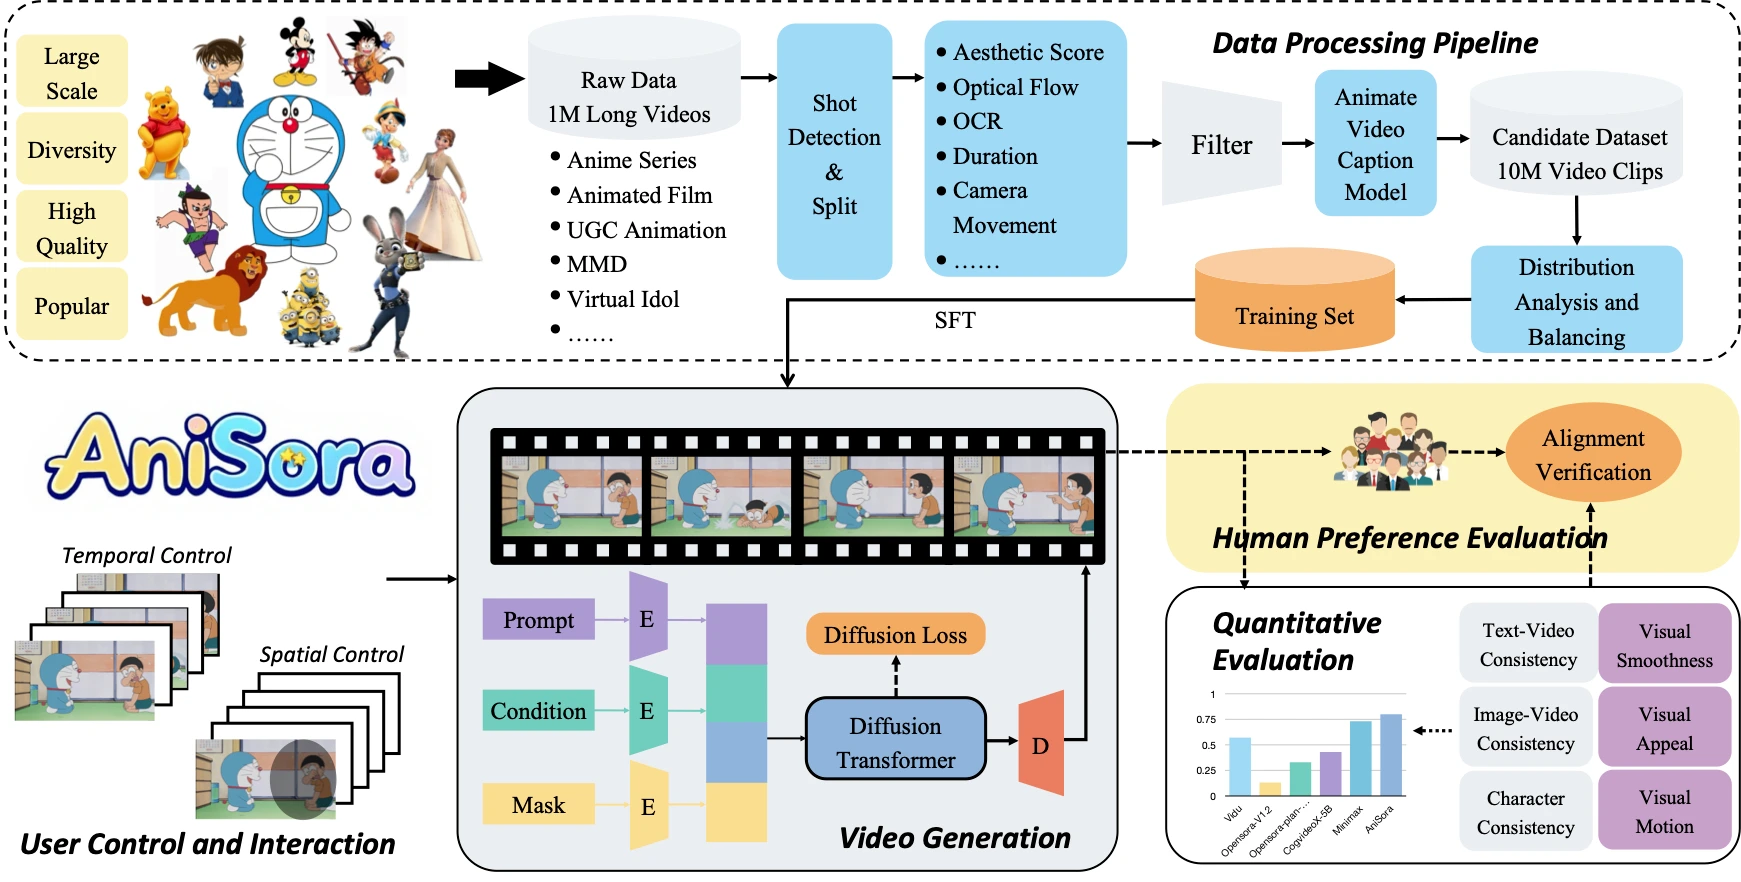
AniSora Features
Image-to-Video Generation: Generates coherent animation videos from a single image, suitable for expanding static scenes into dynamic ones.
Frame Interpolation: Supports keyframe interpolation, generating intermediate frames to achieve smooth transitions and reducing the manual drawing workload in animation production.
Local Image Guidance: Allows users to specify particular regions for animation generation.
Spatiotemporal Control: Combines temporal and spatial control capabilities, supporting first-frame, last-frame, multi-frame guidance, and other methods to enable precise animation creation.
AniSora Model Characteristics
Targeted Optimization: Compared with natural videos, anime videos are more expressive and abstract in style, and traditional generation models often struggle to accurately reproduce character expressions, action rhythm, and exaggerated camera language. AniSora has been specifically optimized for these characteristics, aiming to improve video generation efficiency without sacrificing creative expression.
Diverse Style Support: Capable of generating video clips in multiple styles with a single click, covering series episodes, Chinese original animation, comic adaptations, VTuber content, anime PVs, and even remixed (guichu) creations.
Low Barrier to Creation: For individuals or studios with practical production needs, AniSora is an extremely attractive creative tool.
AniSora Core Modules
Data Processing Pipeline: Preprocessed over 10 million pairs of high-quality text-video data, providing a solid foundation for training.
Controllable Generation Model: Introduces a spatiotemporal mask module that supports image-to-video, keyframe interpolation, local image guidance, and other features, adaptable to various creative needs.
Evaluation System: Built an evaluation dataset containing 948 diverse animation clips, combined with double-blind human review and the VBench scoring system to rate dimensions such as character consistency and action continuity.
AniSora Technical Principles
Diffusion Model: Based on the diffusion model architecture, it progressively removes noise to generate high-quality video content.
Spatiotemporal Mask Module: Allows the model to control specific temporal and spatial regions during generation, such as masking which frames or regions require animation, enabling local guidance and keyframe interpolation.
3D Causal Variational Autoencoder (3D Causal VAE): Used to encode and decode the spatiotemporal features of videos, compressing video into a low-dimensional latent space to reduce computational complexity while retaining key spatiotemporal information.
Transformer Architecture: Combined with the powerful modeling capabilities of Transformers, it captures complex spatiotemporal dependencies in videos through attention mechanisms, enabling the model to process long-sequence data and generate more coherent video content.
Supervised Fine-Tuning: Based on pretraining, supervised fine-tuning is performed using a large amount of anime video data, employing various strategies (such as weak-to-strong training strategies, multi-task learning, etc.) to improve the model's generalization ability and generation quality.
Data Processing Pipeline: Based on techniques such as scene detection, optical flow analysis, and aesthetic scoring, high-quality training data is filtered from a large amount of raw anime videos, ensuring the quality and diversity of the training data.
Open-Source Address
https://github.com/bilibili/Index-anisora/tree/main
https://huggingface.co/IndexTeam/Index-anisora
https://www.modelscope.cn/organization/bilibili-index









