
 Script Planner Assistant▸
 AI Apps
 AI News
Simple Subtitling: Automatic Subtitle Generator for Video
小编 ·

Simple Subtitling: Automatic Subtitle Generator for Video
What is Simple Subtitling?
Simple Subtitling is an AI tool that can automatically generate subtitles for film and video works. It uses WhisperX technology to convert audio files into subtitle files (SRT) with timestamps and speaker IDs. It then assigns speaker IDs by extracting and clustering speaker embeddings, and can assign exact speaker names when audio exemplars are available. Specifically, it first converts audio into text with timestamps; then extracts features for each speaker, groups the features using agglomerative hierarchical clustering (AHC), and finally assigns IDs to speakers. If the user provides voice samples of the actors, it can also name the speakers. This tool is designed to make subtitle generation easier and make film and video works more accessible to watch.
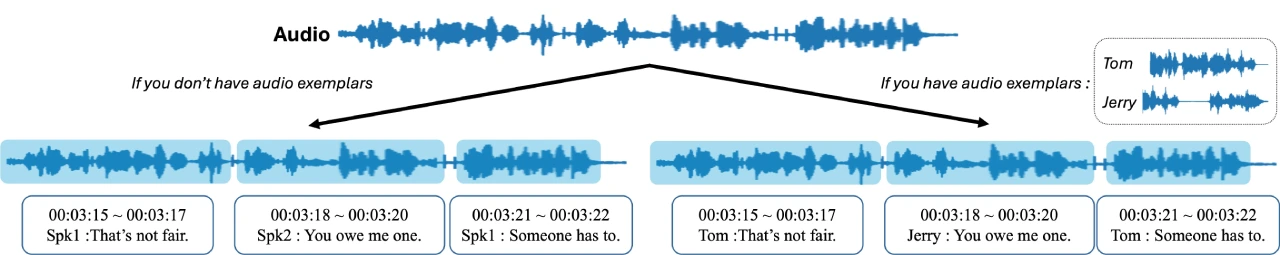
Features of Simple Subtitling
Speech Recognition and Timestamp Generation: Uses WhisperX technology to accurately recognize audio content word by word and sentence by sentence, and generates speech text with timestamps.
Speaker Recognition: Assigns speaker IDs by extracting sentence-level speaker embeddings and applying agglomerative hierarchical clustering (AHC) to group the embeddings.
Multilingual Support: Supports audio input in multiple languages and can generate corresponding subtitles.
Custom Settings: Users can specify the audio exemplar directory to assign exact names to speakers.
High-Precision Speech Recognition and Clustering: Achieves high-precision speech recognition and clustering, accurately converting speech into text and classifying speech from different speakers, improving subtitle accuracy and readability.
Installation and Usage of Simple Subtitling
Installation Steps
Create and activate a conda environment named simplesub, specifying Python version 3.11.
Install the required Python packages for the project in this environment by running the pip install -r requirements.txt command.
You also need to install ffmpeg. Please refer to the relevant documentation for specific installation methods.
Usage
Basic Usage
Run python main.py --input_file [INPUT_FILE_PATH] --output_file [OUTPUT_SRT_PATH], for example python main.py --input_file data/friends.wav --output_file result/friends.srt, which will generate a subtitle file based on the input audio file.
Using Audio Exemplars to Specify Speaker Names
First, organize the --exemplar_dir directory according to a specific structure, where each subfolder represents a speaker and contains that speaker's audio samples.
Then run python main.py --input_file [INPUT_FILE_PATH] --output_file [OUTPUT_SRT_PATH] --exemplar_dir [PATH_OF_EXEMPLARS], for example python main.py --input_file data/friends.wav --output_file result/friends_exemplars.srt --exemplars exemplars.
Parameter Description
input_file: The path of the input audio file.
output_file: The path of the output subtitle file (SRT format).
whisper_model_type: The type of Whisper model, default is 'medium'. Available types can be found in the relevant documentation.
language: Language code (two letters, e.g., 'en' for English). If None, Whisper will detect the language within the first 30 seconds. Default is None.
embedding_model: Speaker embedding extractor, options are 'ecapatdnn' or 'wespeaker'. Default is 'wespeaker'.
n_cluster: If the number of speakers is known, this parameter can be specified. Default is None.
distance_threshold: If n_cluster is not specified, this is the distance threshold for AHC (Agglomerative Hierarchical Clustering). Default is 0.8.
exemplar_dir: The path of the directory containing audio exemplars. Default is None.
exemplar_threshold: The cosine similarity threshold used to determine "unknown" speakers. Default is 0.2.
Github:https://github.com/JaesungHuh/simple-subtitling









