
 Script Planner Assistant▸
 AI Apps
 AI News
ContextGem: AI Tool for Extracting Structured Data from Documents
小编 ·

ContextGem: AI Tool for Extracting Structured Data from Documents
What is ContextGem?
ContextGem is an AI tool for extracting structured data from documents. Its core capability lies in automatically understanding intent based on user-specified extraction requirements and precisely locating the corresponding content within documents, making it especially adept at in-depth analysis.
It is ideal for scenarios that involve heavy document reading, such as extracting key clauses from contracts, important data from reports, or core arguments from papers, helping users efficiently perform close reading.
ContextGem doesn't just locate information and tell you exactly which paragraph or sentence it came from—it also explains the reasons behind the extraction and the reasoning process. It accomplishes complex extraction tasks with just a few lines of code, offering a very high degree of automation, with many complex operations encapsulated out of the box. It can automatically generate prompts, automatically validate data, and automatically segment text, greatly simplifying user workflows.
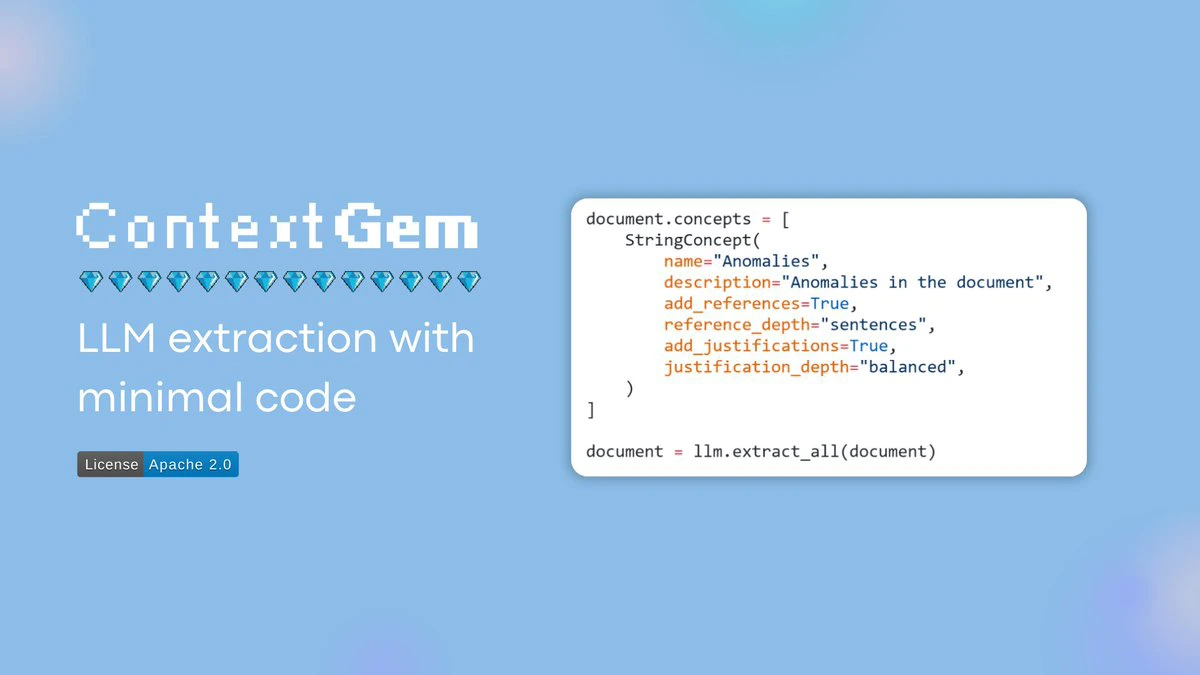
Core Features of ContextGem
Automated Dynamic Prompts: Automatically generates customized, comprehensive prompts based on extraction needs, with no manual prompt writing or maintenance required.
Automatic Data Model and Validator Generation: Automatically creates Pydantic data models and validation logic from definitions, eliminating repetitive boilerplate code.
Precise Mapping of Extracted Content: Automatically maps extracted data back to its precise location in the source document (down to the paragraph or sentence level), ensuring results are verifiable and traceable.
Extraction Justification: Automatically includes textual reasoning or evidence supporting each extracted data point, enhancing the transparency and credibility of the results.
Intelligent Document Segmentation: Leverages state-of-the-art neural segmentation (SaT) models to accurately split documents into paragraphs and sentences, with support for multiple languages.
Unified Extraction Pipeline: Allows the entire extraction workflow to be defined in a single, declarative, and reusable pipeline configuration, including nested contexts and role-specific LLMs.
Nested Context Extraction Support: Automatically handles hierarchical information extraction based on pipeline definitions (e.g., document > section > subsection > entity), simplifying complex document analysis.
Built-in Concurrency Processing: Enables concurrent I/O processing with a simple use_concurrency=True switch, accelerating intensive extraction workflows involving multiple LLM calls.
Automatic Usage and Cost Tracking: Monitors LLM calls, token usage, and associated costs within workflows with no additional setup required.
Integrated Fallback and Retry Logic: Includes built-in retry mechanisms and allows easy configuration of fallback LLMs for improved resilience.
Multi-language Support: Supports multiple languages for both input and output without requiring additional prompts.
Multi-LLM Provider Support: Supports cloud LLMs (e.g., OpenAI, Anthropic, Google, Azure OpenAI, etc.) and local LLMs (e.g., Ollama, LM Studio, etc.) through a unified interface for easy switching.
Optimization Strategies: Provides strategies for optimizing accuracy, speed, and cost, along with recommendations for handling long documents and selecting appropriate LLMs.
Result Serialization: Allows saving and loading document objects, pipelines, and LLM configurations to avoid repeated calls to expensive LLMs.
Document Converter
ContextGem provides built-in document converters that can transform DOCX files into data usable by LLMs. It can extract information that other open-source tools often miss, such as misaligned tables, comments, footnotes, text boxes, headers/footers, and embedded images, while preserving document structure and rich metadata for better LLM analysis.
ContextGem Use Cases
ContextGem focuses on deep, accurate analysis of individual documents, leveraging the expanded context windows and capabilities of modern LLMs. It is well suited for scenarios that require extracting precise data and insights from specific documents—for example, legal contract analysis, financial document processing, and similar tasks. However, it does not currently support cross-document querying or whole-corpus retrieval; for such use cases, modern RAG systems (e.g., LlamaIndex, Haystack) may be more appropriate.
ContextGem Project Link
https://github.com/shcherbak-ai/contextgem









