
 Script Planner Assistant▸
 AI Apps
 AI News
Arxiv Daily AIGC: An Automated Tool for Crawling, Analyzing, and Organizing arXiv Papers
小编 ·

Arxiv Daily AIGC: An Automated Tool for Crawling, Analyzing, and Organizing arXiv Papers
What is Arxiv Daily AIGC?
Arxiv Daily AIGC is an AI-driven automated tool for crawling, analyzing, and organizing arXiv articles. Every day, it extracts the latest papers from the cs.CV category on arXiv, filters out papers related to image, video, and multimodal generation through the OpenRouter API, and evaluates their value. The filtered paper information is saved as JSON files, and then beautiful HTML daily reports are generated based on this data, with the main page updated. The entire workflow, including daily scheduled crawling, filtering, generation, and deployment to GitHub Pages, is fully automated through GitHub Actions.
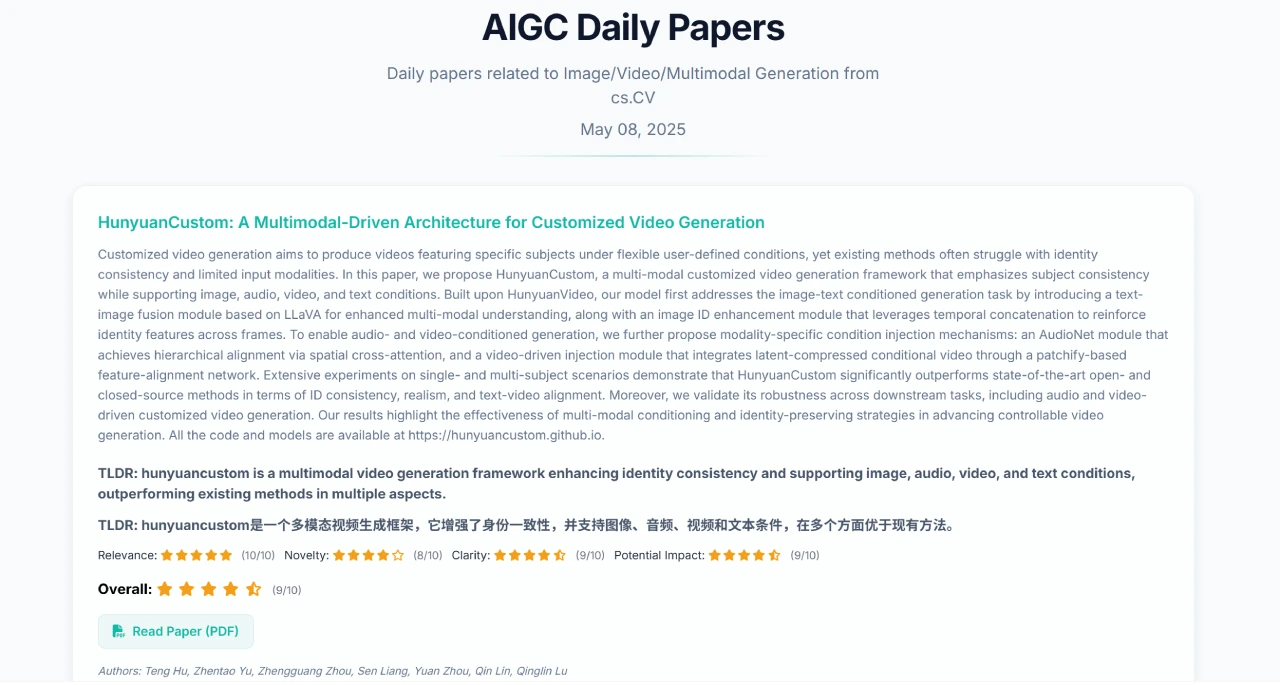
Features of Arxiv Daily AIGC
Data Crawling: Automatically crawls the latest papers from the Computer Vision (cs.CV) category on arXiv every day.
AI Filtering: Uses a large language model (LLM, currently via the OpenRouter API) to intelligently filter papers related to image/video/multimodal generation, and scores the value of papers across different dimensions.
Data Storage: Saves the filtered paper information (title, abstract, links, etc.) as date-named JSON files (stored in the daily_json/ directory).
Web Page Generation: Generates daily HTML reports based on JSON data using predefined templates (stored in the daily_html/ directory), and updates the main entry page index.html.
Automated Deployment: Implements the complete workflow of daily scheduled crawling, filtering, generation, and deployment to GitHub Pages through GitHub Actions.
Tech Stack of Arxiv Daily AIGC
Backend/Script: Python 3.x (using libraries such as arxiv, requests, jinja2, etc.).
Frontend: HTML5, TailwindCSS (CDN), JavaScript, Framer Motion (CDN).
Automation: GitHub Actions.
Deployment: GitHub Pages.
Installation and Usage of Arxiv Daily AIGC
Clone the repository: Use the git clone command to clone the project locally.
Create and activate a virtual environment: A Python virtual environment is recommended.
Install dependencies: Install all Python libraries listed in the requirements.txt file.
Configure API key: The project requires an OpenRouter API key for AI filtering.
How to Use Arxiv Daily AIGC
Run locally: Directly run the main script main.py to manually trigger the complete workflow (crawling, filtering, generation).
GitHub Actions Automation: The repository is configured with a GitHub Actions workflow (.github/workflows/daily_arxiv.yml), which runs on a schedule by default every day.
Related Links
Github:https://github.com/onion-liu/arxiv_daily_aigc
Project Homepage:https://www.aha-time.com/arxiv_daily_aigc/









