
 Script Planner Assistant▸
 AI Apps
 AI News
Voila: An Open-Source End-to-End AI Voice Model
小编 ·

Voila: An Open-Source End-to-End AI Voice Model
What is Voila?
Voila is an end-to-end AI voice model that uses full-duplex technology, capable of listening and speaking simultaneously with low latency. Its response latency is only 195 milliseconds, lower than the average human reaction time, and it abandons the traditional pipeline system.
The model comes preloaded with over one million voices and supports multiple functions including Automatic Speech Recognition (ASR), Text-to-Speech (TTS), and multilingual voice translation. In addition, Voila enables real-time autonomous conversations, continuously listening, reasoning, and proactively responding to users. Users can also define the speaker's identity, tone, and other characteristics through text instructions, achieving a more personalized and natural voice interaction experience.
Voila Features
Low-latency and full-duplex conversation: Voila achieves full-duplex, low-latency conversation with a response latency of only 195 milliseconds, surpassing the average human reaction time.
Preservation of voice details: Capable of preserving rich voice details such as intonation, rhythm, and emotion.
Hierarchical multi-scale Transformer architecture: Combines the reasoning capabilities of Large Language Models (LLMs) with powerful acoustic modeling, enabling natural, character-aware voice generation. Users can define the speaker's identity, tone, and other characteristics through text instructions.
Powerful voice customization: Supports over one million pre-built voices and can efficiently customize new voices from audio samples as short as 10 seconds.
Unified model design: Suitable for a wide range of voice applications, including Automatic Speech Recognition (ASR), Text-to-Speech (TTS), and multilingual voice translation with minimal adaptation.
Technical Principles
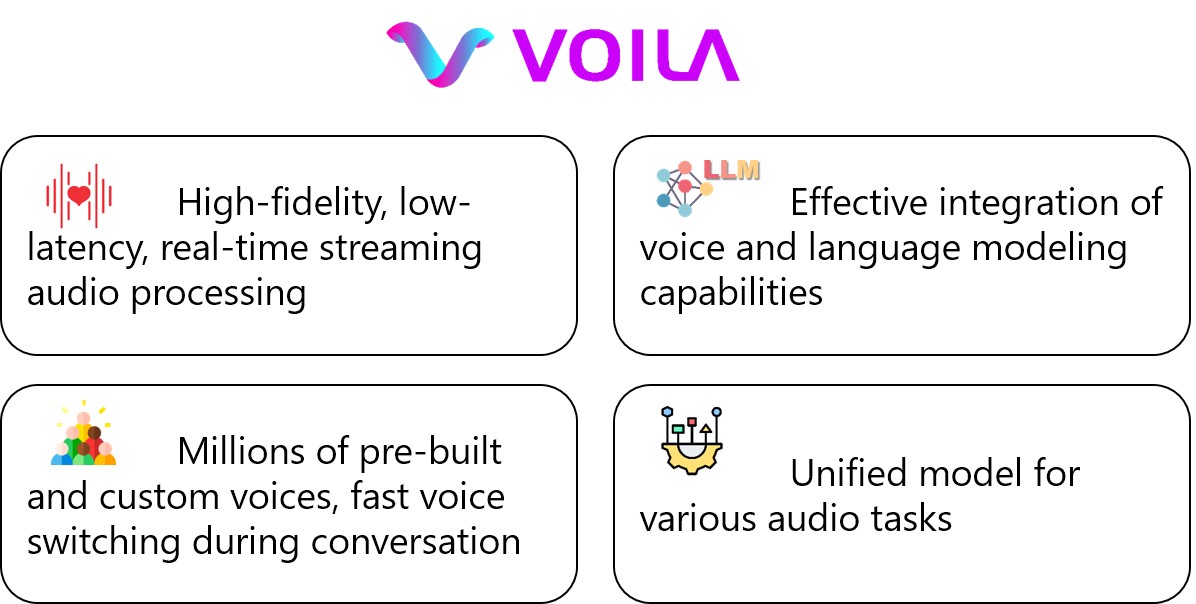
High-fidelity, low-latency, real-time streaming audio processing: Enables low-latency conversation while preserving voice details.
Efficient integration of voice and language modeling capabilities: Combines text and voice modeling to enhance interaction naturalness.
Millions of pre-built and custom voices: Supports quick voice switching during conversation, enriching the interaction experience.
Unified model for various audio tasks: A single model supports multiple audio tasks, reducing development and deployment costs.
Voila Application Scenarios
Voice assistant: Can serve as an intelligent voice assistant that interacts with humans in an autonomous, real-time, and emotionally expressive manner, continuously listening, reasoning, and proactively responding, facilitating smooth, dynamic, and emotionally resonant interaction experiences.
Voice role-playing: In scenarios such as role-playing, users can define the speaker's identity, tone, and other characteristics to achieve natural, character-aware voice generation.
Multilingual voice translation: With minimal adaptation, it can be used for multilingual voice translation.
Project Related Links
Project Homepage: https://voila.maitrix.org/
Model: https://huggingface.co/collections/maitrix-org/voila-67e0d96962c19f221fc73fa5
Demo: https://huggingface.co/spaces/maitrix-org/Voila-demo
Paper: https://arxiv.org/abs/2505.02707
GitHub Repository: https://github.com/maitrix-org/Voila









