
 Script Planner Assistant▸
 AI Apps
 AI News
Muyan-TTS: An Open-Source Trainable TTS Model by Muyan for Podcasts
小编 ·

Muyan-TTS: An Open-Source Trainable TTS Model by Muyan for Podcasts
What is Muyan-TTS?
Muyan-TTS is an open-source, trainable TTS model released by Muyan Intelligence (Beijing), designed specifically for podcasts, with a budget of under $50,000. Muyan-TTS is pretrained on over 100,000 hours of podcast audio data, supports zero-shot TTS synthesis, is capable of generating high-quality speech, and also supports speaker adaptation through a few tens of minutes of target speech.
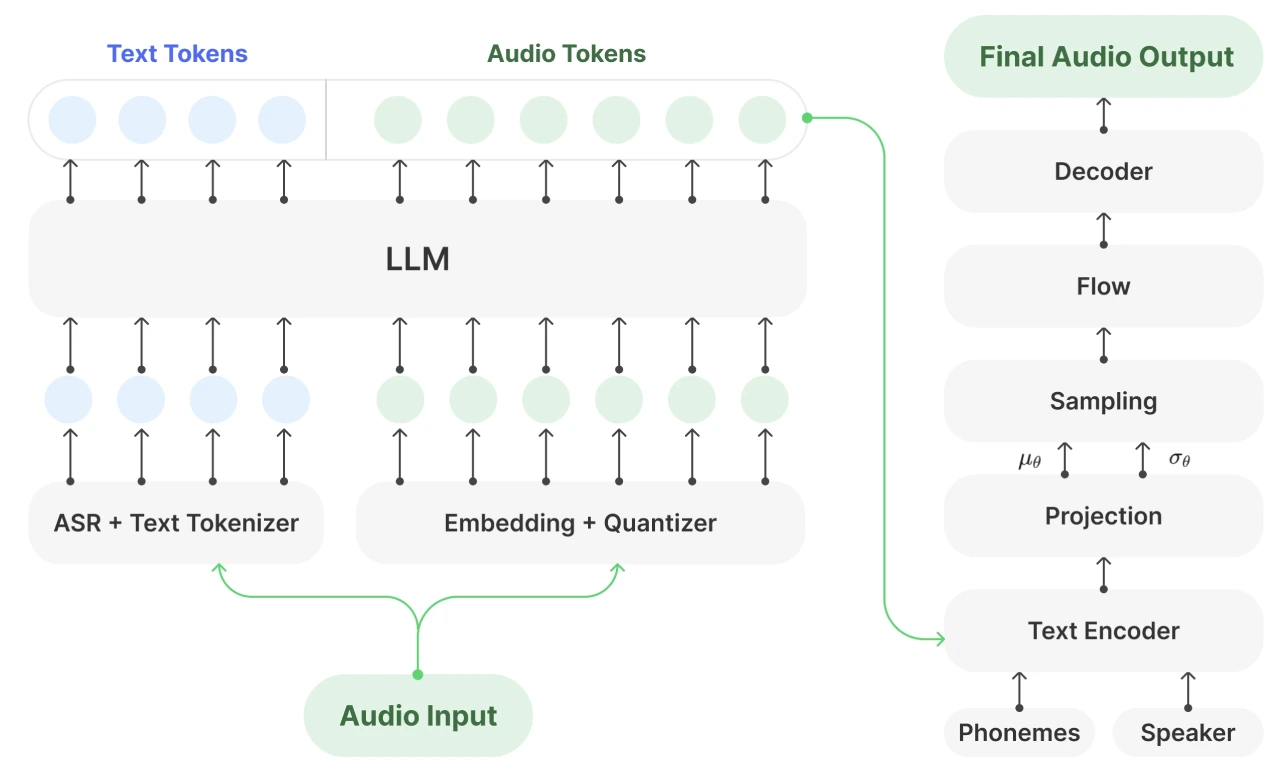
Features of the Muyan-TTS Model
Large-scale pretraining: Muyan-TTS is based on the Llama-3.2-3B model and pretrained using over 100,000 hours of podcast audio data. It enables zero-shot text-to-speech AI synthesis and generates high-quality speech.
Speaker adaptation support: With a few tens of minutes of target speaker voice data, Muyan-TTS can further adapt to the voice characteristics of a specific speaker, enabling highly customized speech synthesis.
Architecture design: Muyan-TTS adopts the two-stage structure of GPT-SoVITS. The language model part continues pretraining with Llama-3.2-3B as the backbone, while the decoder part uses the SoVITS architecture, combining the semantic modeling capabilities of LLMs with the grapheme-to-phoneme (G2P) characteristics of the VITS model, effectively reducing hallucination phenomena.
Data processing: A parallel corpus containing over 100,000 hours of high-quality speech and corresponding transcriptions has been constructed, suitable for TTS training in long audio scenarios such as podcasts.
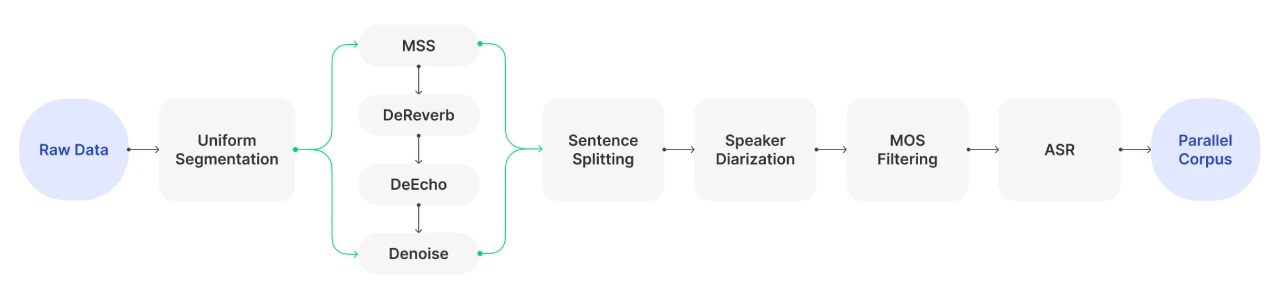
Open Source & Training
Open-source information: Muyan-TTS is fully open source, providing a complete data collection and processing workflow, detailed training methods, and an optimized inference framework. Its code and models are available on GitHub.
Training cost: Regarding training cost, assuming the rental prices of A10 and A100 GPUs are $0.5 and $1 per hour respectively, the total training cost of Muyan-TTS is approximately $50,540.
Performance
Zero-shot synthesis: On the LibriSpeech dataset, Muyan-TTS demonstrates outstanding zero-shot synthesis performance, with a word error rate second only to CosyVoice2 and a mean opinion score higher than Spark-TTS and GPT-SoVITS v3.
Supervised fine-tuned model: The supervised fine-tuned Muyan-TTS-SFT outperforms the base model in speech quality and speaker similarity, but shows a slight decrease in WER.
Inference speed: Muyan-TTS has the fastest inference speed among all tested models, requiring only 0.33 seconds to synthesize 1 second of speech, making it suitable for real-time speech generation scenarios.
Application Scenarios of Muyan-TTS
Muyan-TTS is suitable for various forms of audio content, such as host narration, interview replication, voice summaries, and more. Balancing synthesis quality, personalization capabilities, and runtime efficiency, it is well-suited for long audio scenarios such as podcasts.
Limitations
It relies on the G2P module in the decoder, requiring a complete phoneme sequence for synthesis, and cannot achieve streaming inference.
The training data is primarily in English, with limited multilingual speech synthesis capabilities.
Due to the lack of instruction-level annotations in the training corpus, Muyan-TTS currently does not support instruction-following TTS tasks.
Installation and Usage of Muyan-TTS
Installation Steps
1. Clone the repository and create a virtual environment:
git clone https://github.com/MYZY-AI/Muyan-TTS.git
cd Muyan-TTS
conda create -n muyan-tts python=3.10 -y
conda activate muyan-tts
make build
2. Install FFmpeg (Ubuntu system):
sudo apt update
sudo apt install ffmpeg
3. Download the model:
The Muyan-TTS and Muyan-TTS-SFT models can be downloaded from Hugging Face or ModelScope.
You also need to download the weights of chinese-hubert-base.
Place all downloaded models in the pretrained_models directory.
Usage
Run the following command for speech synthesis:
python tts.py
The core inference code is as follows:
async def main(model_type, model_path):
tts = Inference(model_type, model_path, enable_vllm_acc=False)
wavs = await tts.generate(
ref_wav_path="assets/Claire.wav",
prompt_text="Although the campaign was not a complete success, it did provide Napoleon with valuable experience and prestige.",
text="Welcome to the captivating world of podcasts, let's embark on this exciting journey together."
)
output_path = "logs/tts.wav"
with open(output_path, "wb") as f:
f.write(next(wavs))
print(f"Speech generated in {output_path}")
GitHub repository:https://github.com/MYZY-AI/Muyan-TTS









