
 Script Planner Assistant▸
 AI Apps
 AI News
Xiaomi MiMo: Xiaomi's First Open-Source Reasoning LLM
小编 ·

Xiaomi MiMo: Xiaomi's First Open-Source Reasoning LLM
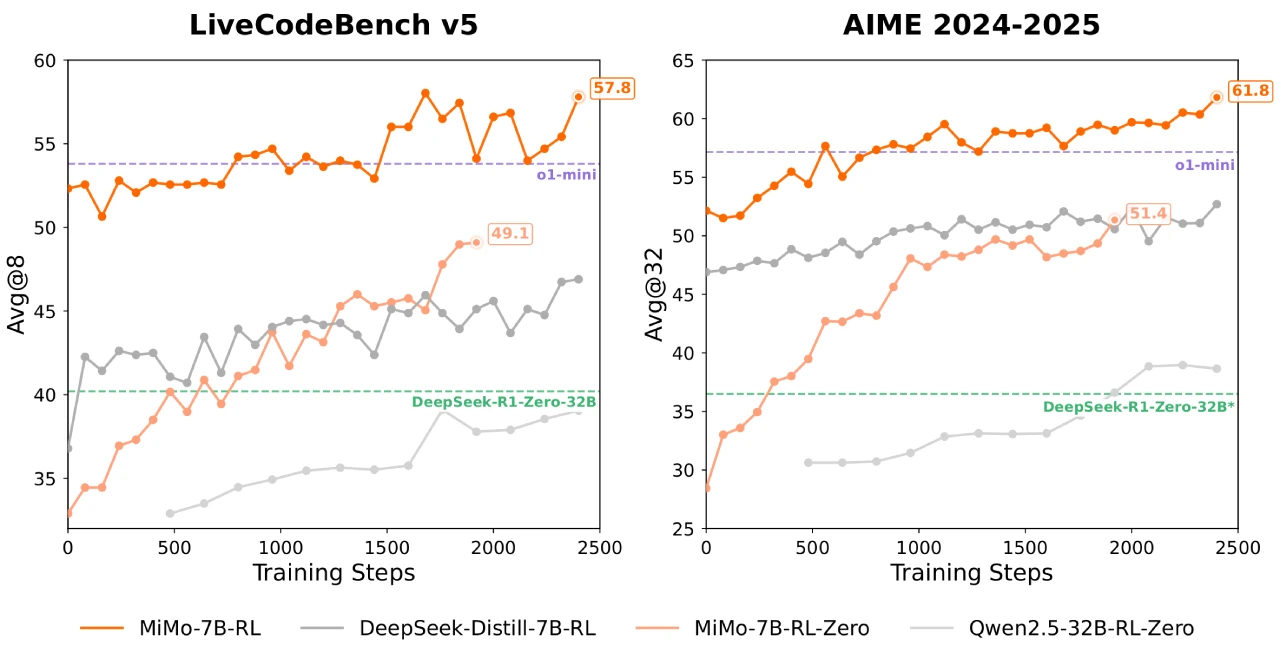
Xiaomi MiMo is Xiaomi's first open-source large model "built for reasoning," announced on April 30, 2025. The MiMo-7B series models fully unlock the reasoning potential of language models by paying attention not only to post-training but also to pre-training strategies tailored for reasoning. Despite the relatively small 7B scale, this series demonstrates reasoning capabilities that surpass many 32B models, with MiMo-7B-RL achieving performance comparable to OpenAI o1-mini on math and code reasoning tasks.
MiMo Core Features
Pre-training
Data preprocessing optimization: Improved text extraction tool suite, adopting multi-dimensional data filtering to increase the density of reasoning patterns in pre-training data.
Synthetic data generation: Employed multiple strategies to generate large volumes of diverse synthetic reasoning data.
Three-stage data mixing: Pre-training adopts a three-stage data mixing strategy, with MiMo-7B-Base pre-trained on approximately 25 trillion tokens.
Multi-token prediction: Introduced multi-token prediction as an additional training objective to boost model performance and accelerate inference.
Post-training
High-quality training data: Carefully selected 130K math and code problems as RL training data, with each problem thoroughly cleaned and difficulty-evaluated, and rule-based verifiers used to ensure data quality.
Code reward mechanism: For challenging code problems, introduced a test-difficulty-driven code reward, assigning fine-grained scores to test cases of varying difficulty to optimize the strategy.
Data resampling: Implemented a data resampling strategy for simple problems to improve rollout sampling efficiency and stabilize policy updates.
RL Infrastructure
Seamless rollout engine: Developed a seamless rollout engine that integrates continuous rollout, asynchronous reward computation, and early termination, reducing GPU idle time and achieving 2.29x faster training and 1.96x faster validation.
MTP support: Supports MTP in vLLM and enhances the robustness of the inference engine in the RL system.
MiMo Model Versions
MiMo-7B-Base: Foundation model with exceptional reasoning potential
MiMo-7B-RL-Zero: RL model trained from the base model
MiMo-7B-SFT: SFT model trained from the base model
MiMo-7B-RL: RL model trained from the SFT model, with performance comparable to OpenAI o1-mini.
Technical Details and Innovations
Pre-training data optimization: Multi-dimensional data filtering and synthetic reasoning data generation improved the quality of pre-training data and the density of reasoning patterns.
MTP module: Introducing the MTP module in pre-training significantly boosted performance and inference speed on reasoning tasks.
RL infrastructure: Developed a Seamless Rollout Engine that accelerated RL training and validation, achieving 2.29x and 1.96x speedups respectively.
Test-difficulty-driven reward mechanism: To address the sparse reward problem in code tasks, proposed a test-difficulty-based reward mechanism that improved the model's learning efficiency on difficult problems.
Experiments and Results
Pre-trained Model Performance
MiMo-7B-Base: Surpassed other open-source models at the 7B parameter scale across multiple benchmarks, such as BBH and SuperGPQA.
Reasoning potential evaluation: Used the pass@k metric to evaluate the model's reasoning potential; MiMo-7B-Base achieved higher pass@k scores across all benchmarks.
Post-trained Model Performance
MiMo-7B-RL-Zero: RL trained directly from MiMo-7B-Base, demonstrating strong reasoning capabilities.
MiMo-7B-RL: RL trained from the SFT model, ultimately surpassing OpenAI's o1-mini on math and code tasks.
Specific results:
On AIME 2025, MiMo-7B-RL scored 55.4, outperforming o1-mini by 4.7 points.
On LiveCodeBench v5 and v6, MiMo-7B-RL significantly outperformed o1-mini.
Related Links
Hugging Face:https://huggingface.co/XiaomiMiMo
GitHub Repository:https://github.com/XiaomiMiMo/MiMo
Technical Report:https://github.com/XiaomiMiMo/MiMo/blob/main/MiMo-7B-Technical-Report.pdf









