
 Script Planner Assistant▸
 AI Apps
 AI News
LiveCC: A Real-Time Video LLM Co-Developed by ByteDance and the National University of Singapore
小编 ·

LiveCC: A Real-Time Video LLM Co-Developed by ByteDance and the National University of Singapore
What is LiveCC?
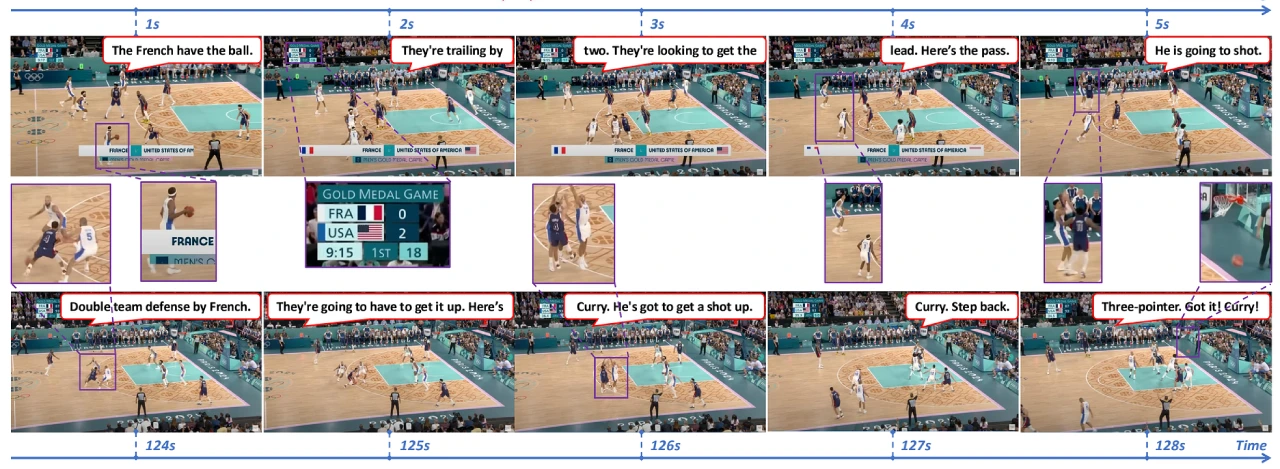
LiveCC is a video large language model developed in collaboration between ByteDance and the National University of Singapore, capable of providing real-time commentary on video content. It is trained using automatic speech recognition (ASR) transcripts, making it low-cost and highly efficient. The researchers also developed a new streaming training method and a data production pipeline, resulting in two datasets: Live-CC-5M and Live-WhisperX-526K. Even without high-quality supervised fine-tuning, the LiveCC-7B-Base model performs remarkably well in video question-answering and real-time commentary. Evaluated on the LiveSports-3K benchmark, the final LiveCC-7B-Instruct model surpasses a 72B state-of-the-art model in real-time commentary quality, and also achieves top-tier results on video question-answering benchmarks such as VideoMME and OVOBench.
Core Features of LiveCC
Model Training Methods
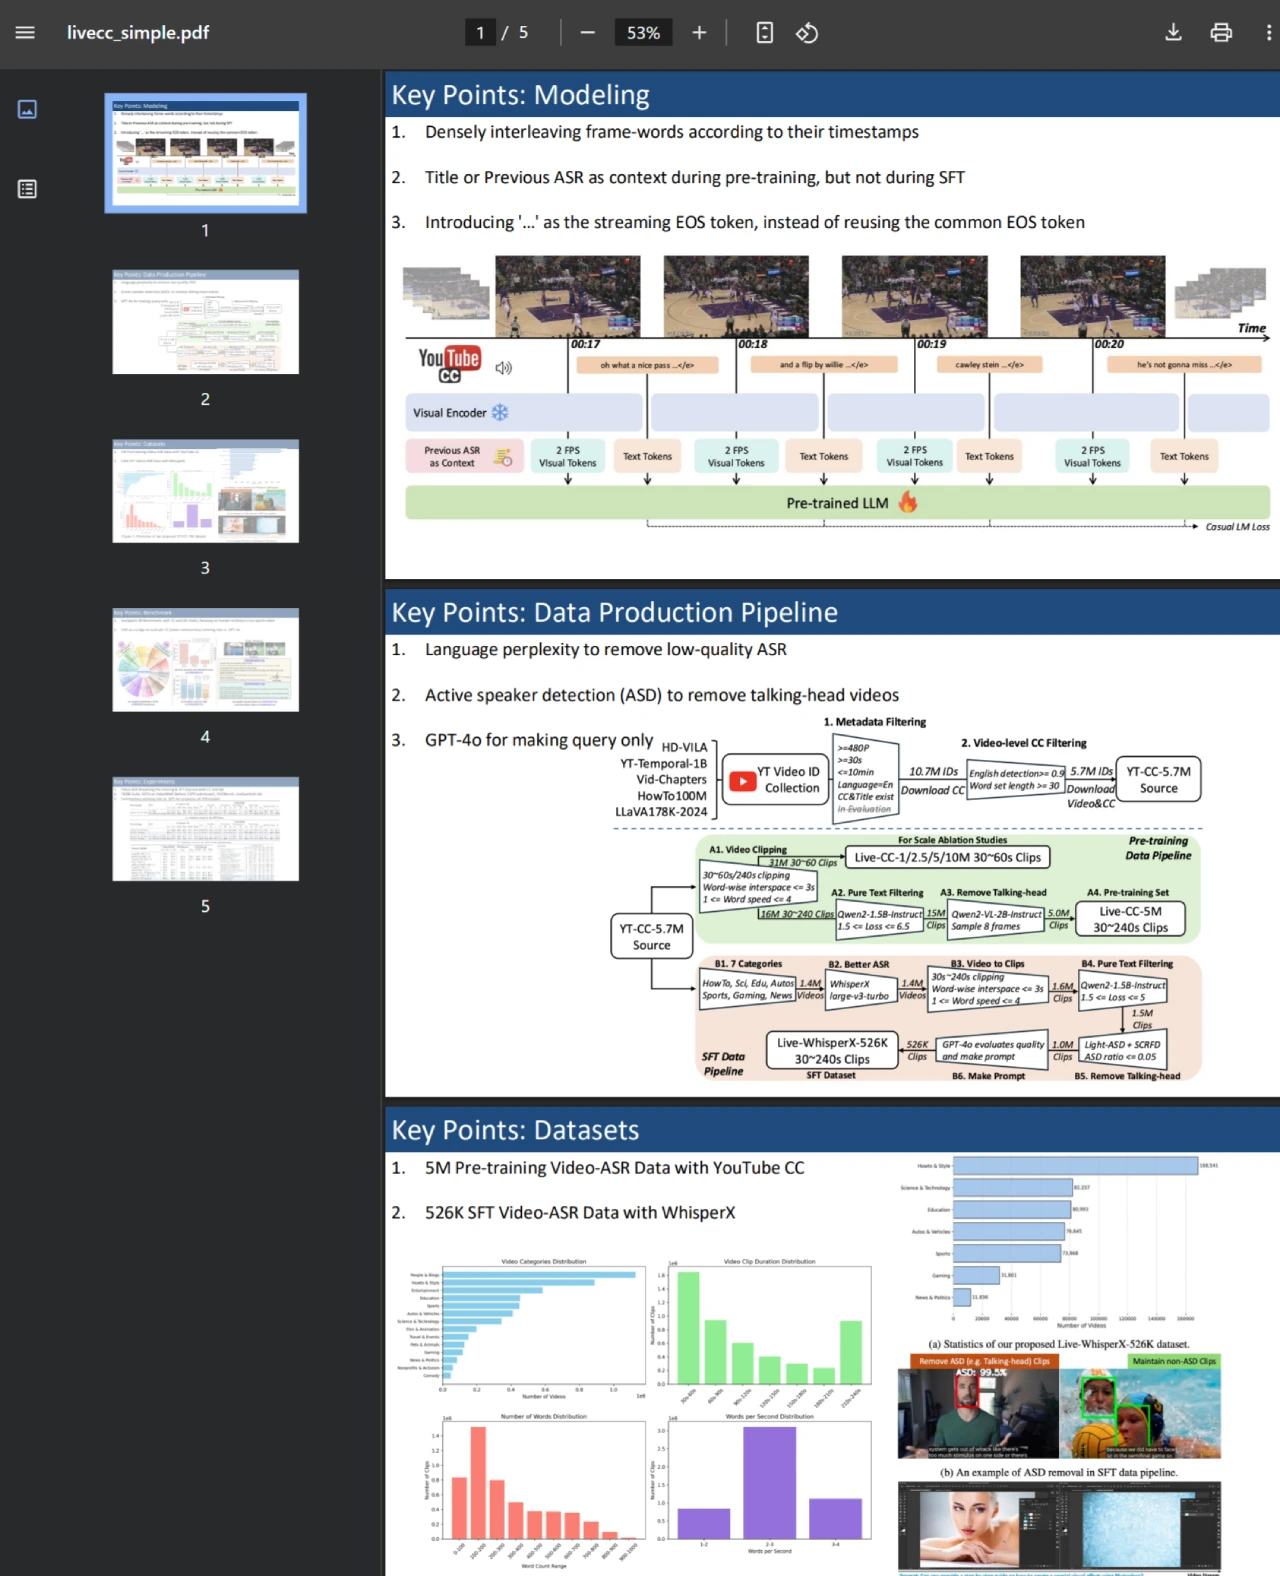
Innovative Training Approach: Proposes a novel video-ASR streaming training method that closely interleaves ASR words with video frames based on timestamps, aligning with the streaming nature of ASR and enabling the model to learn temporal alignment and fine-grained vision-language modeling.
Data Production and Dataset Construction: Introduces a data production pipeline that processes YouTube videos along with their subtitles (CC, equivalent to ASR), constructing the Live-CC-5M dataset for pre-training and the Live-WhisperX-526K dataset for high-quality supervised fine-tuning (SFT).
Model Performance
LiveCC-7B-Base Model: Even without SFT, this model demonstrates competitive performance on general video question-answering tasks and exhibits a new capability for real-time video commentary.
LiveCC-7B-Instruct Model: Evaluated using the carefully designed LiveSports-3K benchmark (which uses an LLM as a judge to measure free-form commentary), this model's real-time commentary quality surpasses that of advanced 72B models (such as Qwen2.5-VL-72B-Instruct and LLaVA-Video-72B). On popular video question-answering benchmarks (such as VideoMME and OVOBench), it achieves state-of-the-art results at the 7B/8B scale, demonstrating the broad generalizability of the approach.
LiveCC Applications
LiveCC can be widely applied in areas such as real-time interpretation of video content, real-time commentary on sporting events, and interactive explanation of educational videos.
Frequently Asked Questions
Q: How does LiveCC differ from other video large language models in terms of training data acquisition?
A: LiveCC leverages inexpensive automatic speech recognition (ASR) transcripts for large-scale training, while other models often rely on costly manual annotations or proprietary model APIs (such as GPT-4o). This difference gives LiveCC an advantage in terms of training data cost and scalability.
Q: What roles do the Live-CC-5M and Live-WhisperX-526K datasets play?
A: The Live-CC-5M dataset is used for model pre-training, helping the model learn general vision-language features and knowledge; the Live-WhisperX-526K dataset is used for high-quality supervised fine-tuning (SFT), enabling the model to perform better on specific tasks and improving its overall performance.
Q: What is the significance of the LiveCC-7B-Instruct model surpassing a 72B model in real-time commentary?
A: It demonstrates that LiveCC's training method and model architecture are effective, enabling more efficient real-time commentary with a smaller parameter count. This provides a more cost-effective solution for the deployment of video large language models in real-time application scenarios (such as live sports commentary).
Related Links
GitHub Repository:https://github.com/showlab/livecc
Releases Page:https://github.com/showlab/livecc/releases
Project Homepage:https://showlab.github.io/livecc/
Paper Link:https://arxiv.org/abs/2504.06885
Online Demo:https://huggingface.co/spaces/chenjoya/LiveCC









