
 Script Planner Assistant▸
 AI Apps
 AI News
Crawl4AI: An Open-Source AI-Friendly Web Crawler and Scraper
小编 ·

Crawl4AI: An Open-Source AI-Friendly Web Crawler and Scraper
What is Crawl4ai?
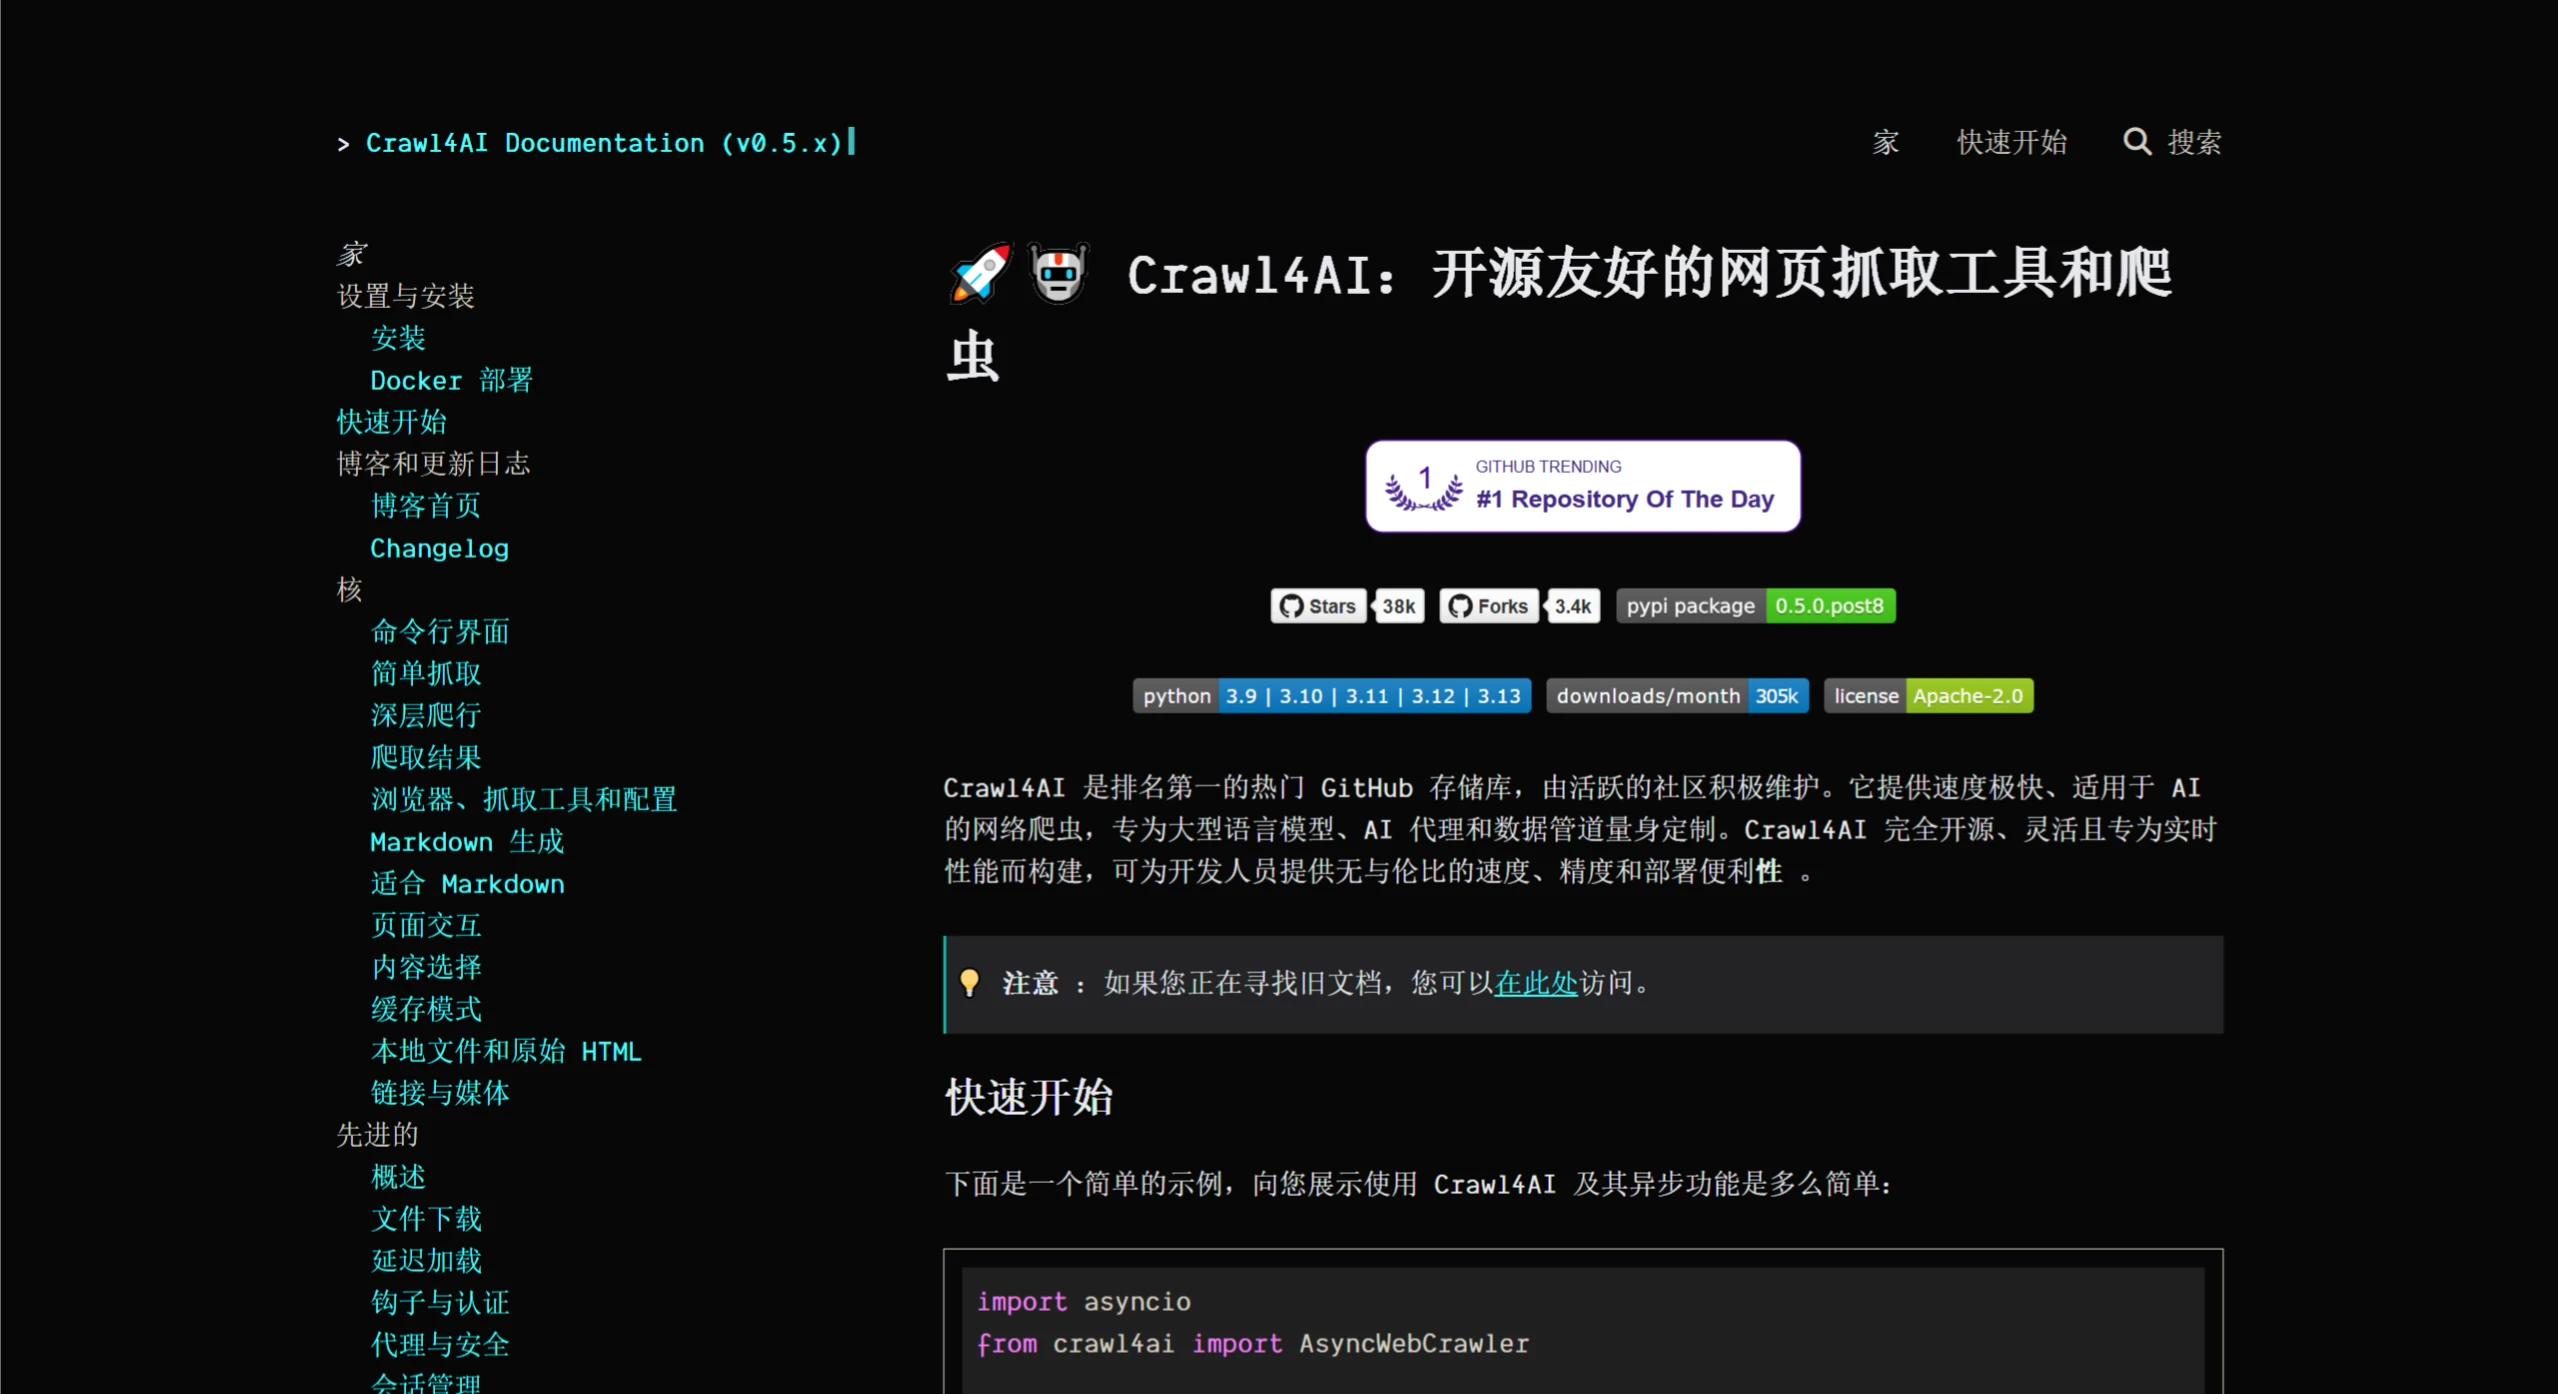
Crawl4AI is an open-source AI-friendly web crawler and scraper, a popular project on GitHub, designed for LLMs, AI agents, and data pipelines. It supports fast and flexible web data extraction, generates Markdown-formatted data suitable for LLMs, and features structured data extraction, browser integration, and dynamic content handling.
Crawl4AI Features
Markdown Generation
Clean Markdown: Generates well-structured, accurately formatted Markdown text.
Fit Markdown: Filters out noise and irrelevant content based on heuristic algorithms to generate Markdown suitable for AI processing.
Citations and References: Converts page links into a numbered reference list with clear citations.
Custom Strategies: Users can create their own Markdown generation strategies to meet specific needs.
BM25 Algorithm: Filters content based on the BM25 algorithm to extract core information and remove irrelevant content.
Structured Data Extraction
LLM-Driven Extraction: Supports all LLMs (open-source and proprietary) for structured data extraction.
Chunking Strategies: Implements topic-based, regex-based, and sentence-level chunking.
Cosine Similarity: Finds relevant content chunks based on user queries for semantic extraction.
CSS-Based Extraction: Uses XPath and CSS selectors for fast, patterned data extraction.
Schema Definition: Defines custom schemas to extract structured JSON data from repetitive patterns.
Browser Integration
Managed Browser: Uses the user's own browser to avoid being detected as a crawler.
Remote Browser Control: Connects to remote browsers via the Chrome Developer Tools protocol for large-scale data extraction.
Browser Profiles: Creates and manages persistent profiles to save authentication state, cookies, and settings.
Session Management: Preserves and reuses browser state to support multi-step crawling.
Proxy Support: Seamlessly connects to authenticated proxies to ensure secure access.
Full Browser Control: Modifies request headers, cookies, user agents, etc., to customize crawling settings.
Multi-Browser Support: Compatible with Chromium, Firefox, and WebKit.
Dynamic Viewport Adjustment: Automatically adjusts the browser viewport to match page content, ensuring complete rendering and capturing all elements.
Crawling and Scraping
Media Support: Extracts images, audio, videos, and responsive image formats (such as srcset and picture).
Dynamic Crawling: Executes JavaScript and waits for async or sync content to extract dynamic content.
Screenshots: Captures page screenshots during crawling for debugging or analysis.
Raw Data Crawling: Directly processes raw HTML (raw:) or local files (file://).
Comprehensive Link Extraction: Extracts internal, external links, and embedded iframe content.
Custom Hooks: Defines hooks at each step to customize crawling behavior.
Caching: Caches data to improve speed and avoid repeated scraping.
Metadata Extraction: Extracts structured metadata from web pages.
Iframe Content Extraction: Seamlessly extracts embedded iframe content.
Lazy Loading Handling: Waits for images to fully load to ensure no content is missed due to lazy loading.
Full-Page Scanning: Simulates scrolling to load and capture all dynamic content, suitable for infinite scroll pages.
Other Features
Stealth Mode: Avoids being detected as a crawler by mimicking real user behavior.
Tag-Based Content Extraction: Refines crawled content based on custom tags, headings, or metadata.
Link Analysis: Extracts and analyzes all links for detailed data exploration.
Error Handling: Robust error management to ensure seamless execution.
CORS and Static Serving: Supports file-system-based caching and cross-origin requests.
Clear Documentation: Simplified getting-started and advanced usage guides.
Crawl4AI Advantages
Tailored for LLMs: Generates intelligent, concise Markdown suitable for RAG and fine-tuning applications.
Blazing-Fast Performance: Real-time, cost-efficient performance, up to 6 times faster than traditional methods.
Flexible Browser Control: Provides session management, proxy support, and custom hooks to ensure seamless data access.
Heuristic Intelligence: Uses advanced algorithms to efficiently extract content, reducing reliance on expensive models.
Open Source and Deployable: Fully open source, no API key required, supports Docker and cloud integration.
Crawl4AI Use Cases
AI and Machine Learning: Provides high-quality training data for LLMs, supporting natural language processing and knowledge graph construction.
Data Pipelines: Builds efficient data pipelines to extract and process web data in real time.
Content Extraction: Extracts text, images, videos, and other multimedia content from web pages for content management systems.
Academic Research: Helps researchers extract papers and research data from web pages to support academic research work.
Business Intelligence: Extracts market data, product information, and user reviews to support business decisions.
News Media: Quickly scrapes news content to support news aggregation and content analysis.
Crawl4AI Installation and Usage Tutorial
Installation
Basic Installation:
pip install crawl4ai
crawl4ai-setup  # Set up the browser
Install Pre-release Version:
pip install crawl4ai --pre
Development Installation:
git clone https://github.com/unclecode/crawl4ai.git
cd crawl4ai
pip install -e .  # Basic installation
pip install -e ".[all]"  # Install all optional features
Github Address:https://github.com/unclecode/crawl4ai
Crawl4AI Documentation:https://docs.crawl4ai.com/
Discord:https://discord.com/invite/jP8KfhDhyN









