
 Script Planner Assistant▸
 AI Apps
 AI News
OmniTalker: Alibaba's Real-Time Text-Driven Talking Avatar Framework
小编 ·

OmniTalker: Alibaba's Real-Time Text-Driven Talking Avatar Framework
What is OmniTalker?
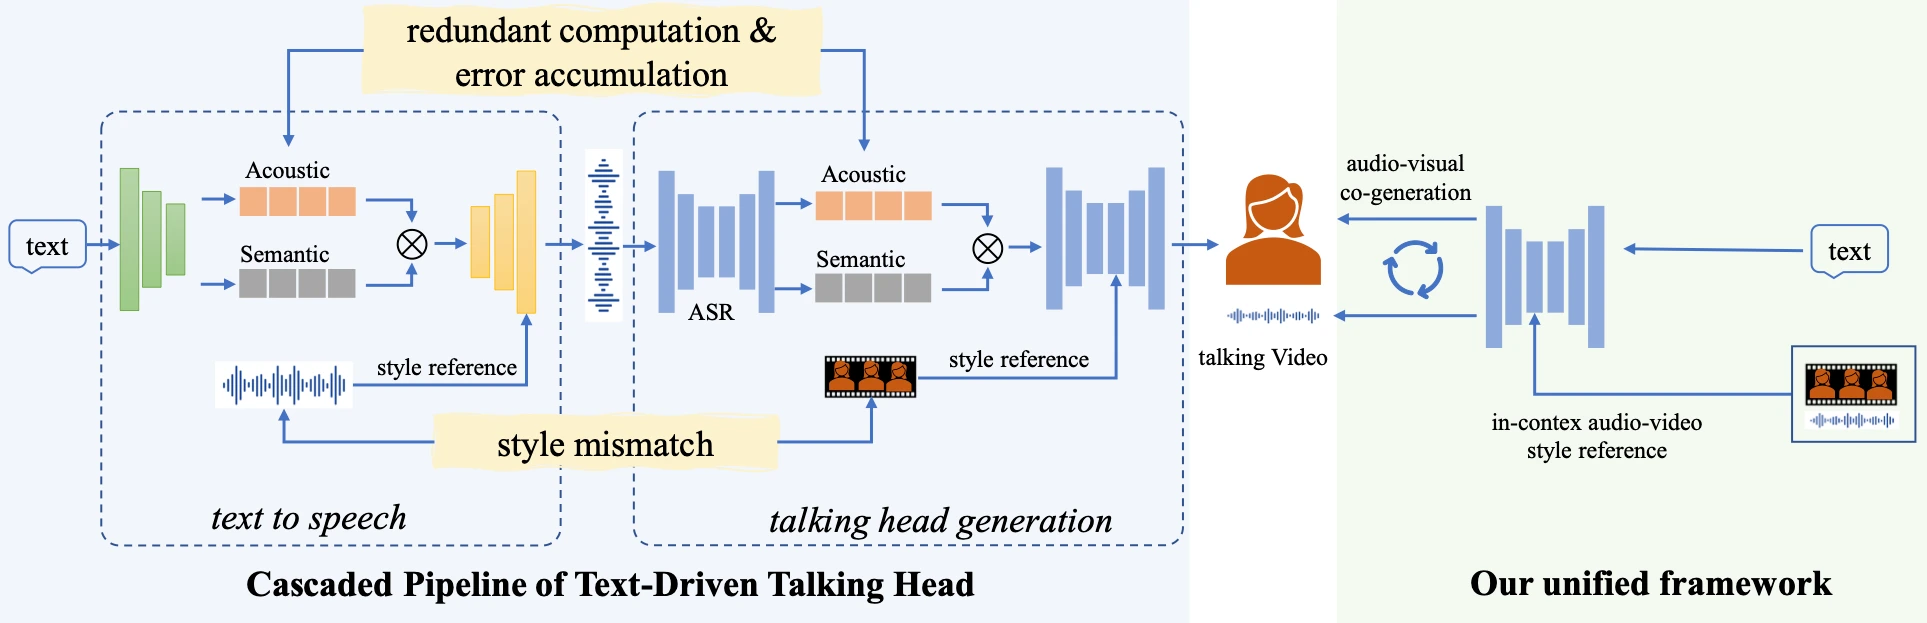
OmniTalker is a real-time, text-driven talking avatar AI multimodal generation framework developed by Alibaba's Tongyi Lab. It can generate matching speech and video animations in real time based on the input text. The generated speech and video are not only high-quality, but also realistically simulate facial expressions and head movements, as if a real "digital human" is talking to you. OmniTalker supports Chinese-English mutual conversion, supports emotional expression such as calm, happy, sad, angry and other emotions, and supports long-form video generation.
OmniTalker Features
Multimodal input processing: Capable of perceiving multiple modalities including text, images, audio, and video.
Streaming generation: Generates text and natural speech responses in a streaming fashion, with audio and video encoders adopting a chunk-by-chunk processing approach, decoupling the handling of long-sequence multimodal data.
Precise audio-video synchronization: Ensures precise synchronization between video and audio inputs through TMRoPE technology.
Real-time interaction: Supports chunked input and instant output, enabling fully real-time interaction.
Natural and smooth speech generation: Performs excellently in terms of naturalness and stability of speech generation, surpassing many existing streaming and non-streaming alternatives.
Performance advantages: Performs well on multimodal benchmarks, with audio capabilities superior to similarly sized Qwen2-Audio, and on par with Qwen2.5-VL-7B.
OmniTalker Core Technology
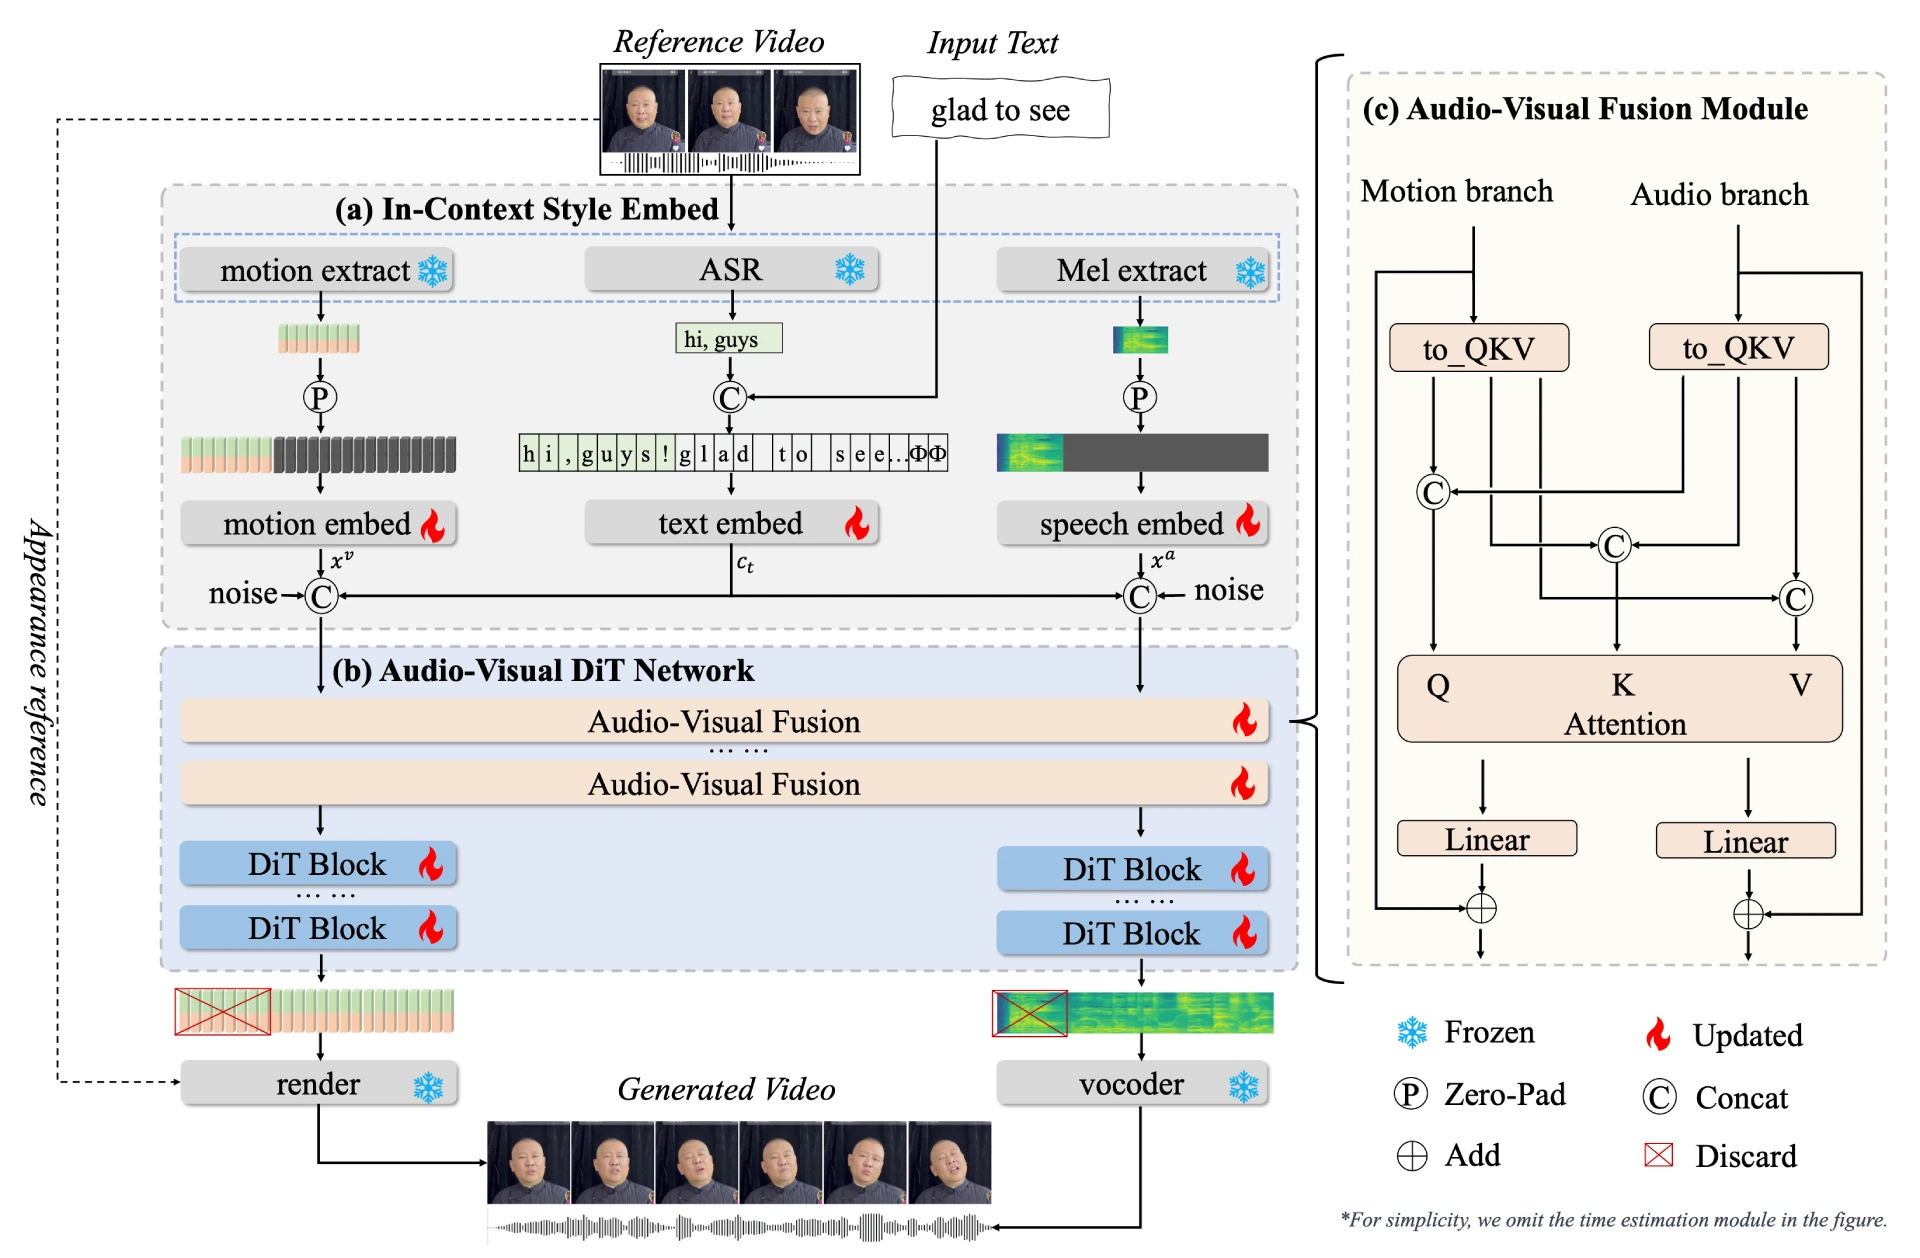
1. Dual-branch Diffusion Transformer (DiT) Architecture
Includes an audio branch and a visual branch:
Audio branch: Synthesizes high-quality speech from text.
Visual branch: Predicts head pose and facial dynamics.
A novel audio-visual fusion module ensures temporal synchronization and stylistic consistency between audio and video outputs.
2. In-context Reference Learning
OmniTalker can capture speech and facial style features from a single reference video without needing additional style extraction modules. This means that regardless of the input text, OmniTalker can generate speech and video content that is highly consistent with the style of the reference video.
3. Real-time and High Efficiency
OmniTalker can generate speech and video in real time at 25 FPS, which is highly leading among similar technologies. This efficient inference speed enables OmniTalker to be applied to scenarios such as real-time video chat and virtual livestreaming, delivering a smooth interactive experience for users.
OmniTalker Application Scenarios
Intelligent voice assistant: Processes user voice commands and generates real-time voice responses.
Multimodal content creation: Simultaneously processes text, image, and video inputs to generate corresponding text or voice descriptions.
Education and training: Generates virtual teachers that produce speech and video based on teaching content.
Virtual customer service and assistants: Creates virtual customer service or assistants that generate real-time voice and video responses.
Entertainment and media: Creates virtual anchors, actors, and generates performance content in real time.
OmniTalker Advantages
High-quality generation: The generated speech and video content is of high quality, accurately replicating the style of the reference video, including subtle changes in speech intonation, rhythm, and facial expressions.
Zero-shot learning: No need for large amounts of training data; can quickly generate content based on input text and reference video, adapting to different scenarios and needs.
Real-time interaction: Generates speech and video in real time at 25 FPS with low latency, suitable for scenarios such as real-time video chat and virtual livestreaming.
Project website:https://humanaigc.github.io/omnitalker/
Technical paper:https://arxiv.org/pdf/2504.02433v1









