
 Script Planner Assistant▸
 AI Apps
 AI News
Speech-02: A Powerful Text-to-Speech (TTS) Model by MiniMax Audio
小编 ·

Speech-02: A Powerful Text-to-Speech (TTS) Model by MiniMax Audio
What is Speech-02?
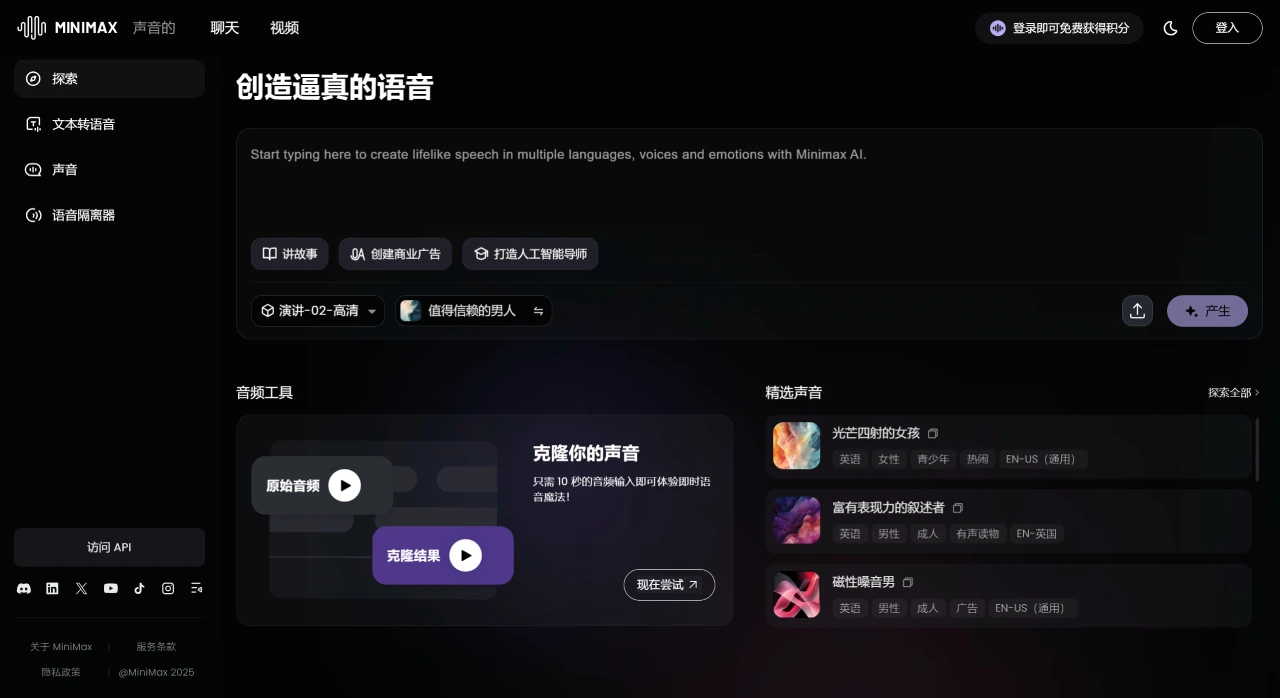
MiniMax Audio Speech-02 is a powerful text-to-speech (TTS) model that can instantly convert any file or URL into lifelike audio. It supports single inputs of up to 200,000 characters, covers more than 30 languages, and comes with authentic accents. In addition, Speech-02 supports unlimited voice cloning, sub-second streaming processing, and multiple audio formats (such as FLAC, WAV, MP3, and PCM).
The Speech-02 model comes in two versions: speech-02-hd-preview (featuring 99% voice similarity and studio-grade clarity, ideal for dubbing, audiobooks, and other scenarios that demand lifelike performance) and speech-02-turbo-preview (which strikes a balance between low latency and high performance, suitable for real-time applications).
Language and Voice Capabilities
Multilingual Support: Speech-02 supports text-to-speech in more than 30 languages, including English, Chinese, Japanese, Korean, French, German, Spanish, Portuguese, Italian, Arabic, Russian, Turkish, Dutch, Ukrainian, Vietnamese, Hindi, Thai, Polish, Romanian, Greek, Finnish, and Indonesian, with authentic accents.
Rich Voice Library: Features over 300 natural, lifelike voices that deliver authentic expression across multiple languages.
Technical Performance
Single-Input Character Limit: Supports single inputs of up to 200,000 characters.
Streaming Processing Speed: Supports sub-second streaming processing.
Model Versions: Includes speech-02-hd-preview and speech-02-turbo-preview. The former is characterized by 99% voice similarity and studio-grade clarity, making it ideal for dubbing, audiobooks, and other scenarios that require lifelike performance; the latter strikes a balance between low latency and high performance, suitable for real-time applications.
Speech-02 Features
Unlimited Voice Cloning: Capable of rapidly cloning voices in multiple styles and tones with industry-leading quality.
Voice Control: Users can easily control the emotion, volume, speed, and output format of the voice.
Voice Mixing: Existing voices can be combined to create entirely new and unique voices.
Audio Format Support: Supports multiple audio formats, including FLAC, WAV, MP3, and PCM.
Speech-02 Use Cases
Audiobook Production: Ideal for converting novels, academic papers, and other long-form content into high-quality audio.
Podcast Creation: Helps podcast creators produce more engaging and diverse content.
Film and Game Dubbing: Provides cinema-grade low frequencies and immersive audio effects.
International Conferences and Translation: Supports instant, seamless switching between multiple languages.
Currently, the Speech-02 model has been launched on the MiniMax Audio platform and API platform, but the domestic version has not yet been released.
Official Links
MiniMax Audio Platform:https://www.minimax.io/audio
MiniMax Audio API Platform:https://www.minimax.io/platform









