
 Script Planner Assistant▸
 AI Apps
 AI News
QVQ-Max: Alibaba's Visual Reasoning Model That Understands Images and Videos
小编 ·

QVQ-Max: Alibaba's Visual Reasoning Model That Understands Images and Videos
What is QVQ-Max?
QVQ-Max is a visual reasoning model capable of understanding the content of images and videos. It can analyze and reason based on relevant information and provide solutions. The QVQ-Max model performs exceptionally well in multiple fields, such as solving math problems, handling everyday issues, programming assistance, and artistic creation.
Design Intent
Traditional AI models mostly rely on text input, yet in reality, a great deal of information is presented in the form of images, charts, or videos. QVQ-Max aims to build an assistant that is both skilled at capturing visual information and capable of rapid analysis, helping users solve a variety of practical problems.
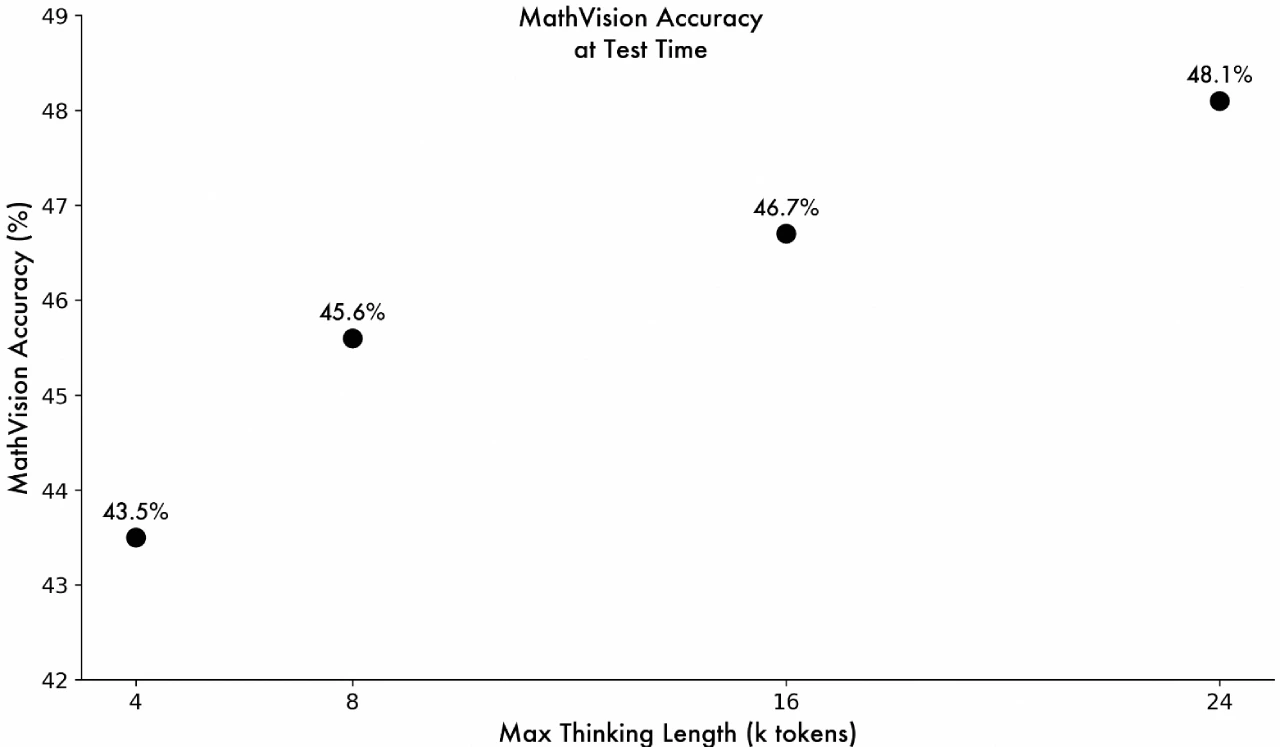
QVQ-Max Core Capabilities
Detailed Observation: QVQ-Max can quickly identify key elements in an image, capturing details whether it's a complex chart or an everyday photo.
In-Depth Reasoning: The model not only identifies content but also reasons based on background knowledge. For example, it can parse geometric figures and derive answers.
Flexible Application: Beyond analysis and reasoning, QVQ-Max can also be used for creation, such as designing illustrations, generating short video scripts, and even creating role-playing content based on user needs.
QVQ-Max Application Scenarios
Workplace Applications: Assists with data analysis, information organization, and programming tasks.
Learning Assistance: Helps solve challenging problems in subjects such as math and physics, especially those accompanied by diagrams.
Daily Life Assistance: Provides outfit suggestions based on wardrobe photos, or guides cooking operations based on recipe images.
QVQ-Max Tutorial
1. Go to https://chat.qwen.ai/
2. Select the QWQ-32B model
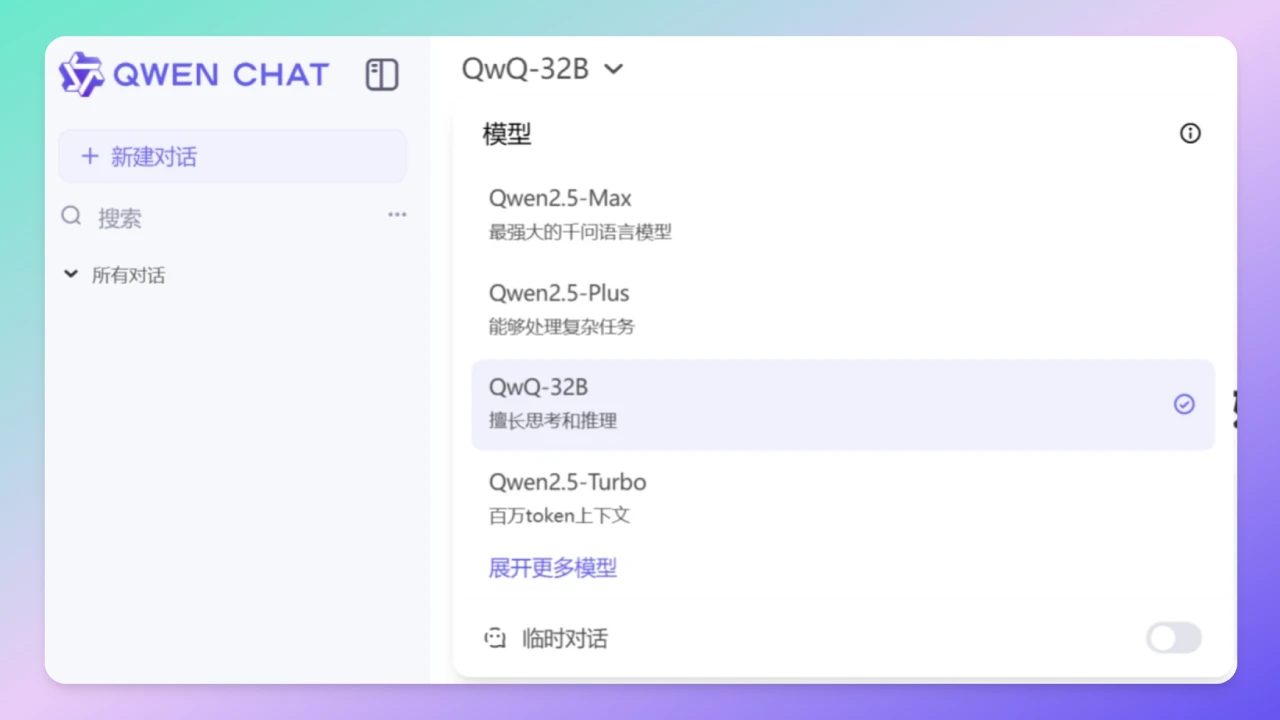
3. Click the "+" icon in the input box to upload an image or video.
4. Ask questions about the image content.
Future Development Directions
Enhanced Observation Capability: Leveraging visual content verification techniques (such as grounding) to improve recognition accuracy.
Strengthened Task-Handling Capability: Developing visual Agents to improve the ability to handle multi-step and complex tasks, such as operating phones, computers, or playing games.
Optimized Interactive Experience: Expanding interaction modalities to include tool verification and visual generation.
QVQ-Max, as a visual reasoning model, has enormous potential. It can not only recognize image content but also analyze and reason based on information, and even complete some creative tasks. Although this is only the first version, it has already demonstrated significant potential. In the future, it is expected to become a practical visual Agent, providing strong support for users to solve real-world problems.
Detailed Introduction: https://qwenlm.github.io/zh/blog/qvq-max-preview/
Access URL: https://chat.qwen.ai/









