
 Script Planner Assistant▸
 AI Apps
 AI News
Qwen2.5-Omni: Alibaba's End-to-End Multimodal Flagship Model
小编 ·

Qwen2.5-Omni: Alibaba's End-to-End Multimodal Flagship Model
What is Qwen2.5-Omni?
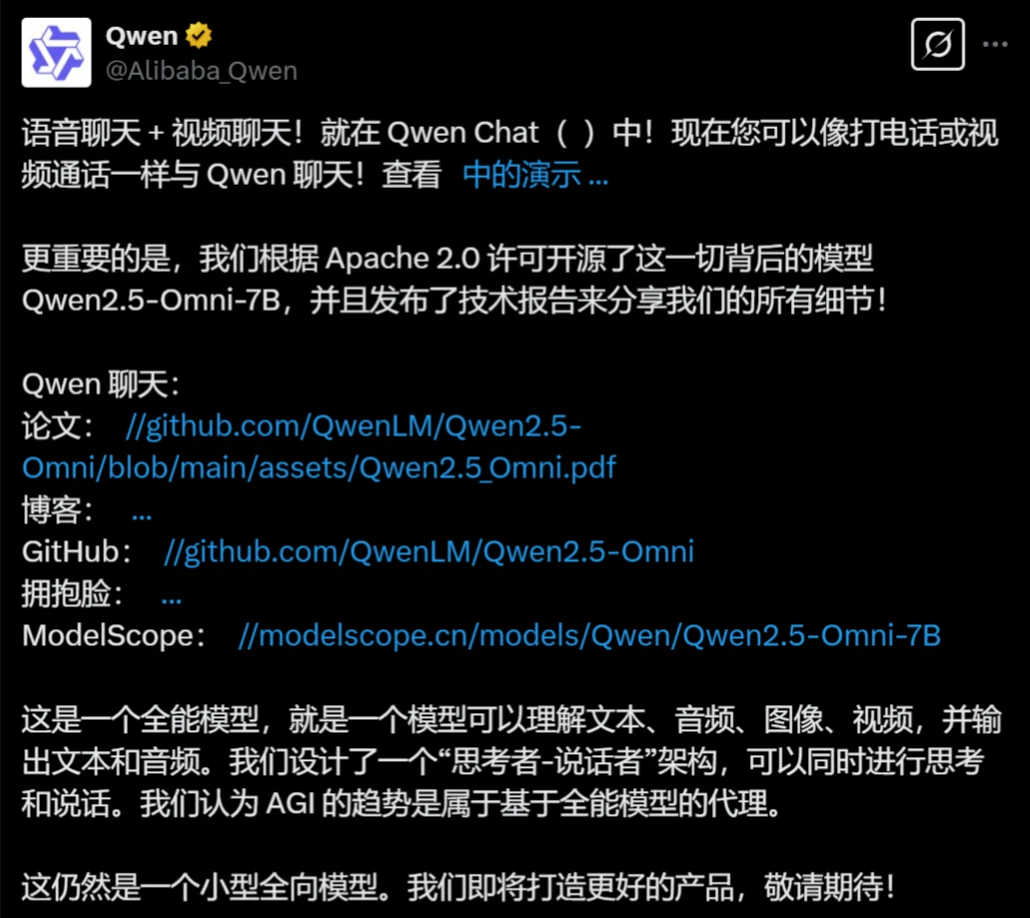
Qwen2.5-Omni is the new-generation end-to-end multimodal flagship model in the Qwen series released by Alibaba. It is designed for comprehensive multimodal perception, meaning it can understand text, audio, images, and video. It can simultaneously think and speak, and through real-time streaming response, it generates both text and natural speech synthesis output as an AI model.
Core Features of Qwen2.5-Omni
Innovative Architecture:
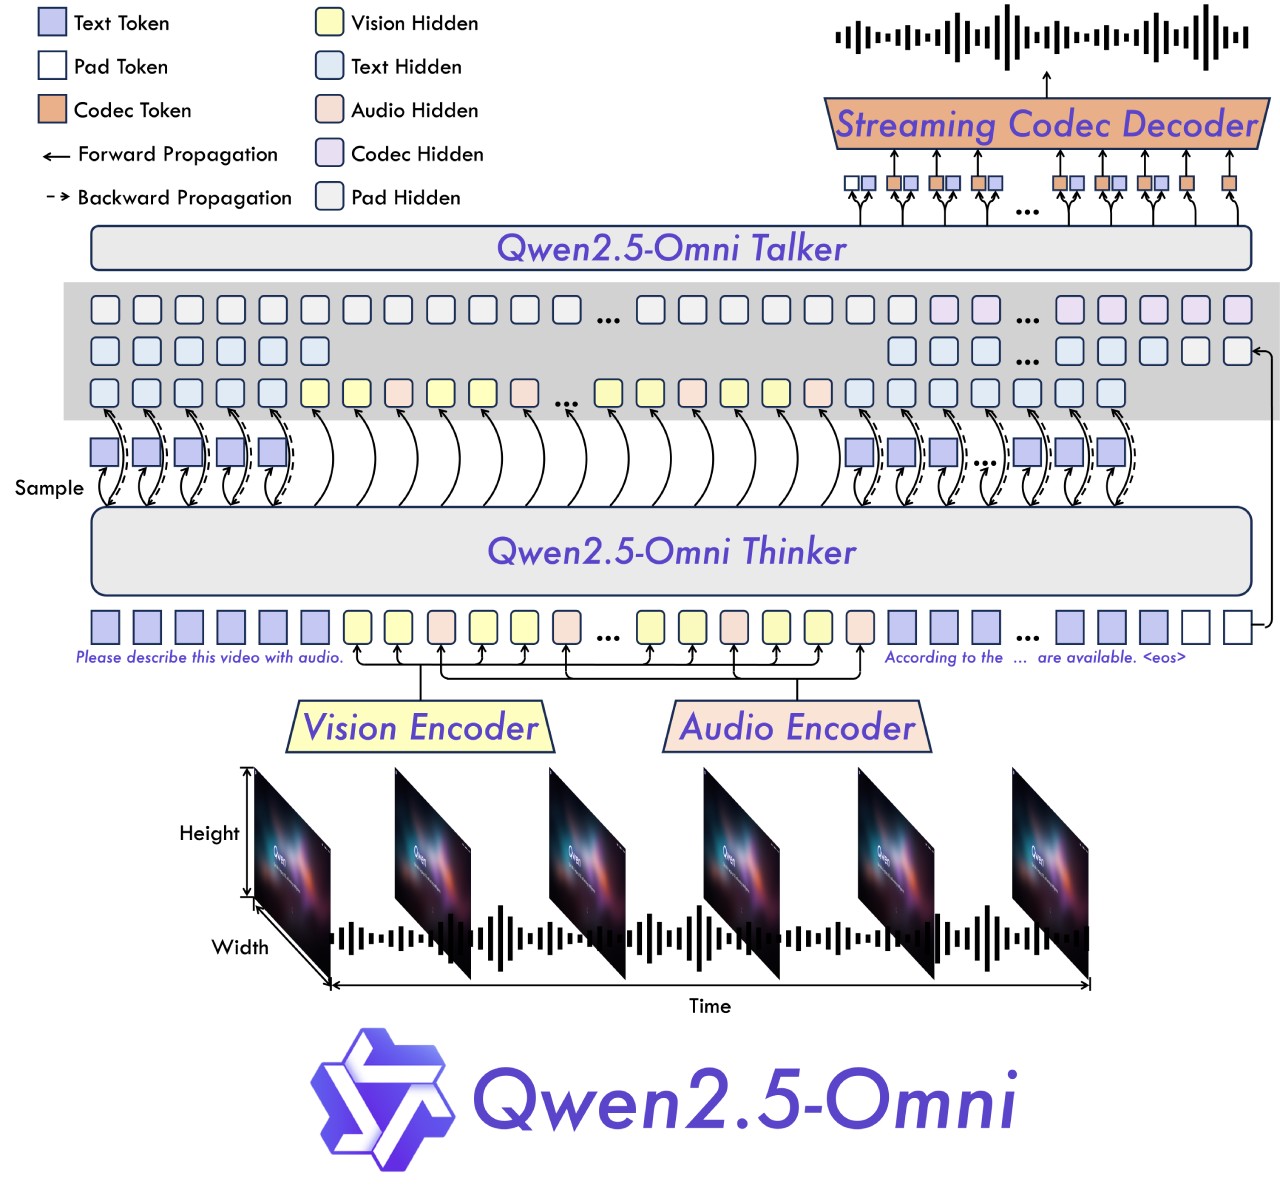
Thinker-Talker Architecture: Thinker is responsible for processing and understanding inputs from text, audio, and video modalities, generating high-level semantic representations and corresponding text content; Talker then converts this content into natural speech output.
TMRoPE Technology: A novel positional encoding technique called TMRoPE (Time-aligned Multimodal RoPE) is proposed for synchronizing the timestamps of video input with audio.
Real-Time Interaction:
Supports fully real-time interaction, capable of processing chunked inputs and producing outputs instantly.
Natural and Fluent Speech Generation:
Surpasses many existing streaming and non-streaming alternatives in terms of naturalness and stability of speech generation.
Omnimodal Performance Advantages:
Performs excellently on multimodal tasks (such as OmniBench), while also showing outstanding results on single-modality tasks (such as speech recognition, translation, audio understanding, image reasoning, video understanding, etc.).
End-to-End Speech Instruction-Following Capability:
Demonstrates end-to-end speech instruction-following performance comparable to text input processing, with excellent results on benchmarks such as MMLU and GSM8K.
Qwen2.5-Omni Architecture Design
Thinker: Similar to the brain, it is responsible for processing and understanding inputs from text, audio, and video modalities, generating high-level semantic representations and corresponding text content.
Talker: Similar to a human mouth, it receives the high-level semantic representations and text content generated by Thinker, and outputs natural speech in a streaming manner.
Overall Architecture: Thinker is a Transformer decoder equipped with encoders for audio and images to extract information. Talker is a dual-track autoregressive Transformer decoder architecture. During training and inference, Talker directly receives high-dimensional representations from Thinker and shares all the historical context information of Thinker. The entire architecture is trained and inferred end-to-end as a unified model.
Qwen2.5-Omni Performance
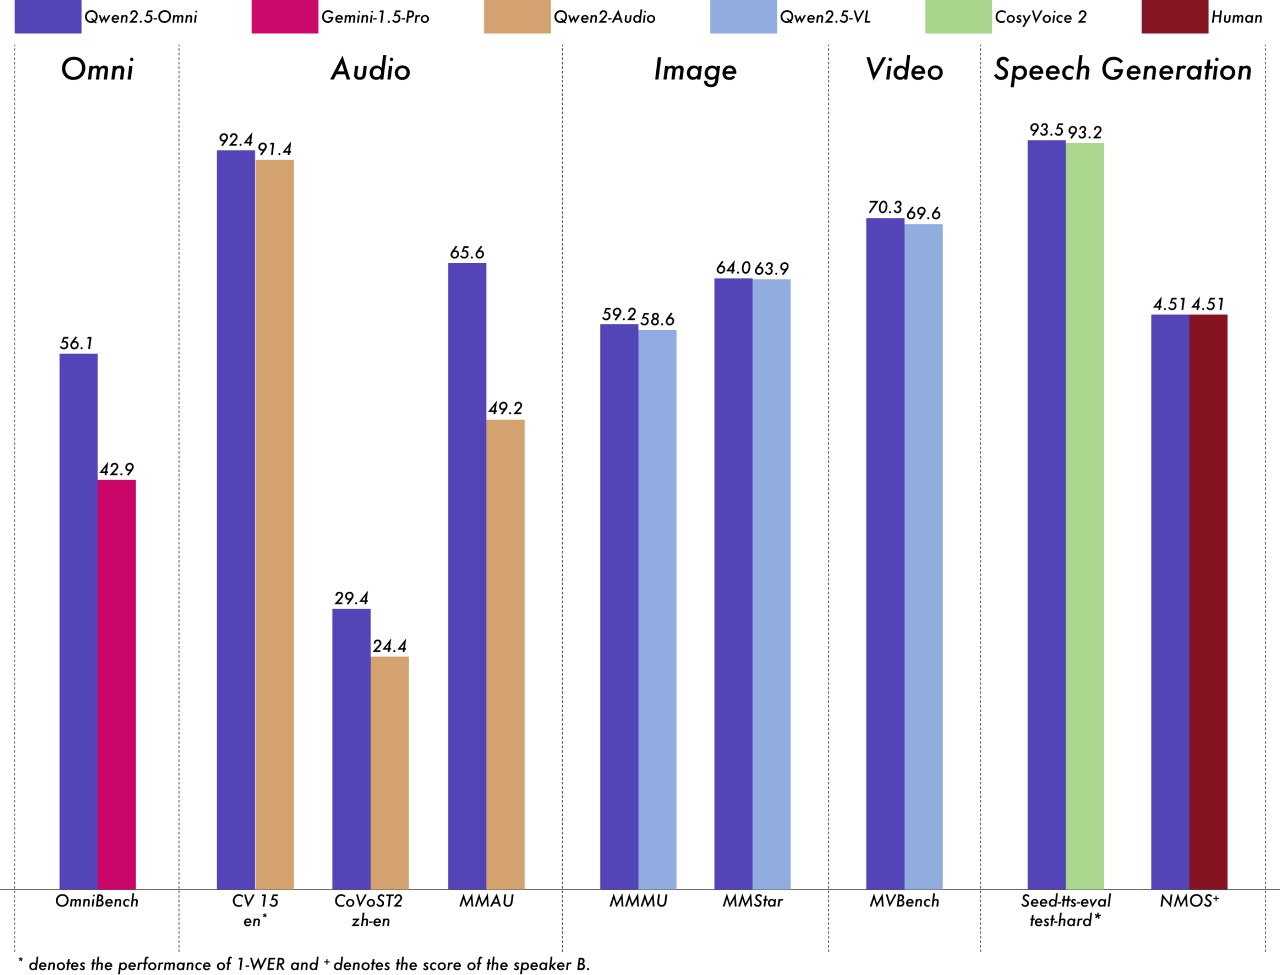
On multimodal tasks (such as OmniBench), Qwen2.5-Omni achieves state-of-the-art performance.
On single-modality tasks, it excels in speech recognition (Common Voice), translation (CoVoST2), audio understanding (MMAU), image reasoning (MMMU, MMStar), video understanding (MVBench), and speech generation (Seed-tts-eval and subjective naturalness).
Related Links
Qwen Chat:https://chat.qwenlm.ai
Hugging Face:https://huggingface.co/Qwen/Qwen2.5-Omni-7B
ModelScope:https://modelscope.cn/models/Qwen/Qwen2.5-Omni-7B
DashScope:https://help.aliyun.com/zh/model-studio/user-guide/qwen-omni
GitHub:https://github.com/QwenLM/Qwen2.5-Omni
Demo Experience:https://modelscope.cn/studios/Qwen/Qwen2.5-Omni-Demo









