
 Script Planner Assistant▸
 AI Apps
 AI News
OpenAI Released Three New Voice Models: Two Speech-to-Text and One Text-to-Speech
小编 ·

OpenAI Released Three New Voice Models: Two Speech-to-Text and One Text-to-Speech
On March 20, 2025, Openai released three brand-new voice models, including two speech-to-text models (GPT-4o-transcribe and GPT-4o-mini-transcribe) and one text-to-speech model (GPT-4o-mini-tts).
Speech-to-Text Models
GPT-4o-transcribe: This model has been trained for an extended period on diverse, high-quality audio datasets, enabling it to better capture the nuances of speech, reduce misrecognition, and significantly improve transcription reliability. It is well-suited for handling complex scenarios such as varied accents, noisy environments, and fluctuating speaking speeds—for example, in fields like customer call centers and meeting transcription.
GPT-4o-mini-transcribe: This is a streamlined version of GPT-4o-transcribe, offering faster speed and higher efficiency. Although its word error rate (WER) is slightly higher than that of the full version, it still outperforms the previous Whisper model, making it more suitable for application scenarios with limited resources that still require high-quality speech recognition.
Text-to-Speech Model
GPT-4o-mini-tts: This model is the first to support "steerability." Developers can not only specify what the model "says" but also control how it says it—for example, they can preset the voice style as "calm," "surfer," "professional," "medieval knight," etc., and adjust the voice style based on instructions, such as "speak like a compassionate customer service Agent."
Technical Innovations
Pre-training on real-world audio datasets to optimize model performance.
Enhanced distillation methods to achieve knowledge transfer from large models to small models.
Reinforcement learning to improve transcription accuracy and reduce "hallucination" phenomena.
Application Scenarios
Call centers: Delivering more accurate speech recognition and more natural speech synthesis to enhance the customer service experience.
Meeting records: Quickly and accurately transcribing spoken meeting content into text.
Personalized customer service: Providing a warmer and more expressive voice experience through customized voice styles.
Creative storytelling: Adding vivid voice effects to stories.
Pricing
GPT-4o-transcribe is priced the same as the previous Whisper model, at $0.006 per minute.
GPT-4o-mini-transcribe is priced at $0.003 per minute.
GPT-4o-mini-tts is priced at 1 cent per minute.
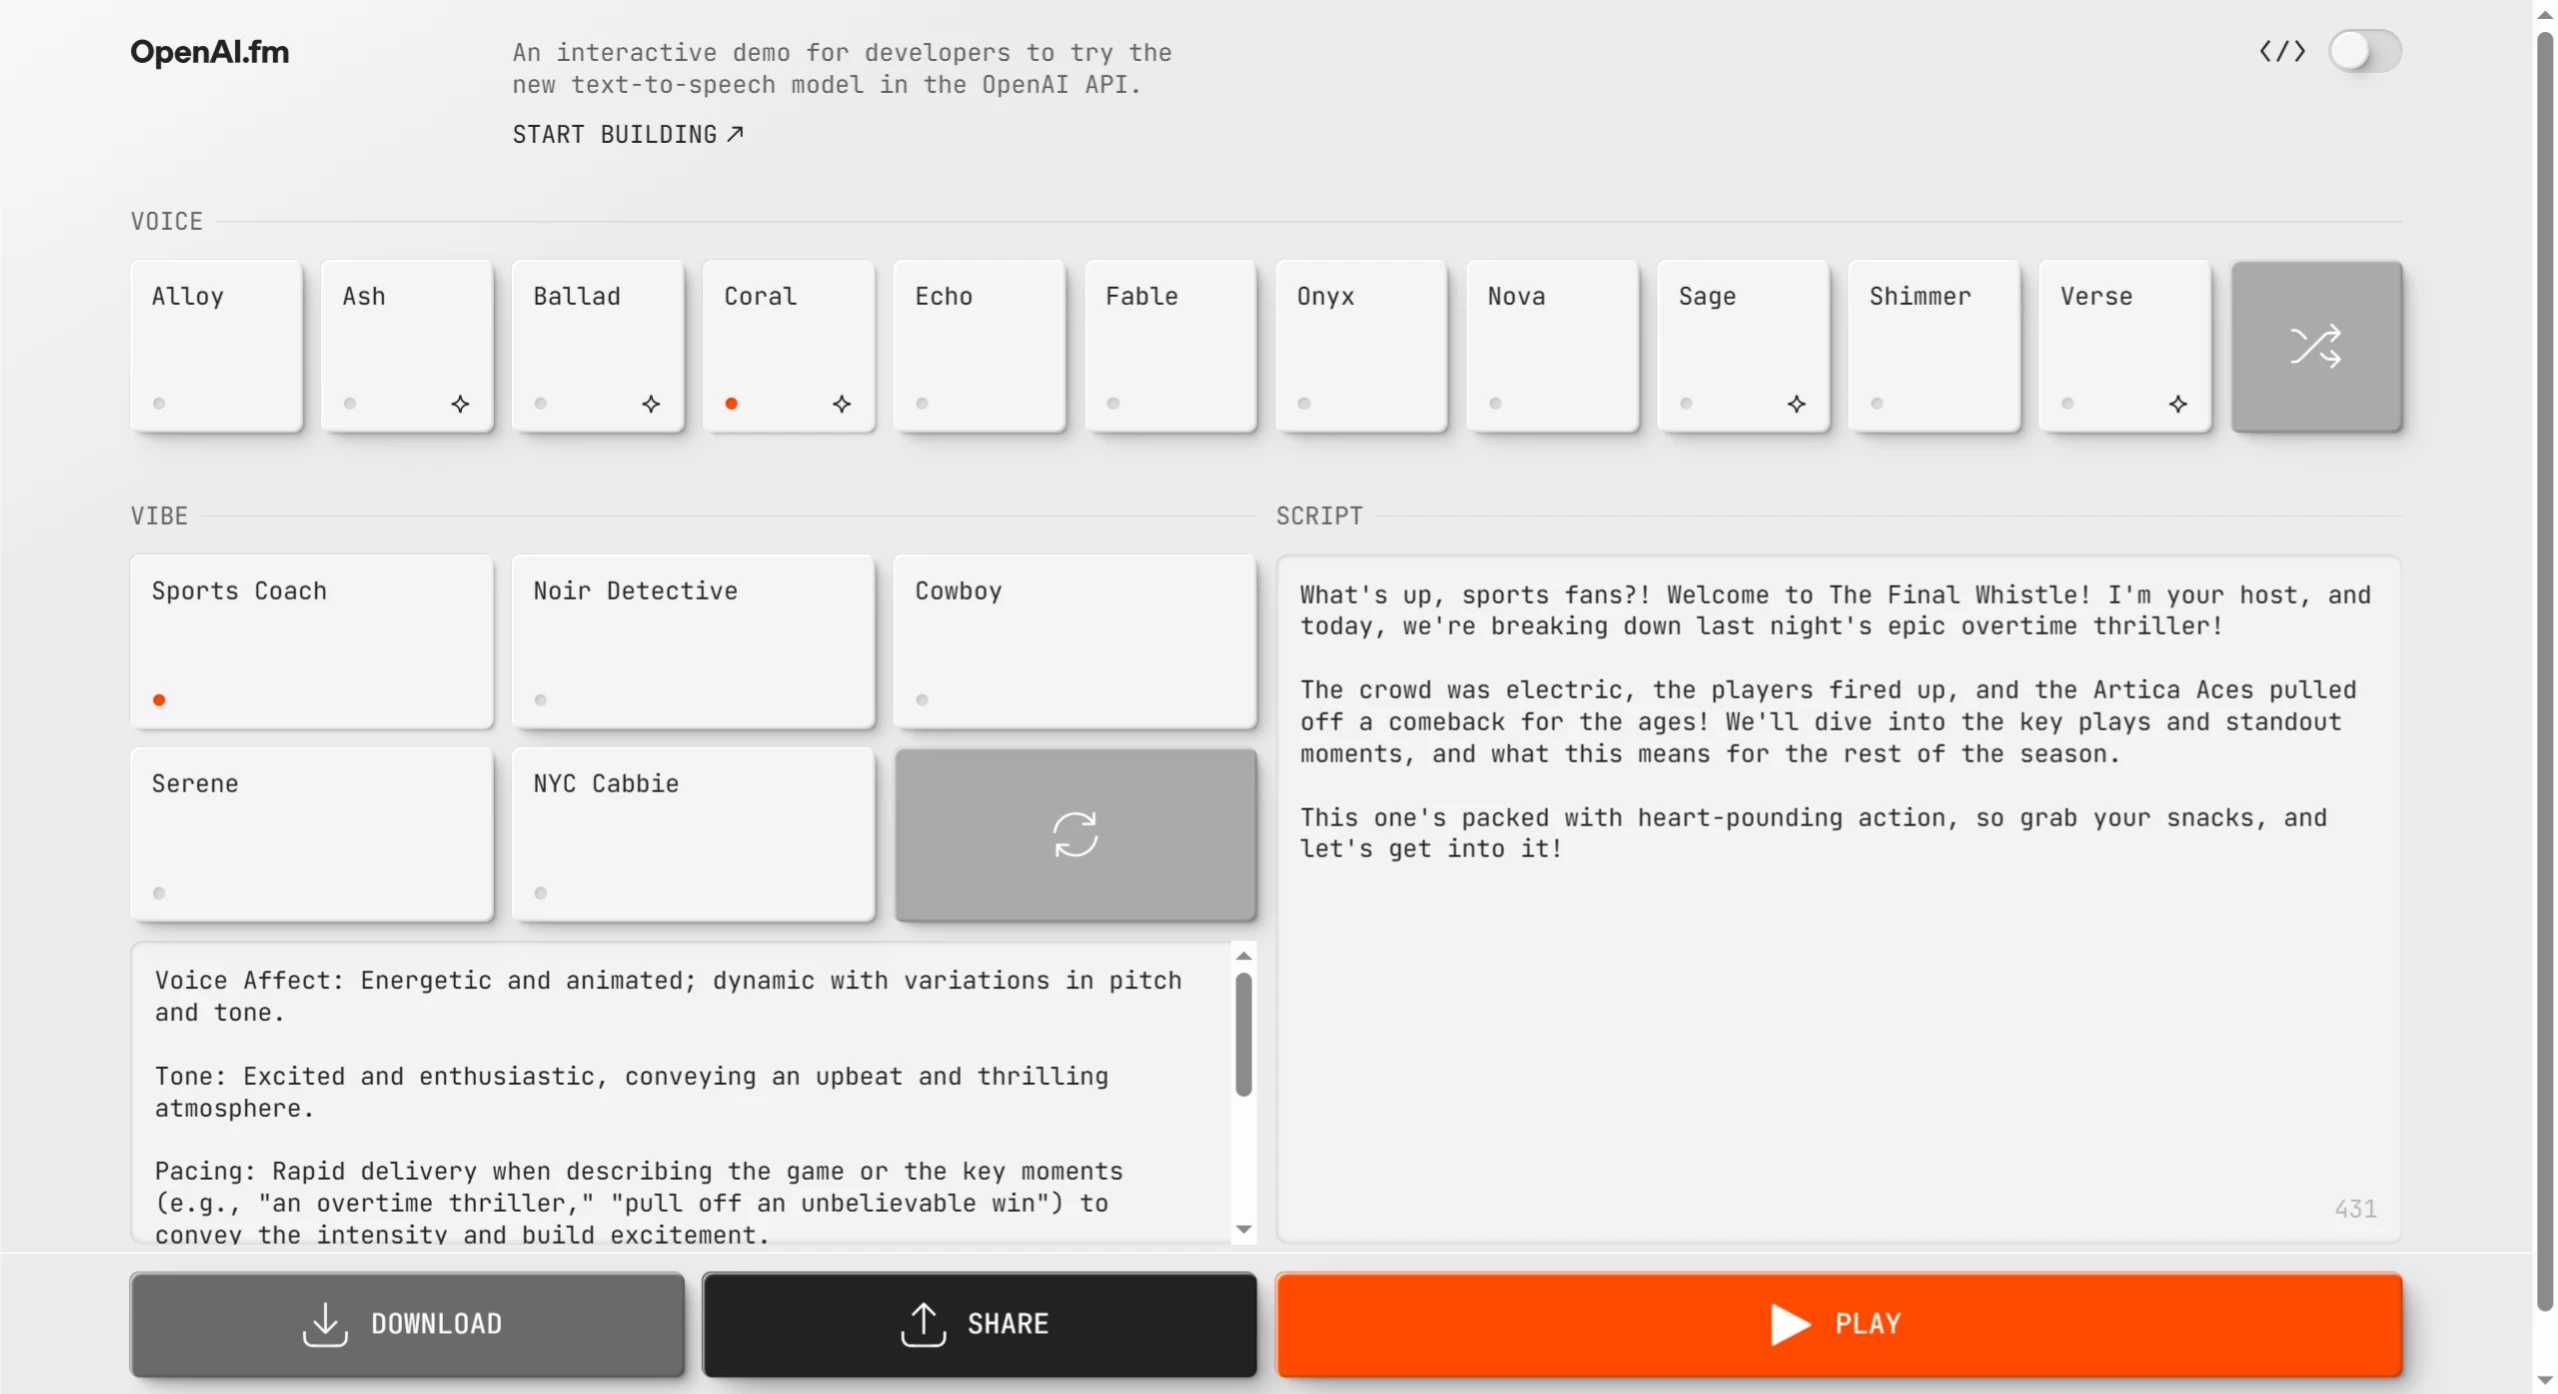
OpenAI's voice model website is OpenAI.fm, which offers a wealth of preset templates, including settings for character, tone, accent, pronunciation, and more. Users can experience and produce related audio for GPT-4o-mini-tts here. In addition, OpenAI has also provided an upgraded Agent SDK to help developers build voice agents more conveniently.
Official Website: http://openai.fm/
Official Blog: https://openai.com/index/introducing-our-next-generation-audio-models/









