
 Script Planner Assistant▸
 AI Apps
 AI News
SpeakerKit: Quickly and Accurately Identify Different Speakers in Audio
小编 ·

SpeakerKit: Quickly and Accurately Identify Different Speakers in Audio
What is SpeakerKit?
SpeakerKit is an on-device speaker diarization tool developed by Argmax that can quickly and efficiently identify different speakers in audio. It works in conjunction with WhisperKit (an audio transcription tool) to generate transcripts with speaker labels. It is suitable for application scenarios that require fast and accurate identification of speakers in audio.
Key Features of SpeakerKit
Speed:
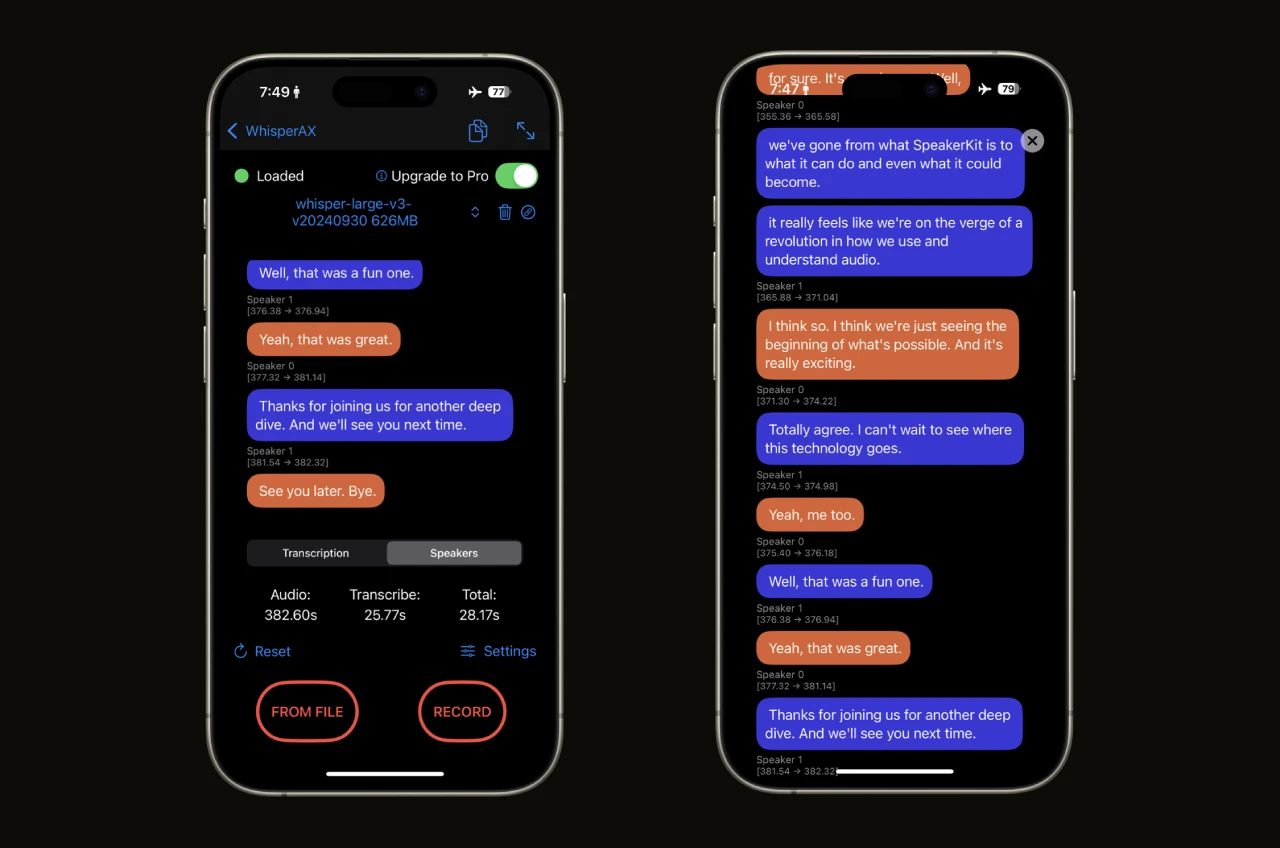
When processing 4 minutes of audio on an iPhone, SpeakerKit completes speaker diarization in approximately 1 second, significantly faster than other comparable systems.
When combined with WhisperKit, the total time for transcription and diarization is only 25 seconds.
Quality:
SpeakerKit's error rate is comparable to industry-leading systems (such as Pyannote), despite being several times faster.
Size:
The total size is approximately 10MB, making it easy to integrate into applications or quickly download.
Compatibility:
Supports devices running iOS 16 and macOS 13 or later.
Android support is under development.
Modularity:
SpeakerKit can work together with WhisperKit to generate transcripts with speaker labels, and it can also be integrated with other transcription engines, offering greater flexibility than server-side APIs.
Benchmarks
Argmax developed a Python toolkit called SDBench to standardize the testing of speaker diarization system performance across 13 widely used datasets. The SDBench code will be open-sourced, and the related paper will be released in April 2025.
Future Plans
Optimizing Transcription Quality:Currently, SpeakerKit's standalone speaker diarization quality has reached industry-leading levels (as measured by DER). The next step is for the team to optimize its combined use with WhisperKit to improve the quality of transcripts with speaker labels (as measured by WDER).
Speaker Recognition Feature:SpeakerKit will introduce a new feature that can extract speaker voiceprints and recognize them in new contexts.
Further Reading:https://www.argmaxinc.com/blog/speakerkit
HuggingFace:https://huggingface.co/argmaxinc/speakerkit-pro









