
 Script Planner Assistant▸
 AI Apps
 AI News
HunyuanVideo-I2V: Tencent Hunyuan's Open-Source Image-to-Video Framework
小编 ·

HunyuanVideo-I2V: Tencent Hunyuan's Open-Source Image-to-Video Framework
What is HunyuanVideo-I2V?
HunyuanVideo-I2V is a new image-to-video framework open-sourced by the Tencent Hunyuan team on March 6, 2025. Built upon the previously open-sourced HunyuanVideo, it further extends the capability of image-to-video generation, allowing video creators to generate high-quality short videos from a single image and supporting customized effect training.
HunyuanVideo-I2V Features
Image-to-video: HunyuanVideo-I2V can use a static image as the first frame of a video and generate matching video content based on user-input captions or descriptions.
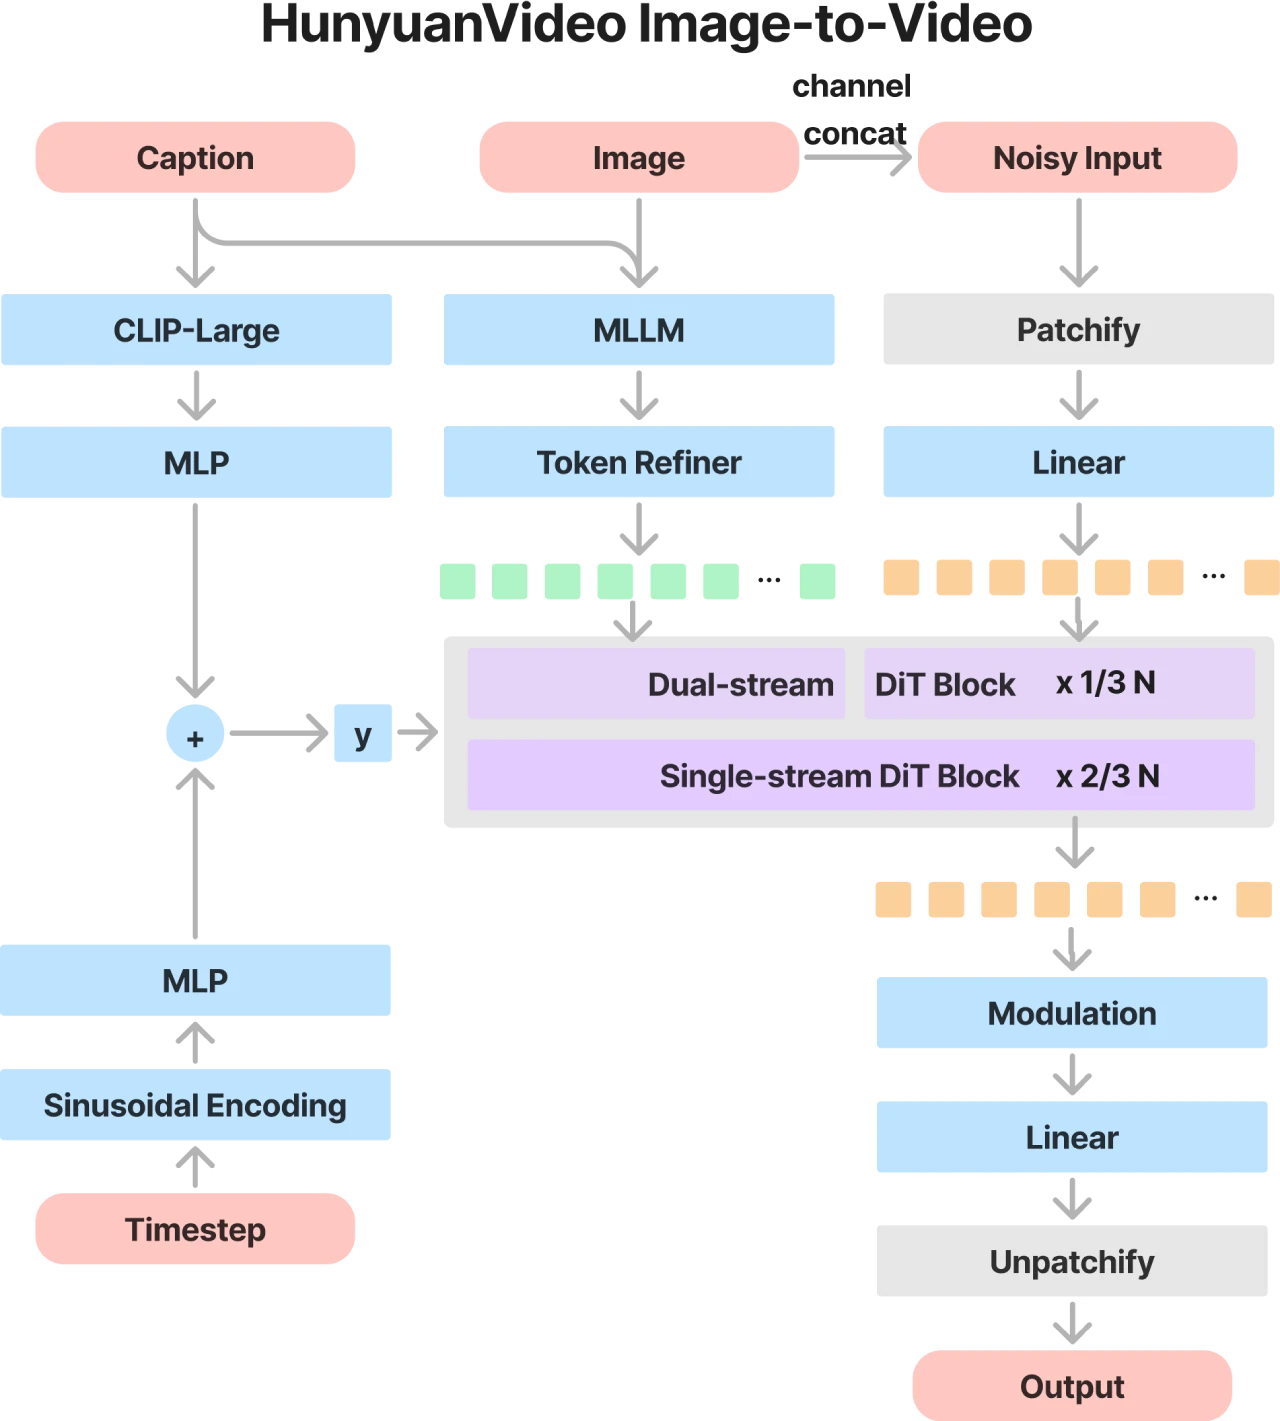
Multimodal Large Language Model (MLLM): The model employs a pre-trained multimodal large language model as the text encoder, significantly enhancing the understanding of the semantic content of input images.
3D Variational Autoencoder (3D VAE): A 3D VAE trained with CausalConv3D technology compresses videos and images from pixel space into a compact latent space, reducing the number of tokens in subsequent models.
Dual-stream to Single-stream Hybrid Model Design: In the dual-stream stage, video and text tokens are processed independently through multiple Transformer blocks; in the single-stream stage, video and text tokens are concatenated for multimodal information fusion.
Progressive Training Strategy: Gradually transition from low-resolution, short videos to high-resolution, long videos to improve model convergence speed.
Prompt Rewriting Model: Addresses the issue of variable language styles and lengths in user prompts, converting user-input prompts into a format that is easier for the model to understand.
Customizable LoRA Training: Supports training video generation models with specific effects using a small amount of data, such as "hair growth" or "character movements" effects.
Efficient Inference: Provides single-GPU inference and multi-GPU sequence parallel inference, supporting faster inference speeds.
HunyuanVideo-I2V Technical Architecture
HunyuanVideo-I2V continues the design philosophy of HunyuanVideo in its overall architecture and optimizes it for image-to-video generation tasks. Its core lies in using image latent space concatenation technology to inject key information from reference images into the video generation process, while achieving cross-modal deep fusion of text and image information through MLLM.
How to Use HunyuanVideo-I2V
1. Installation and Dependencies
Install PyTorch and other dependencies; specific installation guides can be found on the GitHub page.
An NVIDIA GPU is recommended, with at least 80GB of VRAM required.
2. Download Pretrained Models
Pretrained model weights can be downloaded from the GitHub page or Hugging Face page.
3. Inference Code
Use the provided inference code (such as sample_video.py) to generate videos.
4. LoRA Training
LoRA training code is provided, allowing users to train video generation models with specific effects using a small amount of data.
HunyuanVideo-I2V Application Scenarios
Video Content Creation: Provides video creators with efficient, high-quality video generation tools.
Film and Video Production: Generate cinematic-grade video content.
Personalized Videos: Generate personalized videos based on user-uploaded images and descriptions.
Official Website:https://video.hunyuan.tencent.com/
GitHub:https://github.com/Tencent/HunyuanVideo-I2V
Hugging Face: https://huggingface.co/tencent/HunyuanVideo-I2V









