
 Script Planner Assistant▸
 AI Apps
 AI News
WhisperChain: A Real-Time Voice Transcription Tool That Polishes Spoken Language into Formal Text
小编 ·

WhisperChain: A Real-Time Voice Transcription Tool That Polishes Spoken Language into Formal Text
What is WhisperChain?
WhisperChain is a real-time speech transcription tool with built-in polishing features, particularly well-suited for meeting notes, voice memos, and similar scenarios. It automatically cleans up filler words and transforms colloquial expressions into more formal, concise language while preserving the core meaning.
For example, if you say "This thing sold really well, made a lot of money, customers all loved it…", it will transcribe it as "The product has performed exceptionally well in the market, generating considerable revenue and receiving widespread praise from customers."
The processed content is saved directly to the clipboard, ready to use at any time — very convenient.
WhisperChain Features
Real-time speech recognition: WhisperChain uses Whisper.cpp to achieve real-time speech recognition, capable of instantly converting spoken content into text.
Transcription cleanup: Cleans up transcribed text using LangChain, improving readability and accuracy.
Global hotkey support: Users can use a global hotkey (default is
Automatic clipboard integration: Transcription results are automatically saved to the clipboard, allowing users to paste and use them anytime, anywhere.
WhisperChain Project Architecture
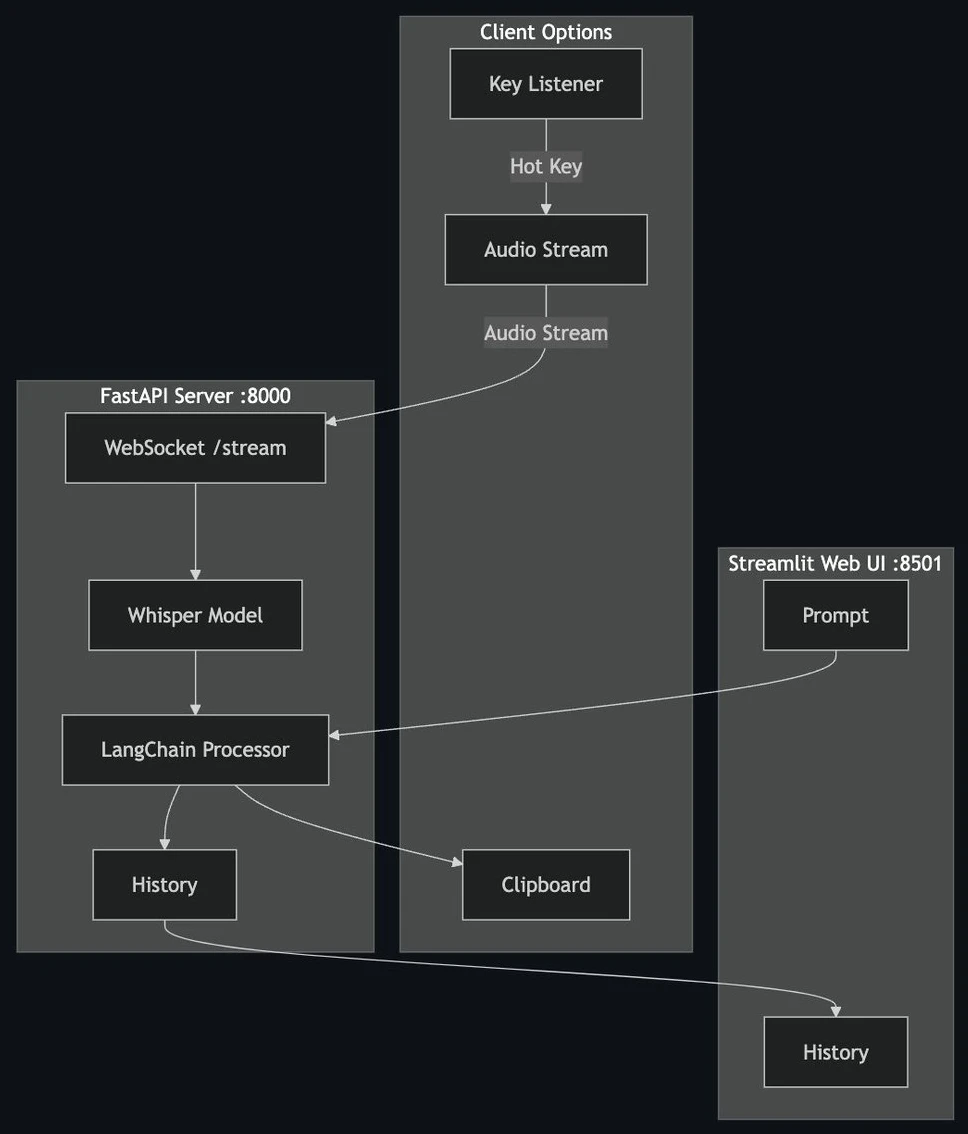
WhisperChain's architecture includes client-side options (such as hotkey listening, audio streaming, and clipboard integration), a Web UI (Streamlit), and backend services (FastAPI). Audio streams are transmitted to the backend via WebSocket, processed through the Whisper model for recognition and LangChain for cleanup, and finally output as polished text.
WhisperChain Use Cases
Meetings and lectures: During meetings or lectures, convert spoken content into text in real time for easy note-taking.
Voice assistants: Enable voice assistants to understand commands more accurately, improving the user experience.
Medical records: Doctors and nurses can use voice input to record patient information, saving time and improving efficiency.
Customer support: Convert customer voice inquiries into text, enabling customer service agents to respond quickly and provide more precise service.
Installation and Configuration
System requirements: Python 3.8+ and an OpenAI API key are required. For macOS, ffmpeg and portaudio also need to be installed.
Installation method: Install WhisperChain via pip:
pip install whisperchain
Configuration: On first run, the system will prompt for an OpenAI API key and save it in the ~/.whisperchain/.env file.
How to Use
Launch the application:
whisperchain
Or launch with a custom configuration file:
whisperchain --config config.json
Use the global hotkey to start recording, release the hotkey after speaking, and the transcription result will be automatically copied to the clipboard.
GitHub repository:https://github.com/chrischoy/WhisperChain









