
 Script Planner Assistant▸
 AI Apps
 AI News
CSM: Sesame's Speech Synthesis Model That Feels Like Talking to a Real Person
小编 ·

CSM: Sesame's Speech Synthesis Model That Feels Like Talking to a Real Person
What is CSM?
CSM (Conversational Speech Model) is a conversational speech synthesis model developed by Sesame. It is based on the Transformer architecture and adopts an end-to-end multimodal learning approach, capable of combining context and emotional background to synthesize extremely realistic human-like speech, delivering outstanding performance in the field of speech synthesis.
Features of CSM
Natural Speech Performance: Mimics the intonation, rhythm, and timbre of real human voices, solving the monotonous intonation problem of traditional speech synthesis systems and making synthesized speech sound like a real person speaking.
Nuanced Emotional Expression: Can incorporate natural elements such as emotion, pauses, and emphasis, conveying a variety of emotions including anger, sadness, and excitement, making conversations more engaging.
Low-Latency Response: Through optimized computation methods, ensures smooth conversation flow with extremely short ai response times, close to real-time human reactions.
Multimodal Interaction: Can simultaneously input text and voice history, with context-awareness capabilities, understanding dialogue context and emotion, making speech more natural and interactive.
Personality Consistency: Maintains stable voice characteristics, avoiding inconsistencies in different scenarios and eliminating the robotic intonation found in traditional TTS systems.
Dynamic Dialogue Modeling: Simulates natural pauses, speech rate, and emphasis in human conversation, enhancing the realism and interactivity of voice interaction.
Technical Highlights of CSM
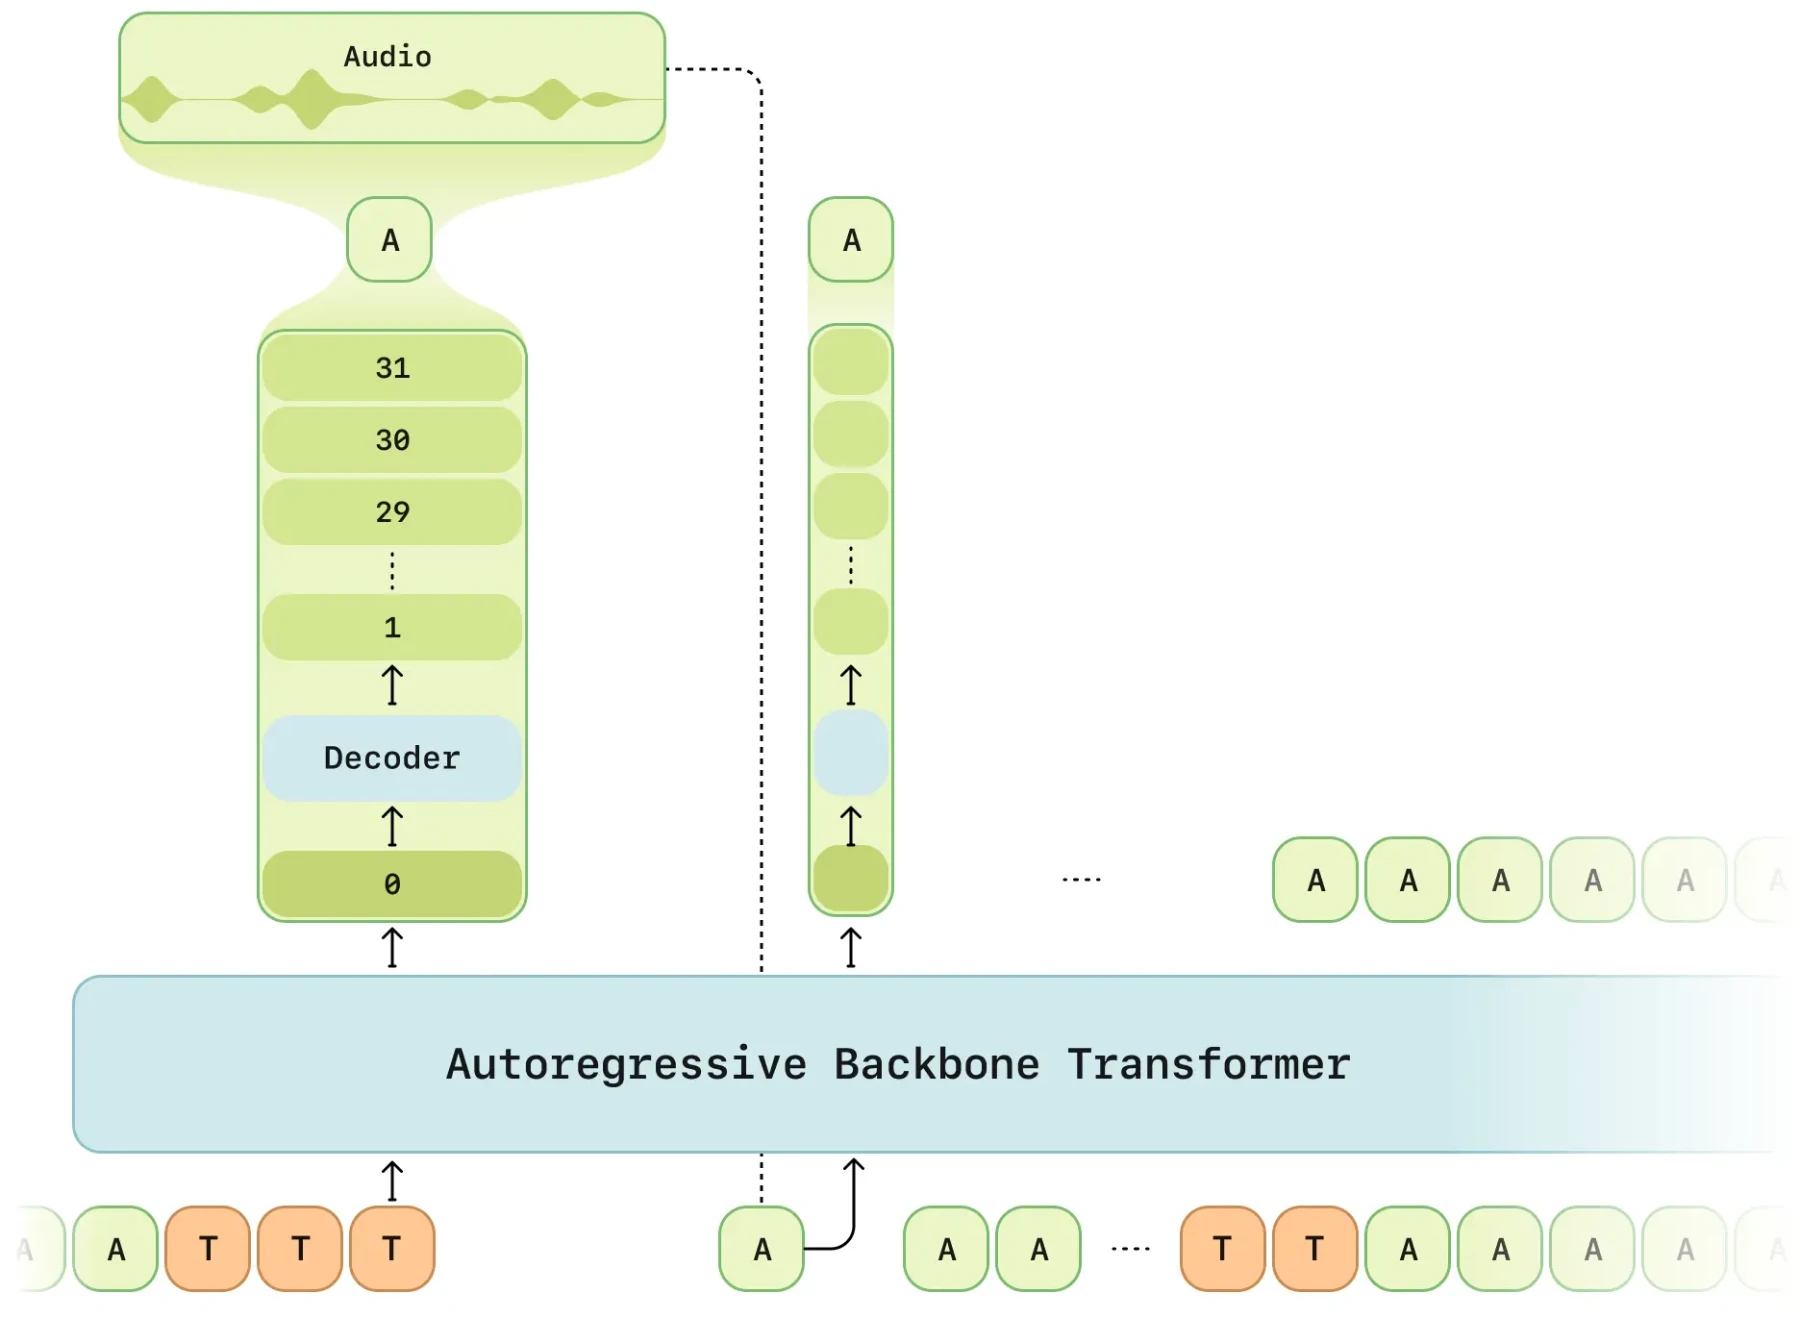
End-to-End Multimodal Transformer Architecture: Generates high-quality speech directly from text without intermediate processing steps. With Transformer at its core, AI voice possesses context-awareness capabilities. Text is processed with the LLaMA Tokenizer, voice is encoded with the Mimi Tokenizer, and RVQ quantization technology is adopted.
Audio Encoding Based on Residual Vector Quantization (RVQ): Uses two types of audio tokens—semantic tokens and acoustic tokens. Semantic tokens represent speech semantics and pronunciation features, while acoustic tokens represent details such as pitch, timbre, and prosody. Through hierarchical RVQ training, different layers predict core and detail features, avoiding information loss and improving speech naturalness.
Computation Optimization and Low-Latency Inference
Latency Mode Optimization: Compute lower-level RVQ layers first, then sequentially compute higher-level detail features, speeding up inference.
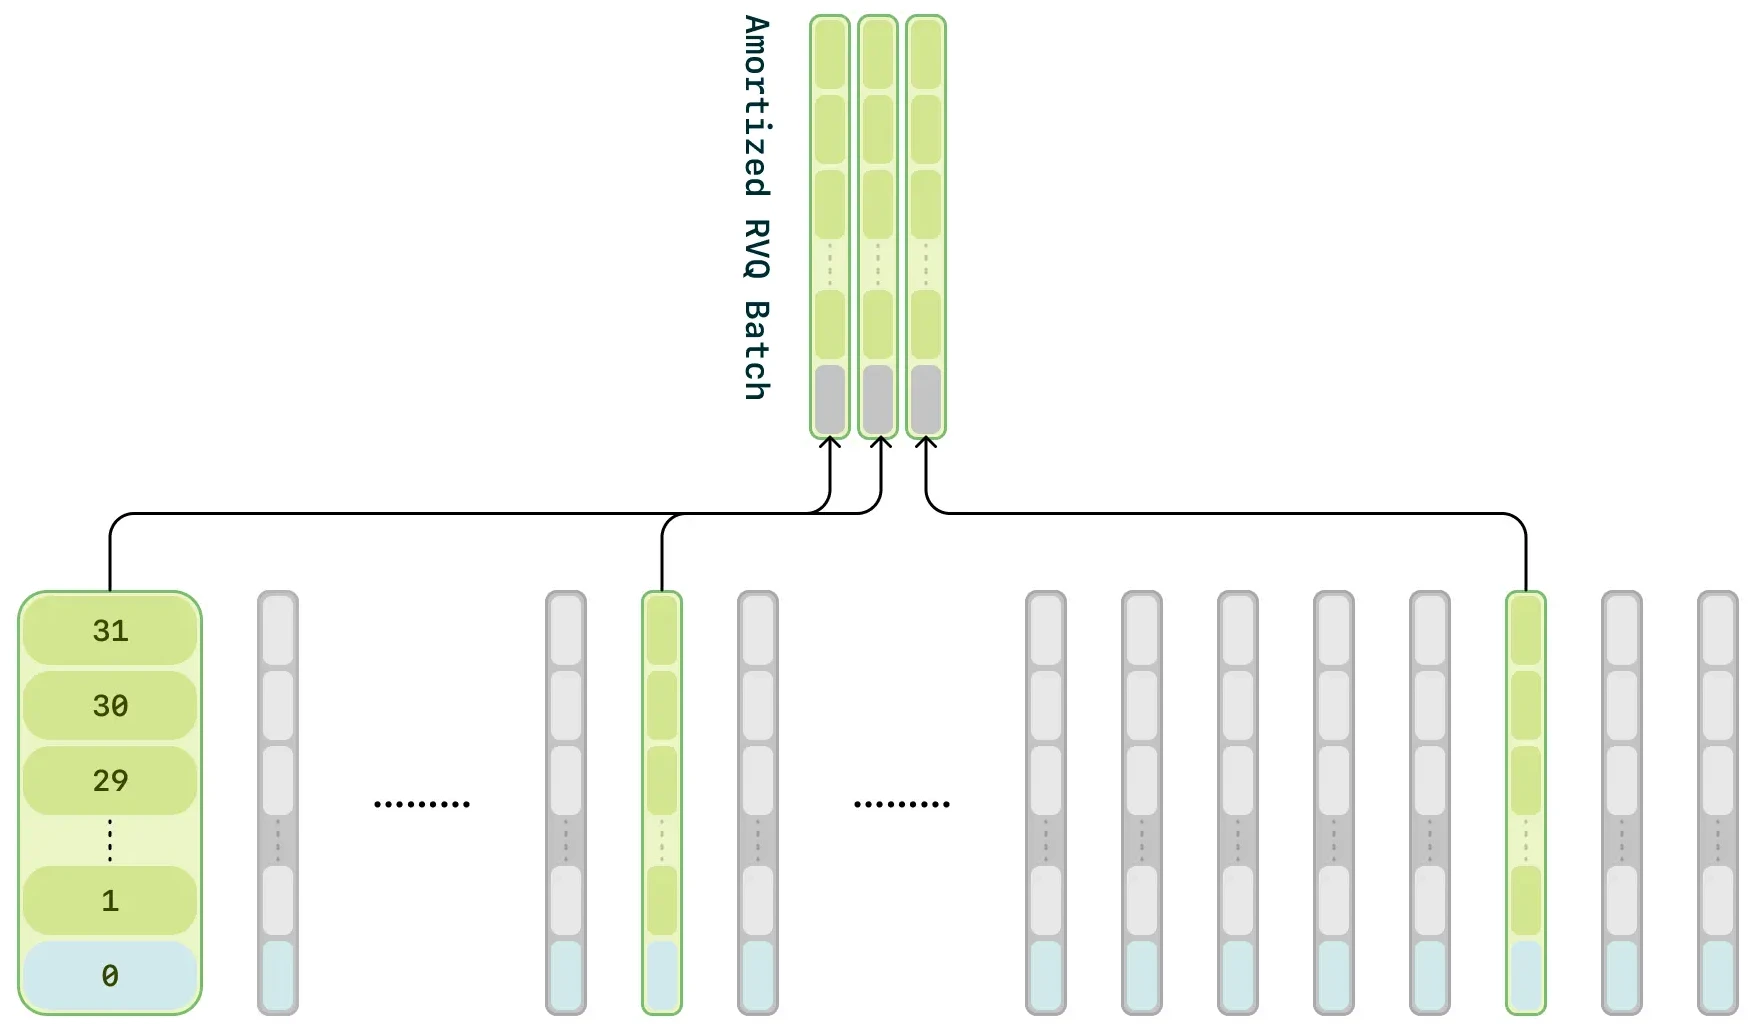
Computation Amortization: During training, randomly sample 1/16 of audio frames for optimization, reducing computational requirements without affecting audio quality.
Two-Stage Transformer Structure: The backbone Transformer processes text and audio information and predicts the base structure; a lightweight decoder refines the audio, reducing computation and improving inference speed.
Wide Applications of CSM
Intelligent Assistants: Makes voice interaction with smart speakers and virtual assistants more natural and friendly, like communicating with a real person.
Customer Service: Applied in customer service systems, allowing users to enjoy smoother interaction experiences and improving satisfaction.
Education and Training: Creates realistic dialogue environments in language learning applications, helping learners understand and practice language knowledge.
Entertainment Industry: Gives vivid and realistic voices to characters in games, animations, and other industries, making stories more engaging.
Virtual Assistant Creation: Creates virtual assistants with more natural voices, providing attentive service.
Translation Tools Optimization: Generates natural and fluent dialogue in real-time voice translation, improving the translation experience.
Education Platform Interaction: Plays a role in interactive voice dialogues on education platforms, enhancing learning fun and effectiveness.
How to Use CSM
Online Experience
You can visit Sesame's official website (sesame.com/voicedemo) to experience the effects of the speech synthesis technology.
Integration into Products
Developers can integrate Sesame's voice model into products or services such as voice assistants and intelligent customer service systems to enhance voice interaction capabilities.
Research and Development
Sesame plans to scale up the model and increase the amount of datasets. Researchers can follow official introductions and demos (https://www.sesame.com/research/crossing_the_uncanny_valley_of_voice ) to learn about the latest results and technological progress.
To experience it online, visit:https://www.sesame.com/research/crossing_the_uncanny_valley_of_voice#demo









