
 Script Planner Assistant▸
 AI Apps
 AI News
Migician: A Multimodal Model from Tsinghua University & Collaborators for Multi-Image Object Grounding in Complex Scenes
小编 ·

Migician: A Multimodal Model from Tsinghua University & Collaborators for Multi-Image Object Grounding in Complex Scenes
What is Migician?
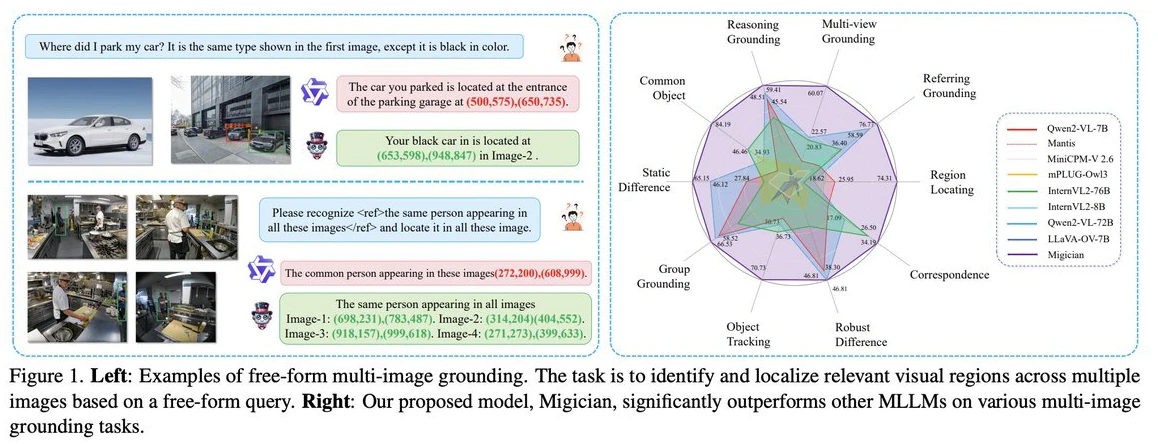
Migician is a multimodal large language model jointly developed by Tsinghua University, Beijing Jiaotong University, and Huazhong University of Science and Technology, capable of free-form and precise localization in multi-image scenarios. It supports rapid localization of target regions across multiple images through text descriptions, images, or a combination of both, enhancing localization capabilities in multi-image scenarios.
Main Features of Migician
Cross-image localization: Migician supports multiple cross-image localization methods, including "image-to-image search" and combined "text + image" queries. For example, in security surveillance, by inputting a text description such as "a man wearing a black top, blue jeans, and a white baseball cap," the model can quickly locate the person matching the description across numerous surveillance frames.
Multimodal fusion: Through an advanced neural network architecture, Migician effectively integrates visual and linguistic information, deeply mining semantic associations across images. For example, when handling the task of "finding frames with red cars in a set of city street scene images," the model extracts visual features such as color and shape from the images while parsing the semantic information of "red car" from the text, then fuses the two to localize the target more accurately.
CoT (Chain-of-Thought) reasoning optimization: Migician introduces CoT reasoning optimization, decomposing complex problems into multiple simpler sub-problems and progressively deriving the final answer. For example, when localizing an item within a specific room, the model first determines the likely area where the room is located based on the text description, then precisely localizes the item within the images of that area.
End-to-end framework: Migician adopts an end-to-end framework that directly processes multi-image input, avoiding the issues of error accumulation and low efficiency found in traditional step-by-step reasoning methods.
Model Performance
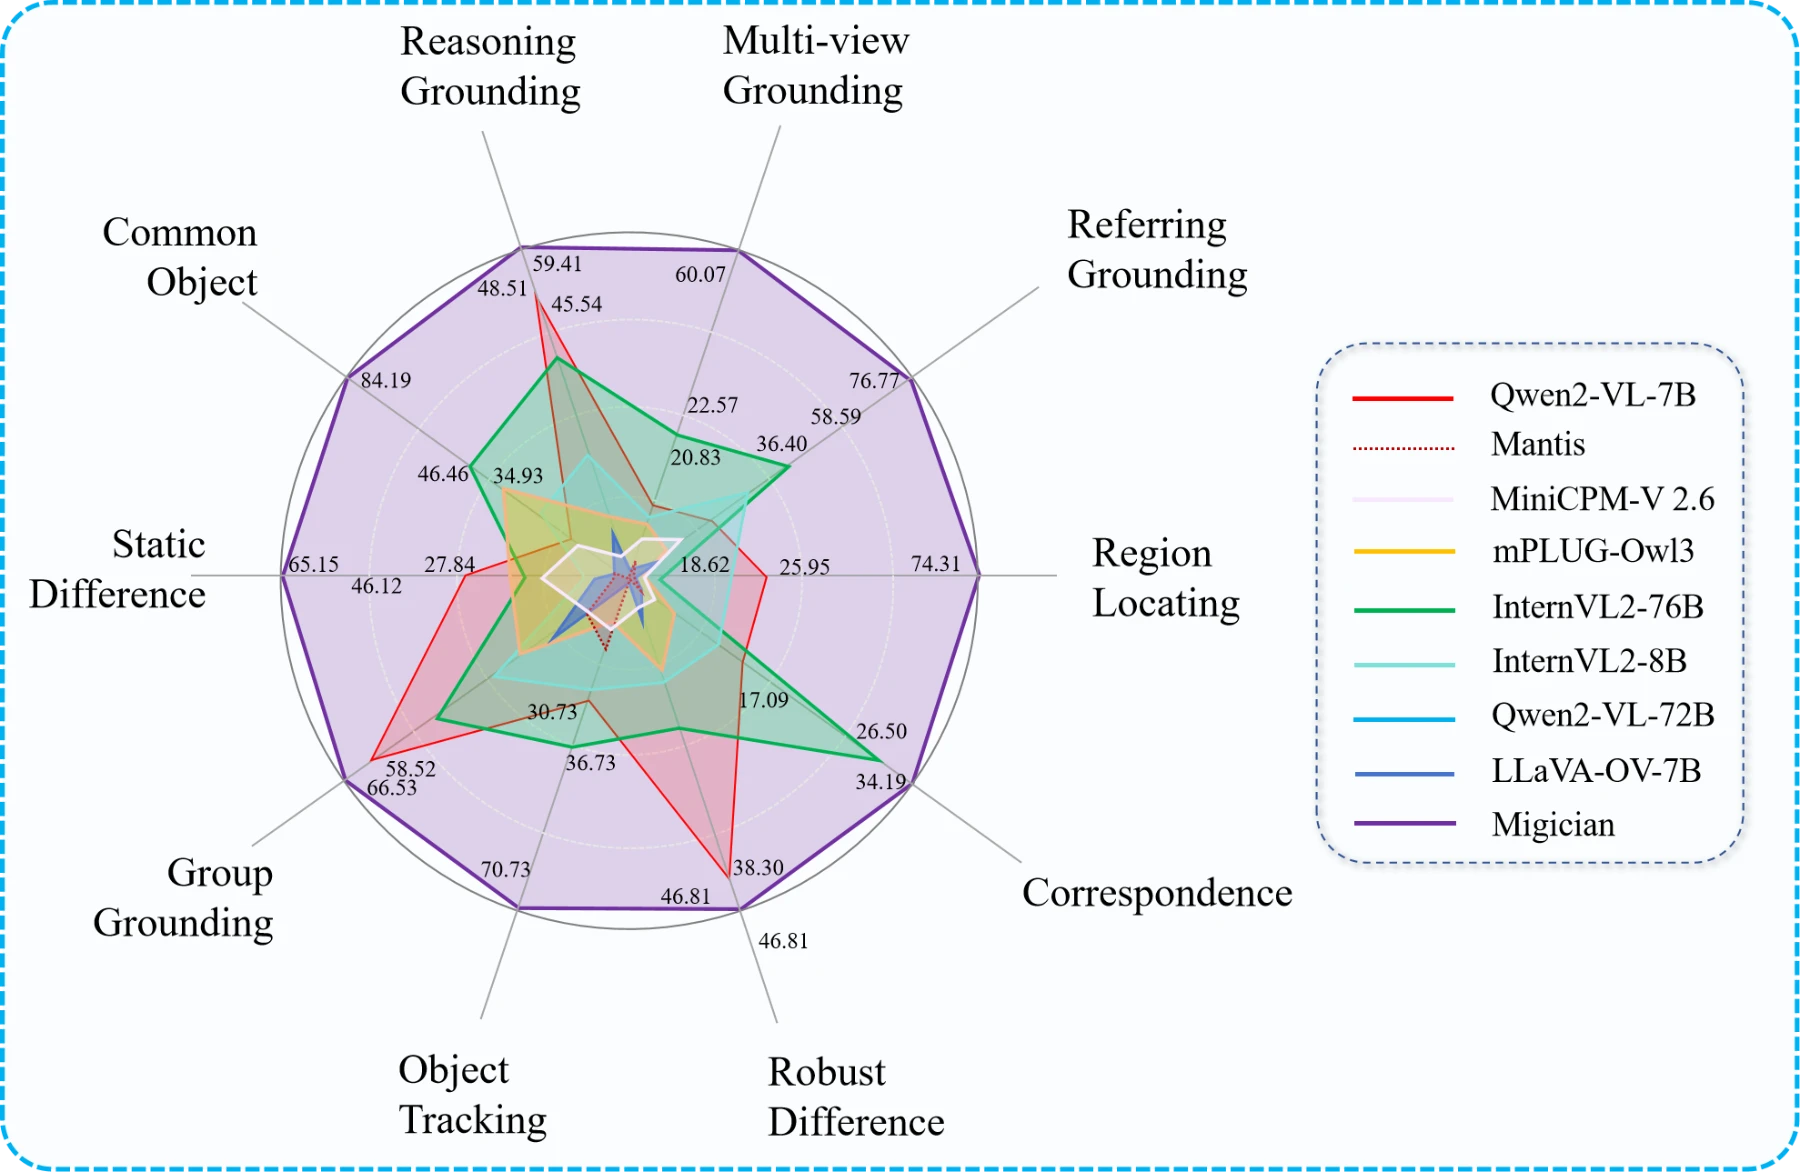
Performance: Migician performs outstandingly on multi-image localization tasks, significantly outperforming existing MLLMs and even surpassing larger 70B models on several tasks. Specifically, Migician's performance on MIG-Bench is 21.61% higher than that of the best existing MLLM.
Evaluation metrics: MIG-Bench provides evaluation metrics such as [email protected], [email protected], [email protected], and average IOU. Users can perform a one-click evaluation by running the MIG_bench_eval.py script.
Migician Application Scenarios
Security surveillance: Real-time analysis of footage from multiple surveillance cameras to quickly locate suspicious individuals, vehicles, or anomalous events.
Autonomous driving: Fusion of image information acquired from multiple vehicle sensors, combined with text descriptions of roads, obstacles, and traffic signs, helping vehicles perceive their surroundings more accurately.
Medical imaging: Rapid localization of lesion areas across multiple medical images to assist in disease diagnosis.
Robot embodied intelligence: Helps robots quickly locate target objects in complex environments to complete tasks such as grasping and transporting.
Migician Project Resources
GitHub Repository:https://github.com/thunlp/Migician
Paper Address:https://arxiv.org/pdf/2501.05767
Migician is a powerful tool specifically designed for multi-image localization tasks. With the help of the large-scale dataset MGrounding-630k and the comprehensive test benchmark MIG-Bench, its localization capabilities in multi-image scenarios have been significantly enhanced.









