
 Script Planner Assistant▸
 AI Apps
 AI News
NSA: DeepSeek's Technique to Accelerate Ultra-Long Context Training and Inference
小编 ·

NSA: DeepSeek's Technique to Accelerate Ultra-Long Context Training and Inference
DeepSeek team introduced an innovative attention mechanism called NSA (Native Sparse Attention) on February 18, 2025. NSA is dedicated to addressing the computational efficiency and performance bottlenecks encountered in long-context processing. Through a hardware-aligned approach with native training support, this technology can substantially boost inference speed and reduce pre-training costs.
Key Features of NSA:
Hardware-friendly: Designed with compatibility across various hardware architectures in mind, aiming to improve training efficiency.
Native Training Capability: Supports direct training on data, enhancing the model's adaptability and flexibility.
Efficient Inference and Training: Accelerates long-context processing, facilitates complex model applications, and effectively handles longer sequence data such as text and video.
Dynamic Hierarchical Sparsity Strategy: Leverages fine-grained token selection and coarse-grained token compression techniques to preserve information while reducing computational complexity.
Cost Reduction: Through optimized design, significantly reduces resource consumption when training deep learning models, including time and computational costs, which is highly valuable for researchers and developers.
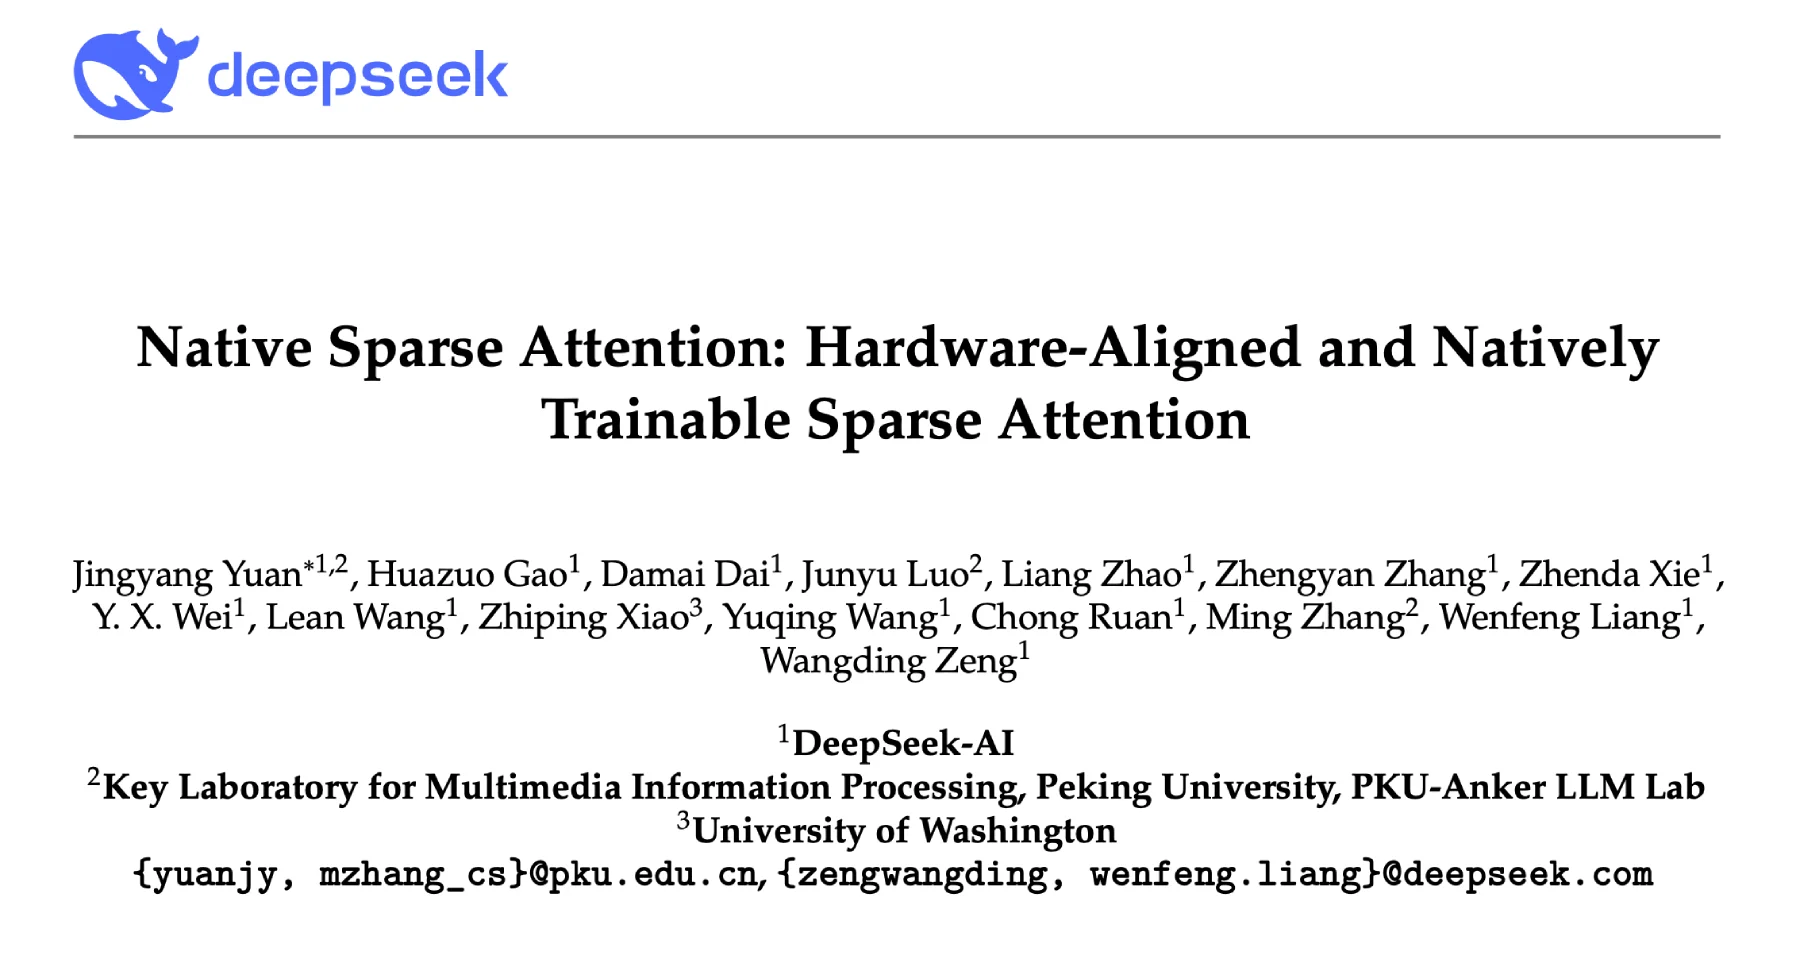
Core Components of NSA:
Dynamic Hierarchical Sparsity Strategy: Combines coarse-grained Token compression and fine-grained Token selection to improve efficiency while ensuring the model's awareness of global context and local details.
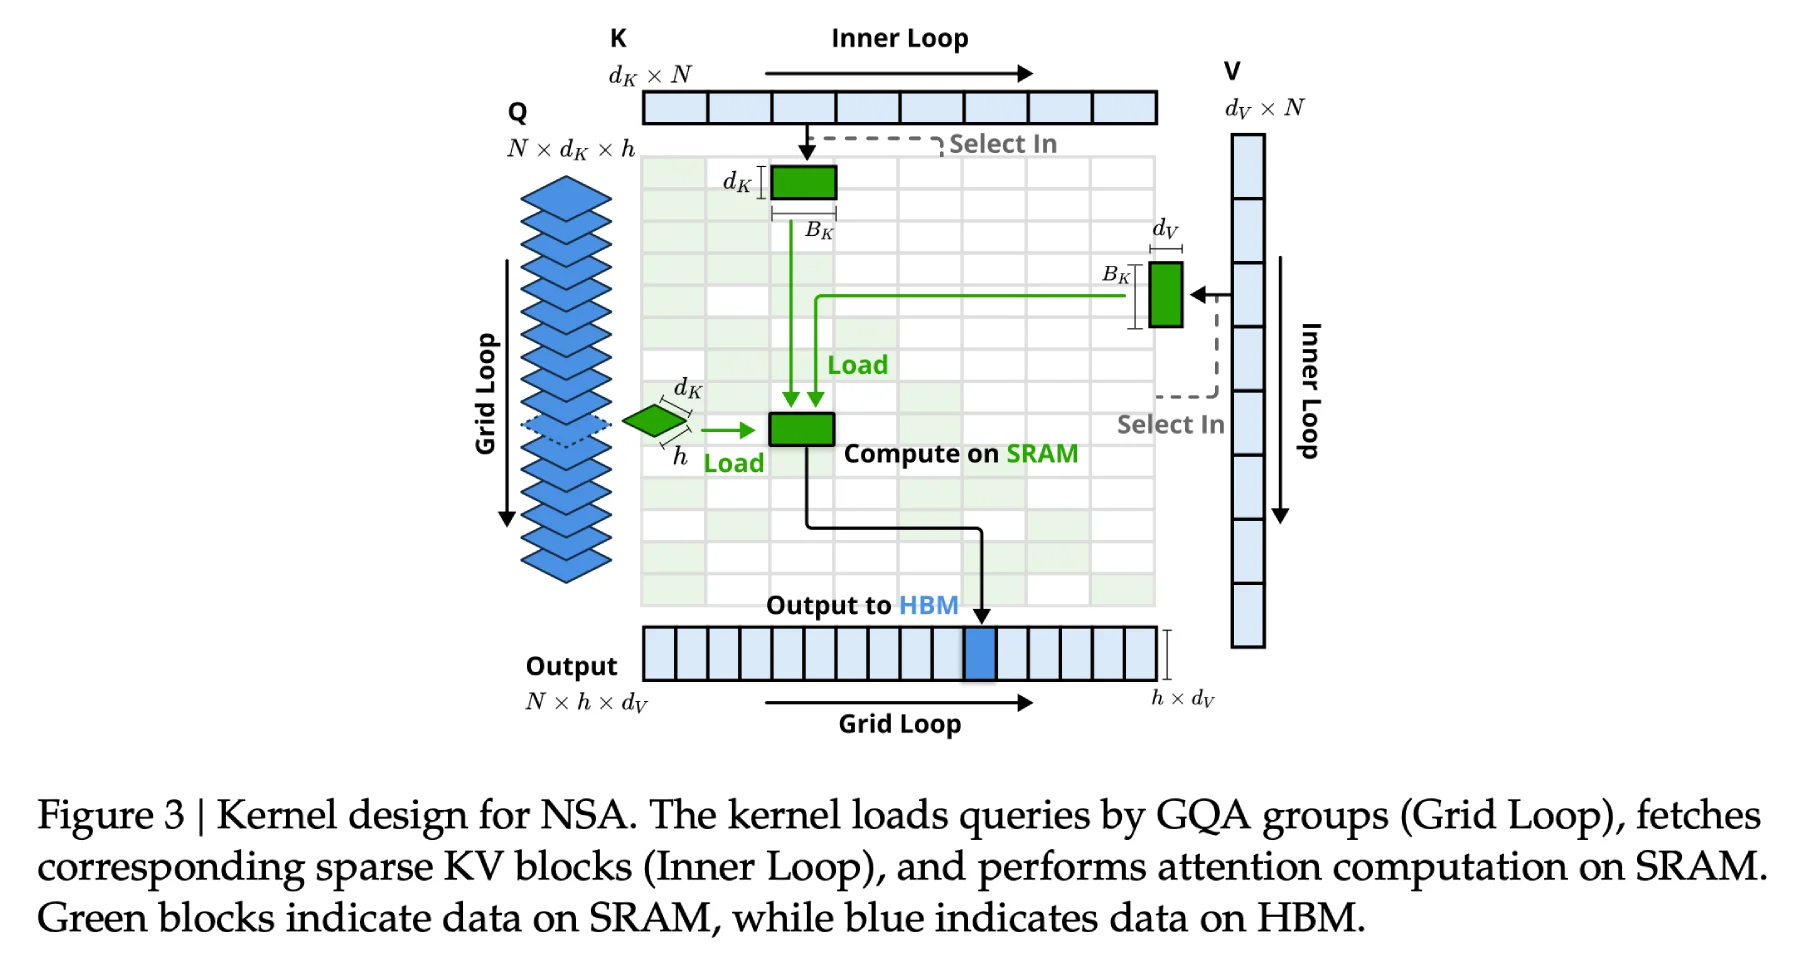
Hardware-aligned Design: Optimizes memory access, adapts to GPU tensor cores, loads data in blocks, reduces redundant transfers, and improves parallel efficiency.
End-to-end Trainable: Supports the entire sparse computation workflow from pre-training to inference, maintaining the stability of backpropagation and avoiding the "training lag" issue of traditional sparse methods.
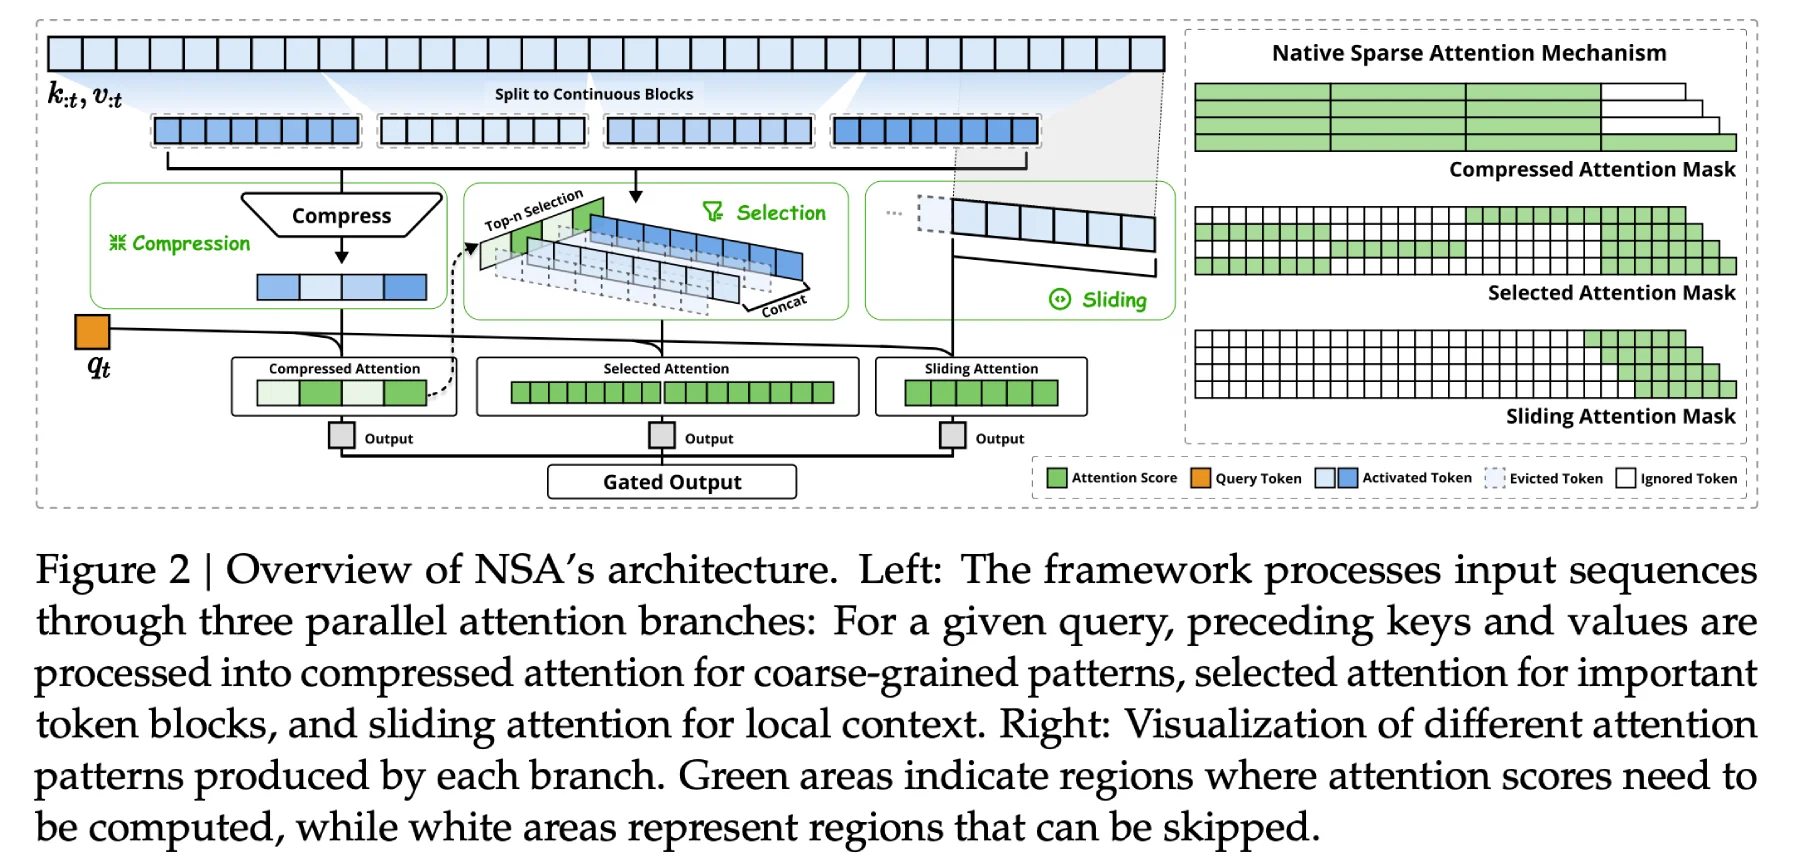
Technical Details of NSA:
Dynamic Hierarchical Sparsity Strategy: Flexibly identifies key information and negligible information, optimizes information processing, ensures the model captures critical global semantics when handling long contexts, while reducing computational burden.
Coarse-grained Token Compression: Reduces the volume of data to be processed and accelerates computation by consolidating similar or unimportant Tokens, while maintaining an understanding of coarse-grained text semantics.
Fine-grained Token Selection: Further screens important Tokens within the compressed data, ensuring the model focuses on details, maintains local precision, and prevents the loss of important information.
Sliding Window: Utilizes a sliding window mechanism to capture local contextual information and avoid overlooking neighboring relationships.
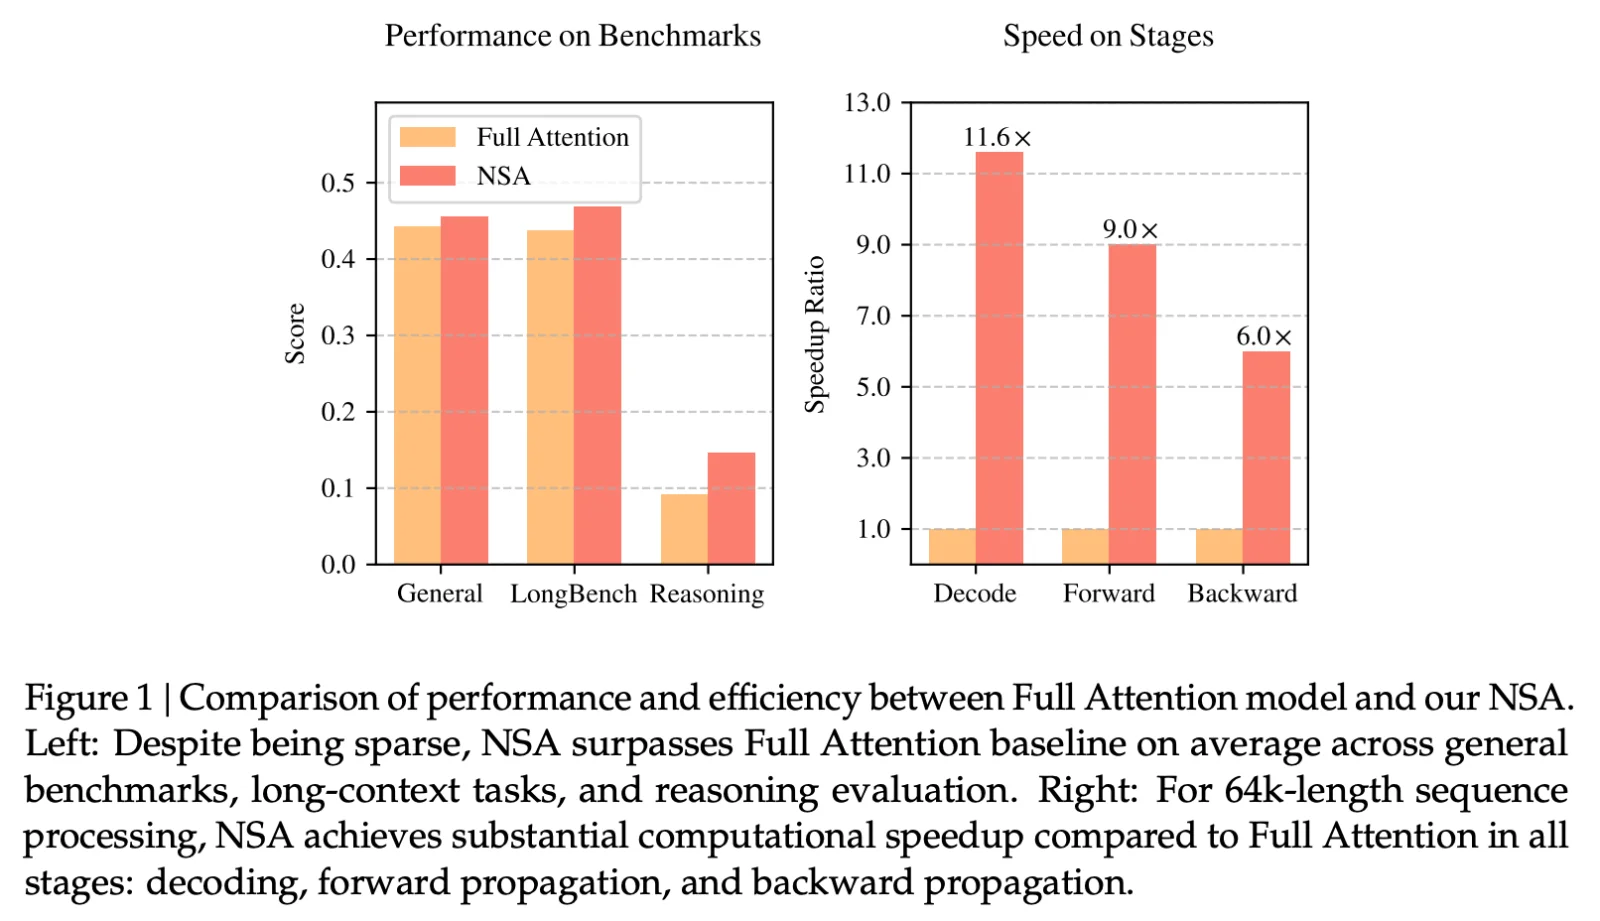
Performance Results of NSA:
Speed Boost: When processing sequences of 64k length, NSA achieves significant speed improvements across decoding, forward propagation, and backpropagation stages, up to 11.6x.
Superior Performance: In multiple benchmarks, NSA performs comparably to or better than full attention models, particularly in long-context tasks and instruction reasoning.
Application Areas of NSA:
Intelligent Assistants: Enables more complex multi-turn dialogues and personalized services.
Scientific Computing: Such as long-sequence data processing in physics simulation and engineering modeling.
Code Generation and Debugging: Understanding large codebases and generating high-quality solutions.
NSA Paper:https://arxiv.org/abs/2502.11089
DeepSeek is a Chinese enterprise focused on general artificial intelligence, dedicated to exploring core AGI technologies and bringing them to productization. DeepSeek has launched multiple high-performance open-source AI large models, such as DeepSeek-V2 which supports long text understanding with a 128k context, and DeepSeek-R1-Lite-Preview which performed excellently on the MT-Bench Chinese evaluation.









