
 Script Planner Assistant▸
 AI Apps
 AI News
OmniHuman: An End-to-End Multimodal Framework for Digital Human Video Generation
小编 ·

OmniHuman: An End-to-End Multimodal Framework for Digital Human Video Generation
OmniHuman is a diffusion Transformer-based multimodaldigital humanvideo generation framework from ByteDance. It requires only a single photo and a segment of audio to generate a video, and the resulting movements, lip sync, and expressions are nearly perfect.
The OmniHuman framework expands data scale by mixing motion-related conditions during the training phase. At its core, this framework can handle multiple input modalities, thereby generating more realistic and natural digital human videos.
Key Features of OmniHuman
Multimodal Input: OmniHuman supports multiple input forms, including text, audio, and video, enabling the generated digital human to display richer emotions and actions across different scenarios. By fusing data from different modalities, it breaks through the bottleneck of scarce high-quality data.
Scaled Data: By introducing motion-related conditions, OmniHuman can effectively scale up the dataset during training, thereby improving the generalization capability and expressiveness of the generation model.
High-Quality Output: Leveraging advanced deep learning techniques, the framework can generate high-quality digital human videos. It supports not only real humans but also 3D characters and anime characters, making it suitable for livestreaming, entertainment, education, and many other fields.
Real-Time Generation: OmniHuman also features real-time generation capabilities, allowing users to receive instant feedback and performance from the digital human in interactive scenarios.
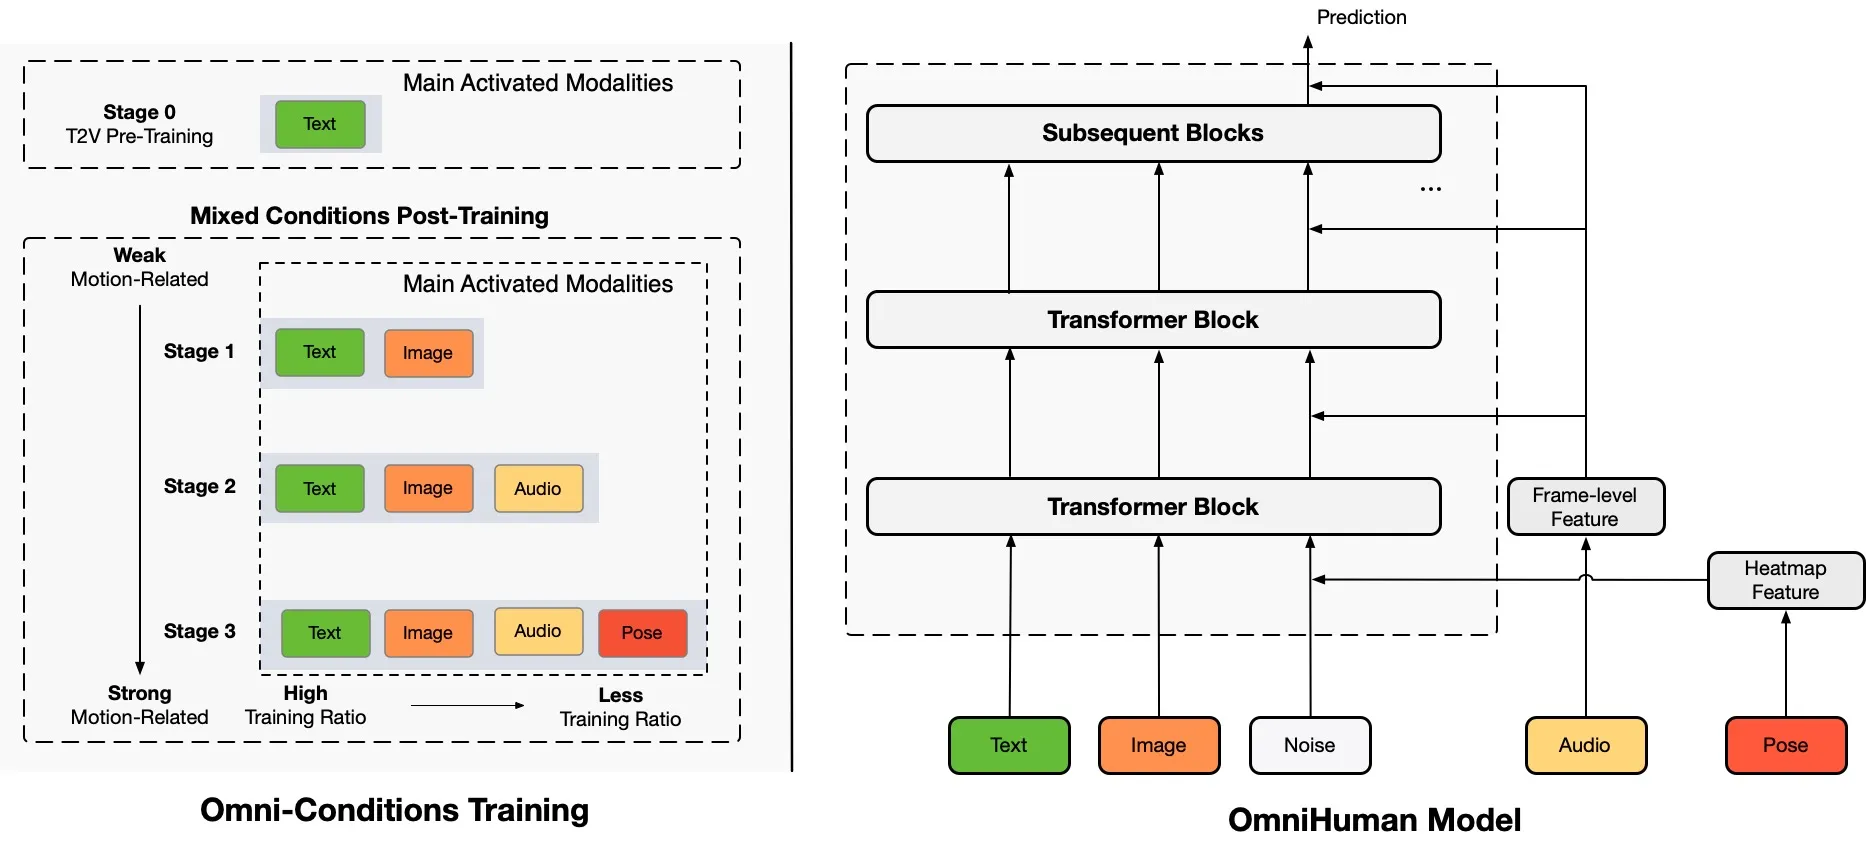
OmniHuman also supports multiple driving modes, including audio-driven, video-driven, and combined driving signals, giving users greater flexibility in terms of input. In addition, OmniHuman is capable of handling human-object interactions and challenging body poses, further enhancing the realism and expressiveness of the generated videos. The design philosophy of the OmniHuman framework is to fully leverage data-driven motion generation, ultimately achieving highly realistic human video generation. Compared with existing end-to-end audio-driven methods, OmniHuman can not only produce more realistic videos but also offer greater flexibility in inputs. Video samples are available on the ttfamily project page, showcasing its application effects across different scenarios.
OmniHuman Application Scenarios
Virtual Anchor: On livestreaming platforms, OmniHuman can generate virtual anchors to provide real-time interaction and entertainment content.
Education and Training: By generating virtual teachers, OmniHuman can deliver personalized learning experiences in online education.
Game Development: In games, virtual characters can be generated through OmniHuman to enhance immersion and interactivity.
OmniHuman Project Address: https://omnihuman-lab.github.io









