
 Script Planner Assistant▸
 AI Apps
 AI News
Missionl AI Releases Mistral Small 3: Just 24B Parameters, but Performance Rivals 70B-Class Models
小编 ·

Missionl AI Releases Mistral Small 3: Just 24B Parameters, but Performance Rivals 70B-Class Models
Mistral ai released Mistral Small 3 on January 30, 2025, a latency-optimized 24B parameter model designed to deliver efficient performance. The model is released under the Apache 2.0 license, allowing users to freely use and modify it.
Key Features of Mistral Small 3:
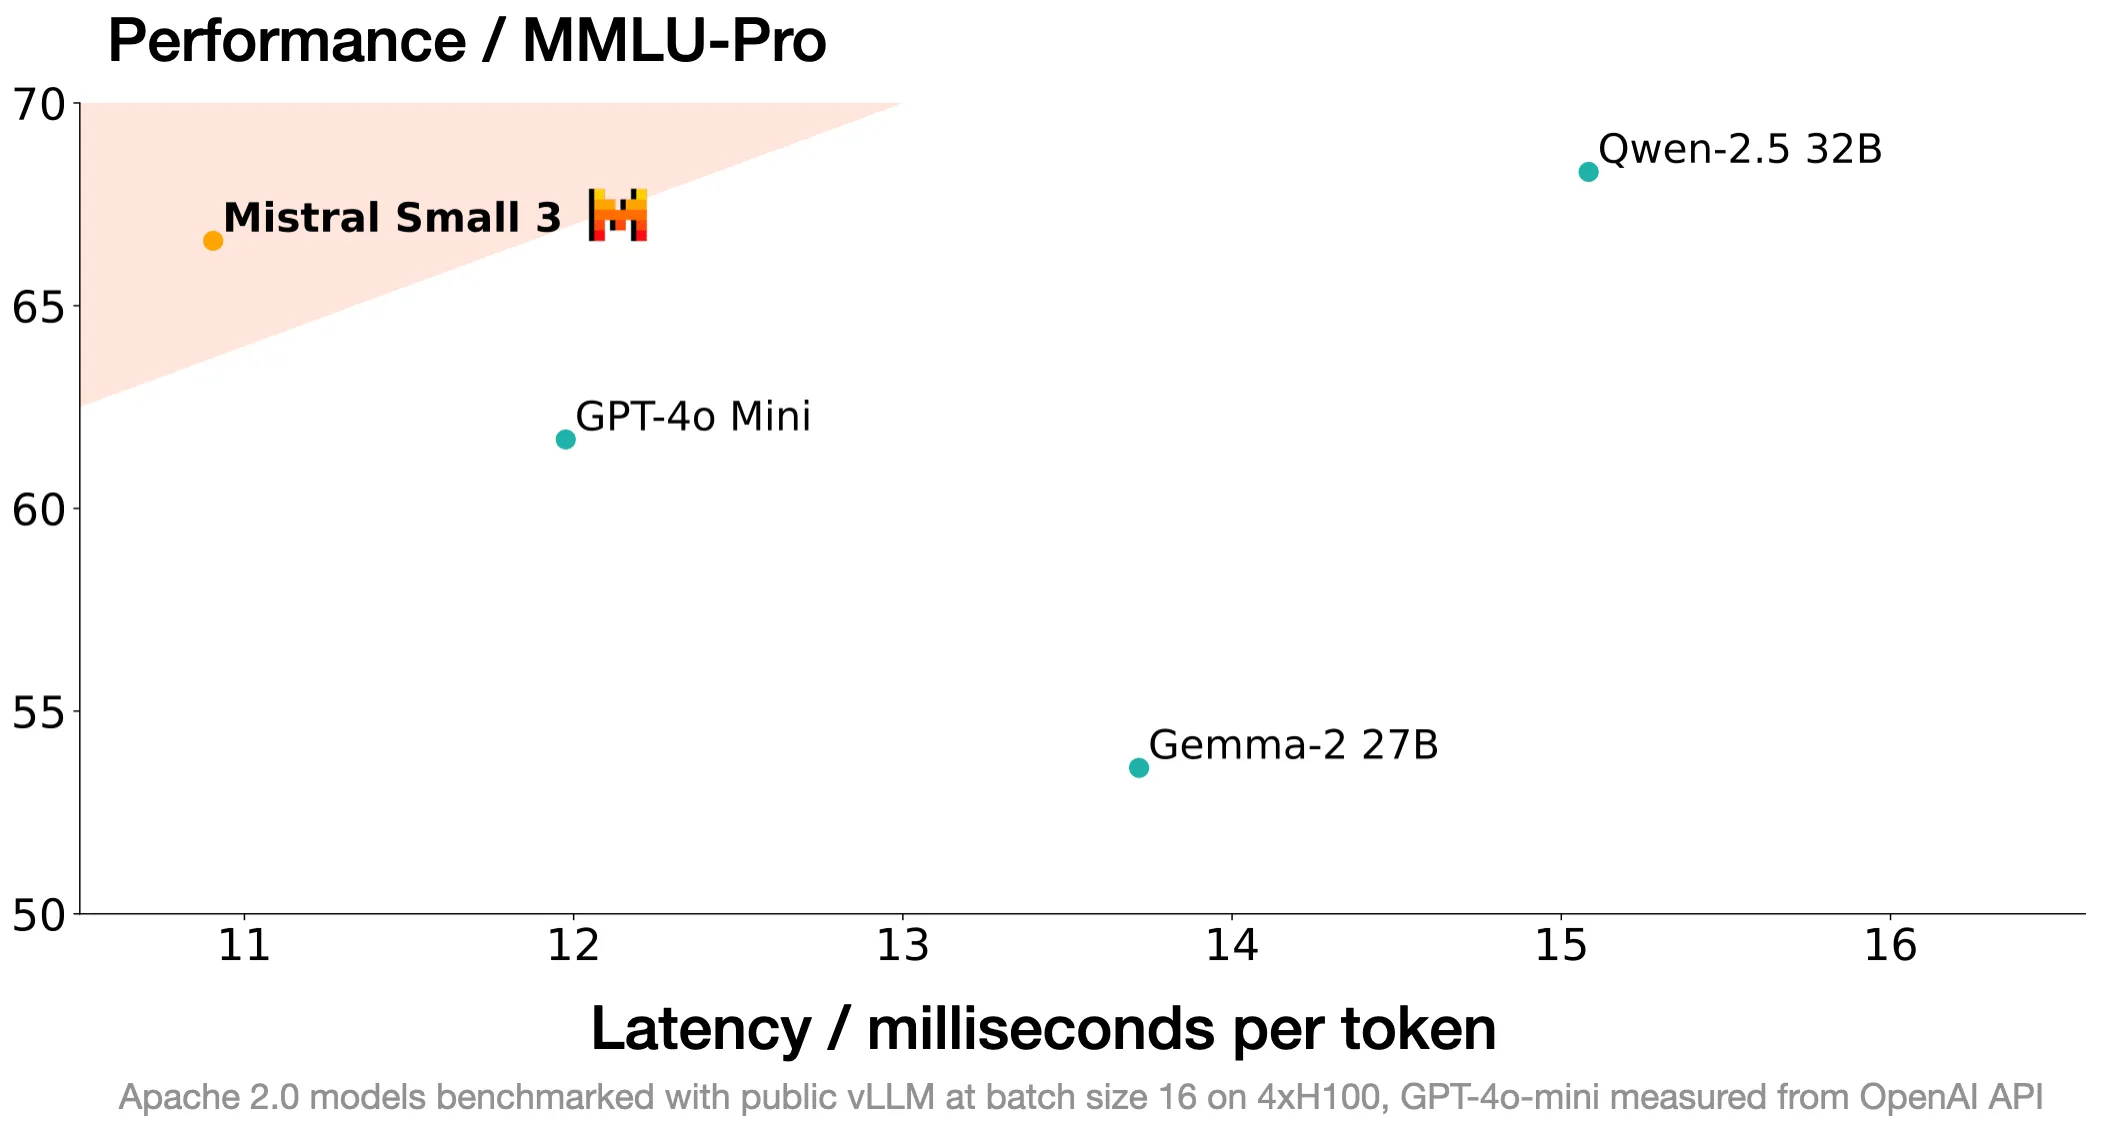
High Performance and Scale: Despite having only 24B parameters, Mistral Small 3 delivers performance comparable to much larger models (such as Llama 3.3's 70B parameter model). This enables faster inference on the same hardware.
Latency Optimization: Mistral Small 3 is optimized for low-latency workloads, making it ideal for applications that require rapid responses.
Domain-Specific Fine-Tuning: Suitable for task-specific training in fields such as legal, medical, and technical support, improving accuracy on specialized knowledge.
Local Inference: Supports running locally on an RTX 4090 or a MacBook with 32GB RAM, making it suitable for individuals and enterprises handling sensitive or proprietary data.
Mistral Small 3 is specifically designed to meet the needs of most generative AI tasks, especially those that require strong language capabilities and instruction-following performance. The model achieves over 81% accuracy on the MMLU benchmark and runs at 150 tokens per second on the same hardware, demonstrating its efficiency advantages.
Additionally, Mistral Small 3 is designed for local deployment, particularly in scenarios involving sensitive or proprietary information. Users can run the model on a single RTX 4090 or a MacBook with 32GB RAM, further enhancing its accessibility and flexibility.
Mistral Small 3 is also partnering with multiple platforms, including Hugging Face, Ollama, and Kaggle, making it easier for developers to access and use the model.
Applications of Mistral Small 3
Mistral Small 3 is suitable for a wide range of applications, including natural language processing, conversational systems, and other tasks requiring efficient inference. It is designed to provide developers with a flexible and powerful tool to meet the needs of modern AI applications.
Conversational Assistants: Suitable for virtual assistants that require fast and accurate responses.
Function Calling: Capable of quickly executing functions in automated or agentic workflows.
Domain Experts: Can be fine-tuned to create high-precision expert models in specific domains.
Local Inference: Ideal for local inference involving sensitive or proprietary information.
Financial Services: Used for fraud detection.
Healthcare Industry: Used for patient triage and customer support.
Robotics/Automotive/Manufacturing: Performs command and control on-device.
Official introduction: https://mistral.ai/news/mistral-small-3/









