
 Script Planner Assistant▸
 AI Apps
 AI News
What Is LLM Distillation, and What's Behind the "Model Distillation" Accusation Against DeepSeek?
小编 ·

What Is LLM Distillation, and What's Behind the "Model Distillation" Accusation Against DeepSeek?
DeepSeek is an emerging artificial intelligence company that has recently attracted widespread attention due to allegations of using OpenAI's technology for model distillation. OpenAI claims that DeepSeek may have extracted knowledge from its models through distillation techniques, thereby developing competing products.
What is Distillation in Large Models?
Distillation in large models is a model compression technique aimed at transferring the knowledge of a large, complex model (called the teacher model) into a smaller, more efficient model (called the student model). This process involves training the student model to mimic the outputs of the teacher model, thereby reducing computational resource consumption while maintaining performance.
This concept was proposed by Hinton et al. in 2015 and is commonly used for model compression, accelerating inference, and reducing deployment costs, while retaining as much of the original model's performance as possible. Distillation techniques are widely applied in deep learning, especially in fields such as natural language processing and computer vision.
Below is a mind map from YouTuber "Jeff's Tech Perspective" (Jeff Li) to help you understand. Teacher Jeff Li explained it in great detail in his video "Episode 379: Distillation in Large Models and the Allegations Faced by DeepSeek" video.
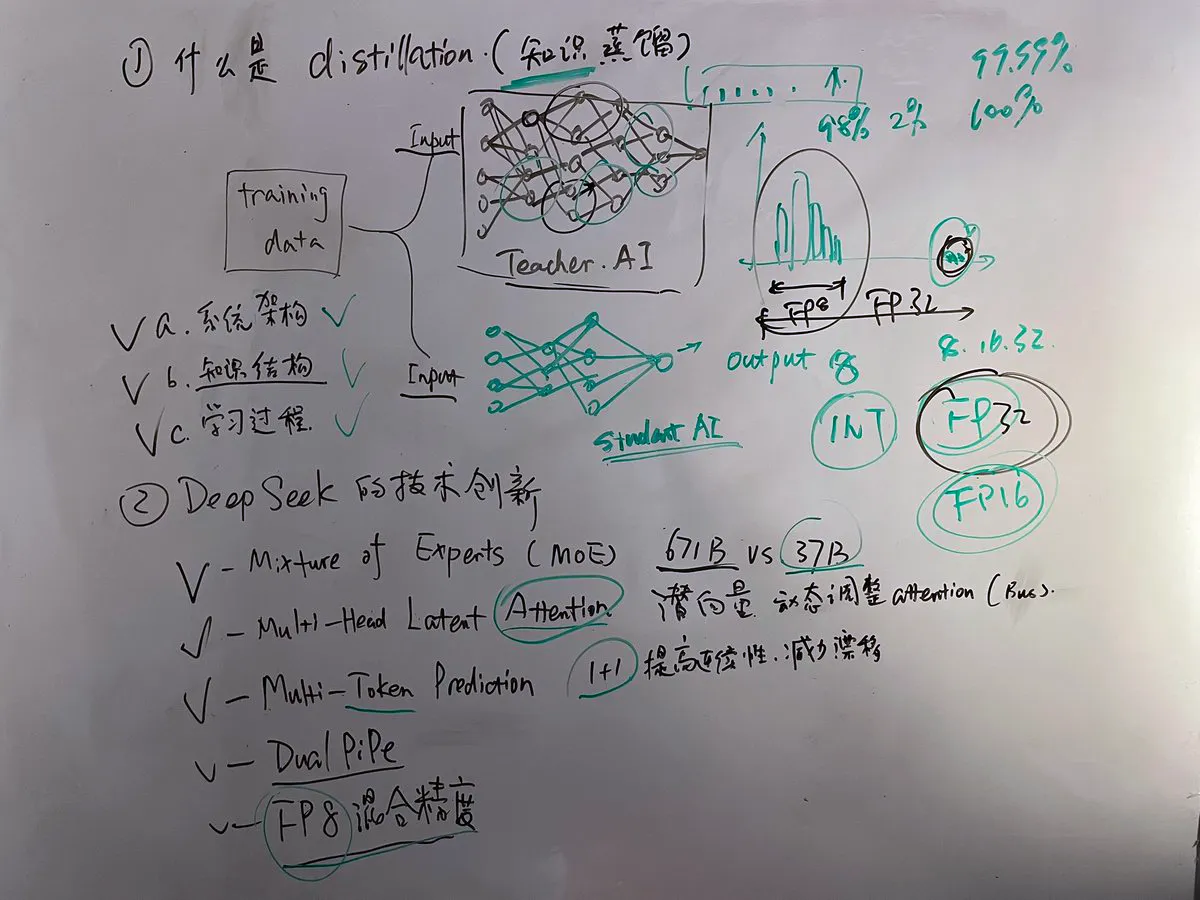
Implementation Methods of Distillation in Large Models:
Soft Labels: Use the probability distributions generated by the teacher model instead of hard labels for training.
Hidden Activations: Use the outputs from some intermediate layers of the teacher model as auxiliary signals for the student model.
Attention Weights: If sequence models are involved, relevant information about the attention mechanism can also be transferred
The "Model Distillation" Allegations Faced by DeepSeek
Background:
DeepSeek is a startup that provides its own large language model products.
DeepSeek's low-cost model development, open-source, and free strategies may threaten the market position of companies such as OpenAI and Anthropic, leading competitors to criticize it, arguing that DeepSeek improperly uses their technology and data.
Key Points:
OpenAI's Stance
Accuses DeepSeek of scraping and using unauthorized data to train its own models.
Its own issues: OpenAI itself has also been accused of illegally scraping data from the internet to train its models, especially copyrighted articles and works. Additionally, OpenAI has faced lawsuits from publishers such as The New York Times for similar behavior.
Anthropic's View
Downplays the severity: Anthropic believes that DeepSeek has not reached a level that truly threatens its products, stating that its technical level is only equivalent to a version from a few months ago.
Microsoft's Attitude
Microsoft has made the DeepSeek model available on its Azure AI and GitHub platforms, showing a form of support, which has also sparked discussions about conflicts of interest.
Specific Disputes over Model Distillation
Legality and Norms: Model distillation is a common technical practice, but there are strict rules and constraints in actual operation. Particularly regarding regulations on commercial use and technology sharing agreements, different companies have different interpretations and levels of enforcement.
How to define obtaining data in an "unauthorized manner"?
Is it allowed to use the output data of certain APIs to train new competing models?
Evidence and Supporting Materials: Currently, neither side has fully disclosed detailed evidence to support their claims, which adds to the complexity and uncertainty of the incident.
Industry Reaction and Public Opinion
Views on this matter vary both within and outside the community. Some see it as a manifestation of market competition; however, many voices are concerned about whether the ethical and legal considerations behind this matter have been fully respected.
The "model distillation" accusations faced by DeepSeek reflect the intense competitive landscape in the current AI industry and the challenges posed by legal gray areas surrounding data usage rights and the boundaries of technological innovation.









