
 Script Planner Assistant▸
 AI Apps
 AI News
Alibaba Officially Releases Open-Source LLM Qwen2.5-1M
小编 ·

Alibaba Officially Releases Open-Source LLM Qwen2.5-1M
Alibaba officially launched its open-source large model Qwen2.5-1M series on January 27, 2025. This marks the first time the Tongyi Qianwen team has extended the context length of an open-source model to 1 million tokens (equivalent to about 10 full-length novels or 30,000 lines of code), achieving a significant breakthrough in long-text processing performance.
I. Main Features of Qwen2.5-1M
Ultra-Long Context Support: The Qwen2.5-1M model supports context processing of up to 1 million tokens, which is equivalent to approximately 1 million English words or 1.5 million Chinese characters. This feature enables the model to handle long-form documents such as books, legal documents, and lengthy reports without cumbersome text segmentation.
Multiple Model Sizes: The released models include Qwen2.5-7B-Instruct-1M and Qwen2.5-14B-Instruct-1M, offering different parameter scales to meet the needs of various application scenarios.
Efficient Inference Framework: The Qwen team open-sourced a vLLM-based inference framework that integrates a sparse attention mechanism, boosting processing speed by 3 to 7 times when handling 1M token inputs. This efficiency enables developers to deploy and apply the model more rapidly.
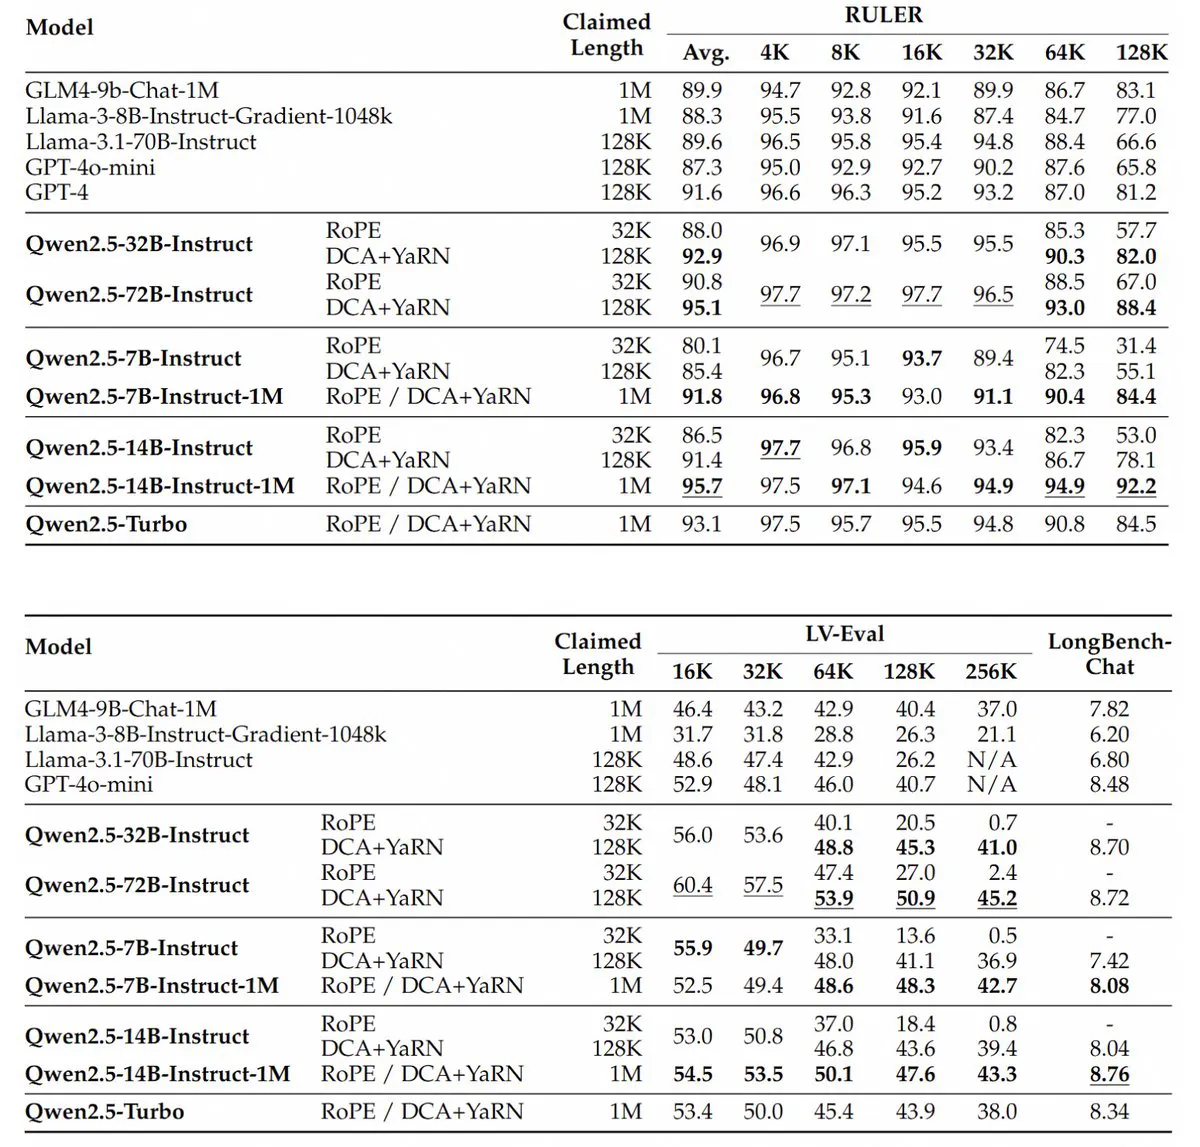
Performance Advantages: On long-text tasks, the Qwen2.5-1M model performs significantly better than the previous 128K version, particularly when handling tasks with lengths exceeding 64K, demonstrating stronger capabilities.
II. Model Features and Performance
Long Context Processing Capability
Million-Token Support: The Qwen2.5-1M series includes 7B and 14B versions, natively supporting a context length of 1M tokens. They can process long-form documents, code repositories, or complex multi-turn conversations without segmenting the input.
Precise Retrieval and Understanding: In the "Passkey Retrieval" task, the model can accurately extract hidden information from 1M token documents, with only the 7B version showing minor errors. In long-text understanding benchmarks such as RULER and LV-Eval, the 14B version consistently outperforms its own closed-source model Qwen2.5-Turbo and OpenAI's GPT-4o-mini.
Compatibility with Short-Text Tasks
The 7B and 14B models perform comparably to the 128K version on short-text tasks (such as Q&A and summarization), without sacrificing fundamental performance due to the enhanced long-context capability. For example, the 14B model performs close to GPT-4o-mini on short-text tasks, while offering 8 times the context length.
III. Technical Breakthroughs and Open-Source Framework
Progressive Training and Length Extrapolation
Staged Expansion: From pre-training to supervised fine-tuning, the context length is gradually expanded from 4K to 256K, followed by reinforcement learning to optimize short-text alignment capabilities56.
Dual Chunk Attention (DCA): An innovative positional encoding extrapolation technique is introduced, which extends the model's supported context length from 256K to 1M without additional training, solving the attention degradation issue of long-distance positional encoding.
Efficient Inference Optimization
Sparse Attention Mechanism: Based on the vLLM framework, sparse attention (MInference) is integrated, combined with chunked prefill and dynamic parallelism techniques, boosting inference speed for 1M token inputs by 3.2 to 6.7 times and significantly reducing memory usage (for example, activation memory for the 7B model is reduced by 96.7%).
Open-Source Framework Support: The inference framework and training technical report are fully open-sourced, allowing developers to quickly deploy the model, with FP8 quantization supported to reduce hardware requirements.
IV. Application Scenarios
Text Generation: The Qwen2.5-1M model can be used to generate long articles, reports, and stories, suitable for content creation, news writing, and other fields.
Information Retrieval: Thanks to its ultra-long context processing ability, the model can perform effective information retrieval within long texts, making it suitable for industries such as legal and healthcare that need to process large volumes of documents.
Dialogue Systems: The model can be used to build intelligent dialogue systems capable of understanding and generating complex conversational content, enhancing user experience.
Multimodal Applications: The design of the Qwen2.5-1M model enables it to be combined with other modalities (such as images and audio), extending its application scope to multimodal understanding and generation tasks.
The release of Qwen2.5-1M not only fills the gap for open-source models in the field of ultra-long context processing, but also provides developers with a high-performance, low-threshold tool choice through technological innovation and an open ecosystem. Its success may accelerate the global AI industry's exploration of long-text applications and promote the role of the open-source community in the AGI race.









