
 Script Planner Assistant▸
 AI Apps
 AI News
FunAudioLLM: Alibaba's Breakthrough in Voice AI
小编 ·

FunAudioLLM: Alibaba's Breakthrough in Voice AI
FunAudioLLM is a suite of speech processing models developed by Alibaba, designed to improve voice interaction between humans and large language models. It consists of two main models: SenseVoice and CosyVoice.
SenseVoice: A speech recognition model that can recognize speech in multiple languages, identify the speaker's emotions, and detect special events in audio (such as music, laughter, etc.). It can transcribe speech content quickly and accurately.
CosyVoice: A speech generation model that primarily generates natural and emotionally rich speech. It can mimic different speakers and even clone a person's voice with just a few seconds of audio samples.
Through the combination of SenseVoice and CosyVoice, FunAudioLLM provides comprehensive speech understanding and generation capabilities, making voice interaction between humans and large language models more natural and rich.
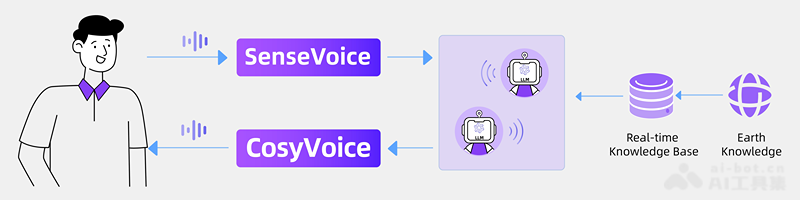
Main Features of SenseVoice and CosyVoice:
SenseVoice focuses on multilingual speech recognition, emotion recognition, and audio event detection, providing high-precision, low-latency speech processing capabilities. CosyVoice focuses on natural speech generation and control, supporting generation in multiple languages, timbres, and speaking styles, and enabling zero-shot learning and fine-grained speech control. The combination of the two enables FunAudioLLM to deliver excellent voice interaction experiences across a wide range of application scenarios.
Main Features of SenseVoice
1. Multilingual Speech Recognition
SenseVoice-Small: Supports five languages, including Chinese, English, Cantonese, Japanese, and Korean. It employs a non-autoregressive end-to-end architecture with extremely low recognition latency. It is 5 times faster than Whisper-small and 15 times faster than Whisper-large.
SenseVoice-Large: High-precision speech recognition, supporting more than 50 languages.
2. Emotion Recognition
Identifies emotions in speech, such as happiness, sadness, anger, etc., by detecting changes in pitch, rhythm, and intonation.
3. Audio Event Detection
Detects special events in speech, such as music, laughter, applause, etc., and predicts the start and end times of these events.
SenseVoice-Small can detect various human-computer interaction events, such as background music, applause, laughter, crying, coughing, sneezing, etc.
4. Language Identification
Capable of identifying the language used by the speaker to ensure the accuracy of speech recognition and contextual understanding.
5. Inverse Text Normalization (ITN)
Provides punctuated and formatted transcription results to enhance the readability and accuracy of the transcribed text.
Main Features of FunAudioLLM:
Multilingual Speech Recognition: Over 400,000 hours of training data, with recognition performance superior to the Whisper model.
Efficient Inference: The SenseVoice-Small model adopts a non-autoregressive end-to-end framework with extremely low inference latency. Processing 10 seconds of audio takes only 70 milliseconds, 15 times faster than Whisper-Large.
Emotion Recognition: Achieves state-of-the-art results among current emotion recognition models on multiple test datasets.
Event Detection: Supports detection of multiple common audio events.
Convenient Fine-Tuning: Provides convenient fine-tuning scripts and strategies, allowing users to easily address long-tail sample issues based on their business scenarios.
Service Deployment: Provides service deployment pipelines that support multiple concurrent requests, with client languages including Python, C++, HTML, Java, C#, etc.
Main Features of CosyVoice:
1. Speech Generation
Supports multilingual speech generation, including Chinese, English, Cantonese, Japanese, and Korean.
Capable of generating natural and emotionally rich speech, supporting different speaking styles and emotional expressions.
2. Diverse Speech Control
Timbre Control: Precisely controls the timbre of the generated speech to match the voice of a specific speaker.
Speaking Style Control: Controls the speaking style of the voice through text commands, such as emotion, speech rate, pitch, etc.
3. Zero-Shot Learning
Voice can be cloned with just a few seconds of audio samples, requiring no additional training data.
Supports cross-lingual voice cloning, allowing you to speak with the voice of one language while using another.
4. Fine-Grained Control of Paralinguistic Features
Supports inserting subtle vocal features such as laughter, breathing, and interjections to make generated speech more natural and vivid.
Text Command Control: Precisely controls the speaker's identity, emotion, and speaking style through text commands.
5. Multi-Role Dialogue
Capable of generating multi-character conversational speech, suitable for scenarios such as interactive podcasts and emotional chats.
Project Address:https://github.com/FunAudioLLM









